


An adaptive AI agent is an agentic system that selects its own tools, adapters, and reasoning paths at runtime based on real-time query analysis, instead of relying on a fixed pipeline. Unlike a static fine-tuned model, it improves continuously through a feedback-driven loop. Developers can build one today with semantic routing, LoRA-as-Tools, and multi-agent orchestration frameworks like LangGraph, then deploy it on real-time infrastructure such as VideoSDK's AI agent platform.
Static AI agents break the moment you take them outside the narrow slice of the world they were trained for. You fine-tune a model on legal documents, it answers legal questions well, and then someone asks it an HR policy question and it confidently hallucinates a vacation policy that does not exist. Multiply that across a dozen departments, a dozen products, and a dozen languages, and the one-model-per-domain approach collapses under its own weight.
That is the problem adaptive AI agents solve. An adaptive AI agent is an agentic system that dynamically chooses which tools, adapters, and reasoning strategies to apply for each incoming query. It parses intent in real time, routes the request to the right specialist capability, and folds the outcome back into its own decision-making so it gets better over time. Instead of being a single frozen brain, it behaves more like a dispatcher with a bench of experts, and the dispatcher learns from every call it handles.
By the end of this article, you will understand the core attributes that make an agent adaptive, the architecture that ties them together, and a practical step-by-step narrative for building one with LoRA adapters, semantic routing, and LangGraph-style orchestration, all explained without a single line of code.
What Makes an AI Agent Adaptive?
An adaptive AI agent is defined by three core attributes working together: dynamic tool selection, continuous learning, and context-aware routing. Dynamic tool selection means the agent evaluates each request and picks the most appropriate capability at runtime, rather than executing a fixed sequence of steps. Continuous learning means outcomes feed back into the system, so routing decisions and response quality improve with usage. Context-aware routing means the agent considers conversation history, user profile, and domain signals when deciding where a query should go.
Contrast this with a static fine-tuned model. A fine-tuned model encodes one domain's knowledge into its weights at training time. It cannot add a new specialty without a full retraining cycle, cannot recognize when a query falls outside its competence, and degrades silently as the world changes around it. Parameter-efficient fine-tuning techniques like LoRA reduce the cost of specialization, but a single adapter is still a static artifact.
The adaptive approach inverts the model. Instead of one model that knows everything, you have a routing brain that knows nothing except how to match intent to expertise, plus a registry of interchangeable specialists. Adding a new domain becomes a registration operation, not a retraining project. That is what makes adaptive agents genuinely scalable for production AI agent deployment.
Semantic Routing as the Brain
Semantic routing is the mechanism by which the base LLM parses a user's intent and selects the right tool or adapter for the job. Instead of keyword matching, the router embeds the incoming query, compares it against descriptions of available capabilities, and scores which specialist best fits. This is real-time query analysis in action: the router reads "my laptop keeps dropping the VPN after the latest patch" and recognizes it as an IT troubleshooting query, not a legal one, and dispatches accordingly. The router itself stays lightweight, which keeps routing latency low even as the tool registry grows.
LoRA-as-Tools: Domain-Specific Adapters
LoRA, or Low-Rank Adaptation, is a parameter-efficient fine-tuning technique that trains small, low-rank weight updates on top of a frozen base model instead of modifying all of its parameters. Because an adapter might be only a few hundred megabytes while the base model weighs tens of gigabytes, you can train and store many of them cheaply.
The LoRA-as-Tools concept treats each of these adapters as a callable tool in the agent's registry. A legal-domain adapter, an HR-domain adapter, and an IT-support adapter all sit alongside conventional tools like search or calculators. When the semantic router identifies a legal question, it loads or invokes the legal adapter, effectively swapping the agent's expertise for that one interaction. Multiple adapters become interchangeable instruments the router can pick up and put down at will, which is what turns a static model into a tool-augmented LLM with genuinely elastic expertise.
Architecture of an Adaptive AI Agent
Every production-ready adaptive agent, regardless of vendor or framework, converges on the same five components: a Query Analyzer, a Router, a Tool Registry, an Execution Engine, and a Feedback Loop. The Query Analyzer ingests the raw request, extracts intent, entities, and context, and produces a normalized representation. The Router compares that representation against the registered capabilities and selects the best match. The Tool Registry holds the catalog of LoRA adapters, external tools, and sub-agents, each with a description the router can reason over. The Execution Engine runs the selected capability, assembles the response, and records telemetry. The Feedback Loop closes the cycle by logging outcomes and feeding them back into routing decisions and adapter training.
The data flow is straightforward: query in, analysis, routing decision, execution, response out, and a telemetry record that improves the next decision. The following diagram shows how these components connect.
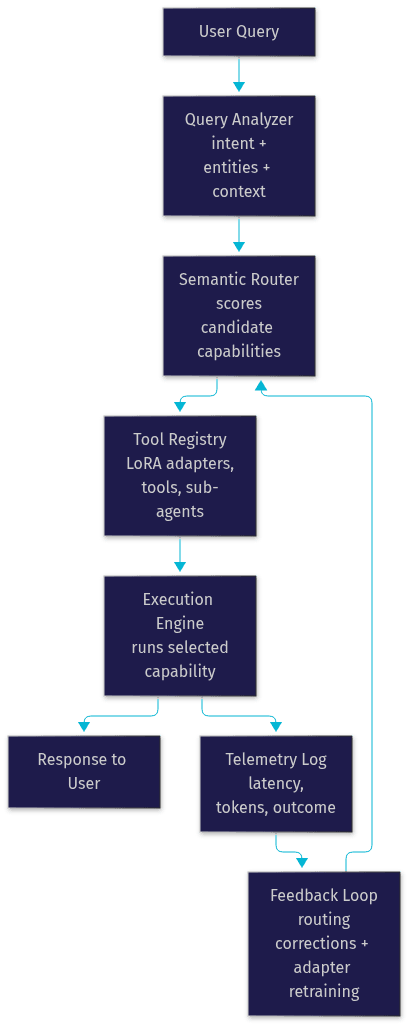
Two properties of this architecture matter most in practice. First, routing is separated from expertise, so each can evolve independently. Second, every decision is logged, which is what makes the continuous adaptation loop possible at all.
Multi-Agent Orchestration with LangGraph
A LangGraph workflow provides the orchestration layer that binds these components into a coherent agentic system. LangGraph models agent logic as a directed graph where nodes represent steps like analysis, routing, and execution, and edges represent the flow of state between them. This graph structure separates the routing brain from the specialist nodes, which means you can add a new domain expert by attaching a node, without touching the rest of the system. For AI agent scalability, that separation is the difference between a system that grows linearly and one that grows combinatorially. It also makes multi-agent orchestration natural: a supervisor node can delegate to specialist sub-agents, each backed by its own LoRA adapter, and merge their outputs.
Continuous Improvement via the MAPE Loop
The MAPE control loop, borrowed from autonomic computing, stands for Monitor, Analyze, Plan, and Execute. Applied to adaptive agents, Monitor means capturing every routing decision, response, and user reaction as telemetry. Analyze means detecting patterns such as routing errors, where a query was sent to the wrong adapter and the user had to rephrase or escalate. Plan means deciding on a correction, such as updating the router's capability descriptions or scheduling a retraining pass on a LoRA adapter with the misrouted examples. Execute means applying that correction and returning to monitoring.
Consider a concrete scenario. An enterprise assistant routes a question about contractor leave policy to the legal adapter instead of the HR adapter. The user marks the answer as unhelpful. The Monitor stage logs the mismatch. The Analyze stage compares the query embedding against both adapters' descriptions and finds the overlap that caused the confusion. The Plan stage rewrites the HR adapter's description to explicitly claim contractor-leave queries. The Execute stage deploys the updated description. The next similar query routes correctly. That is feedback-driven improvement in its simplest form, and it is the knowledge flywheel that keeps an adaptive agent from decaying.
Building an Adaptive AI Agent: Step-by-Step Narrative
The practical workflow for building an adaptive AI agent follows six phases, none of which require writing a single line of code to understand.
1. Define your domains. Start by inventorying the distinct areas of expertise your agent must cover, such as legal, HR, IT support, and product troubleshooting. For each domain, gather representative queries and gold-standard answers. These become both your adapter training data and your routing test set. Skipping this step is the most common cause of blurry routing later.
2. Create your LoRA adapters. For each domain, run parameter-efficient fine-tuning on your frozen base model using the domain's training data. Each adapter should be small, focused, and versioned independently. Validate each adapter in isolation before registering it, because a weak specialist poisons routing scores for everyone.
3. Register your tools. Add each adapter, along with any conventional tools like search or retrieval, to the tool registry with a clear, non-overlapping description. These descriptions are what the semantic router actually reads, so invest real effort in them. Overlapping descriptions are the number one source of routing errors.
4. Configure routing logic. Set up the semantic router to embed incoming queries, score them against registry descriptions, and dispatch to the winner, with a confidence threshold that falls back to a generalist path when no specialist scores high enough. That fallback is your safety net against nonsense queries.
5. Wire the orchestration graph. Compose the analyzer, router, registry, and execution engine as nodes in a LangGraph-style workflow, with state flowing along the edges and telemetry captured at every hop.
6. Deploy and monitor. Ship the agent behind your normal serving infrastructure, instrument the MAPE loop from day one, and review routing accuracy weekly.
Common pitfalls deserve their own mention. Token limits bite when the router tries to stuff too many tool descriptions into a single context window; keep descriptions terse. Adapter overload bites when you register dozens of low-quality adapters that dilute routing signal; prefer fewer, sharper specialists. Latency spikes bite when adapter loading happens on the hot path; pre-warm your most-used adapters. And never let the feedback loop run unattended, because automated retraining on noisy feedback degrades the agent faster than no learning at all.
What Most Tutorials Skip
Most tutorials stop at "it works on a demo." What they skip is production reality: routing accuracy degrades as the registry grows, so you need a regression test set of past queries that must keep routing correctly after every change. They also skip the human review queue. A small percentage of feedback should always route to a person before it becomes training data, because users mark good answers as bad for reasons that have nothing to do with correctness. Finally, they skip graceful degradation: when the router's confidence is low, the agent should say so and fall back to a generalist response rather than confidently guessing.
Real-World Use Cases
Three deployment patterns illustrate where adaptive agents shine.
Enterprise knowledge assistant. A single assistant serves legal, HR, and IT questions across a whole company. Each domain has its own LoRA adapter registered as a tool. An employee asks about maternity leave, the router selects the HR adapter; the next question about a vendor contract clause routes to legal. One interface, many specialists, and a feedback loop that keeps routing sharp as policies change.
Customer-support bot. A company with multiple hardware products registers a product-specific troubleshooting adapter for each product line. The router reads the customer's symptom description plus the product mentioned and selects the right adapter. When a new product launches, support coverage is a registration and a fine-tuning pass, not a rebuild.
Research assistant. A scientific research assistant holds adapters for distinct fields such as genomics, materials science, and climate modeling. The semantic router selects the appropriate domain adapter based on the terminology in the query, so a question about protein folding and a question about perovskite efficiency each reach a specialist that speaks the field's language.
Evaluating and Monitoring Adaptive Agents
Four metrics define the health of an adaptive agent in production. Routing accuracy measures how often queries reach the correct specialist, and it is the single most important number to track. Latency, measured end to end and at the routing stage specifically, tells you whether adapter loading or registry size is hurting responsiveness. Token usage per interaction exposes cost and reveals when descriptions are bloated. User satisfaction, captured through explicit feedback and escalation rates, is the ground truth that validates the other three.
Instrumentation should log every routing decision with the query, the selected capability, the confidence score, and the outcome. Visualization of the feedback loop, such as a dashboard showing misroutes clustered by domain pair, turns raw telemetry into actionable corrections. Teams deploying voice-based adaptive agents can pair this telemetry with session analytics from real-time infrastructure, and VideoSDK's AI agent observability tooling provides exactly this kind of decision logging for agents running in live rooms.
Future Directions
Three trends point at where adaptive agents go next. Elastic memory will let agents grow and shrink their working context dynamically, loading only the memories relevant to the current interaction. Self-evolving cognition will push the MAPE loop deeper, with agents proposing and validating their own adapter updates under human approval gates. Cross-agent collaboration will let multiple adaptive agents negotiate expertise, routing queries among themselves rather than relying on a single central router. Each of these builds on the same foundation described in this article, which is why getting routing, adapters, and feedback right today pays compound interest tomorrow.
Definitions Glossary
Adaptive AI Agent: An agentic system that selects tools, adapters, and reasoning paths at runtime based on real-time query analysis, and improves continuously through feedback. It contrasts with static fine-tuned models that cannot change behavior after deployment.
Semantic Routing: The mechanism by which a base LLM parses a query's intent and scores it against registered capabilities to pick the best specialist. It replaces keyword matching with embedding-based, context-aware dispatch.
LoRA Adapter: A small, low-rank weight update trained on top of a frozen base model using parameter-efficient fine-tuning. In the LoRA-as-Tools pattern, each adapter is registered as a callable, domain-specific tool.
MAPE Loop: The Monitor, Analyze, Plan, Execute control cycle applied to agents. It captures telemetry, detects routing errors, plans corrections, and applies them to keep the agent improving in production.
Tool Registry: The catalog of LoRA adapters, external tools, and sub-agents available to an adaptive agent, each annotated with descriptions the semantic router reasons over when making dispatch decisions.
Key Takeaways
- An adaptive AI agent combines dynamic tool selection, continuous learning, and context-aware routing to handle multiple domains without one-model-per-domain retraining.
- LoRA-as-Tools turns cheap, parameter-efficient adapters into interchangeable specialists that a semantic router can invoke on demand.
- A five-component architecture of Query Analyzer, Router, Tool Registry, Execution Engine, and Feedback Loop is the consensus design for production-ready adaptive agents.
- The MAPE loop is what keeps an adaptive agent from decaying, converting logged misroutes into routing and adapter corrections.
- Developers building voice-based adaptive agents can deploy them on real-time infrastructure like VideoSDK's AI agent platform, which supports Python-based agent workers with built-in observability.
Conclusion
Adaptive AI agents replace the fragile one-model-per-domain pattern with a routing brain, a registry of LoRA specialists, and a feedback loop that never stops learning. The pieces are mature in 2026: parameter-efficient fine-tuning makes specialists cheap, LangGraph-style orchestration makes composition manageable, and the MAPE loop makes improvement systematic. Start small: pick two domains, build two adapters, wire a router, and instrument every decision from day one. If you want to take your adaptive agent into live voice interactions, explore VideoSDK's AI agent documentation and the open-source agent samples on VideoSDK's GitHub. What are you building with adaptive AI agents? Drop a comment, I'd love to hear which domains you're routing between.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ