


An LLM-powered voice agent works by chaining speech-to-text (STT), a large language model for reasoning, and text-to-speech (TTS) into a single real-time pipeline, with voice activity detection (VAD) governing turn-taking. VideoSDK's open-source AI Agent SDK connects these components to real-time rooms, letting you deploy voice agents on web, mobile, or phone lines. This guide walks through the full architecture, from prompt design to production deployment.
Building a voice agent used to mean writing a decision tree. You mapped every phrase a caller might say, wrote a branch for each one, and prayed nobody went off-script. Large language models changed that equation completely. Instead of enumerating intents, you describe the job in natural language and let the model reason about what the caller actually wants.
That flexibility comes with new engineering problems. Voice is unforgiving about latency: if your agent takes four seconds to respond, the conversation feels broken. Every millisecond between the caller finishing a sentence and the agent speaking back is a design decision you own. By the end of this guide, you will understand the complete architecture of an LLM voice agent, how to keep it fast, and how to ship it to production.
How to Use LLMs for Voice Agents: An End-to-End Overview
A voice agent is a software system that holds a spoken conversation with a human. It listens to audio, understands what was said, decides what to do, and speaks a response. The LLM sits at the center of that loop as the reasoning engine, while surrounding components handle the audio in and audio out.
The reason LLMs matter here is generalization. A rule-based IVR system fails the moment a caller phrases something unexpectedly. An LLM handles paraphrase, context, and multi-step requests naturally, and it can call external tools, such as looking up an order or booking a slot, without a hand-coded state machine for every scenario.
What Is a Voice Agent and Why LLMs Matter
Voice agents evolved from touch-tone IVR menus, through keyword-spotting assistants, to today's LLM-driven systems. The older generations required explicit scripting: every path a conversation could take had to be authored in advance. LLM-powered voice assistants invert that. You specify the agent's role, tone, and available actions in a system prompt, and the model composes responses dynamically. That shift enables natural language understanding, graceful recovery from misunderstandings, and dynamic tool calling, capabilities that turn a brittle menu into something closer to a competent human operator.
Core Components of a Voice Agent
Every real-time voice agent architecture shares five components. First, speech-to-text converts the incoming audio stream into text, ideally with streaming transcription so partial results arrive while the caller is still talking. Second, the LLM reasons over the transcript, the conversation history, and its instructions to decide the next action. Third, text-to-speech renders the model's response as natural-sounding audio. Fourth, voice activity detection determines when the caller has actually finished speaking and when they have interrupted the agent, a behavior known as barge-in. Fifth, conversation state management tracks history, user data, and session context across turns. Get any one of these wrong and the whole experience degrades, no matter how good the LLM is.
Setting Up the Development Environment
Before writing any pipeline logic, make three decisions: your language runtime, your model providers, and your hosting model. Most voice agent tooling in 2026 is Python-first, with Node.js as a solid alternative for JavaScript teams.
Start by installing your language runtime and package manager. Then obtain API keys for the services you plan to use: an STT provider such as Deepgram or OpenAI Whisper, an LLM provider such as OpenAI or Anthropic Claude, and a TTS provider such as ElevenLabs or Cartesia. Store keys in environment variables on your machine, never in source files. Finally, choose a transport layer for real-time audio. If you are building on VideoSDK, the AI Agent SDK handles the room connection, so your agent process joins a live session and streams audio directly.
Choosing Between Cloud Services and an Open-Source Stack
Cloud voice APIs (OpenAI, Deepgram, ElevenLabs) offer the lowest setup friction and the best raw quality, at per-usage cost. An open-source voice AI stack (Whisper for STT, Ollama or vLLM for local LLM inference, Piper or Kokoro for TTS) eliminates per-minute costs and keeps data on your infrastructure, at the price of more ops work and typically higher latency unless you tune carefully. A pragmatic middle path: cloud STT and TTS for quality, with the option to self-host the LLM when data privacy demands it.
Installing Required Packages
Install the SDK packages for your chosen providers through your language's package manager, whether that is pip for Python or npm for Node. Pin versions deliberately rather than accepting the latest release blindly, because streaming audio APIs change frequently. Check each provider's release notes before upgrading, and keep your agent's dependency list minimal: every extra package in the hot path is another thing that can add latency or break silently.
Building the Voice Pipeline Architecture
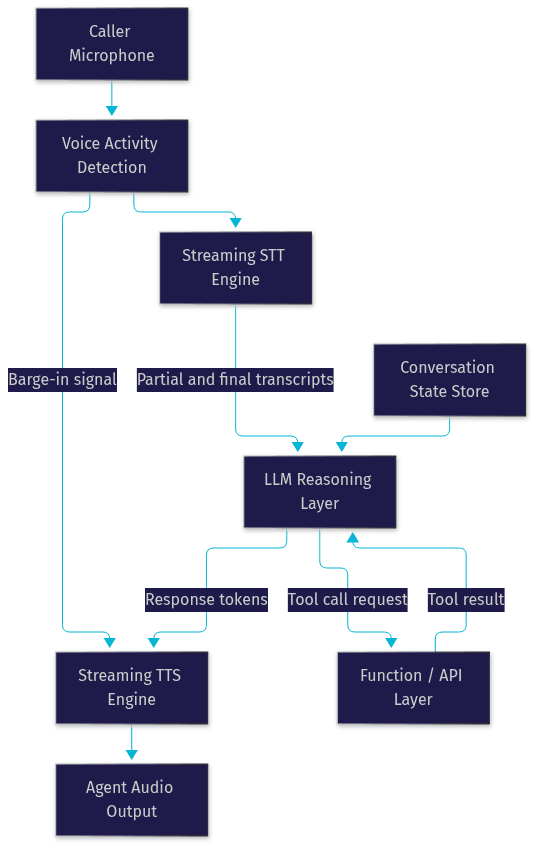
The pipeline is the heart of the system. Audio flows from the caller's microphone into a streaming STT engine, partial transcripts accumulate until VAD detects the caller has finished, the completed utterance goes to the LLM along with conversation history, the LLM's response streams into TTS, and synthesized audio plays back to the caller. If the LLM decides to call a tool, the pipeline pauses speech, executes the tool, feeds the result back to the model, and continues.
The critical design principle is streaming everywhere. Do not wait for a complete transcript before starting inference, and do not wait for a complete LLM response before starting TTS. Every stage should consume input incrementally and emit output incrementally. This is how well-engineered agents reach sub-second response times.
Detailed Walkthrough of Each Stage
STT produces two kinds of output: interim hypotheses while the caller speaks, and a final transcript once the utterance ends. Use interim results to prime the LLM (some stacks let the model start reasoning on partial text) and the final transcript as the authoritative input. The LLM then processes the utterance against its system prompt and history. If it emits a tool call, your orchestration layer executes that call, returns the result, and lets the model compose the spoken answer. Finally, TTS converts the response to audio, ideally sentence by sentence so the first words reach the caller while the rest is still generating. VideoSDK's agent pipeline handles this chaining natively, including turn detection and TTS caching, so you configure providers rather than wiring the loop yourself.
Prompt Engineering for Voice-Optimized LLMs
Voice prompts differ from chat prompts in one crucial way: the output is spoken aloud. Long, structured, markdown-heavy responses that read fine on screen sound terrible when spoken. Instruct the model to answer in one to three short sentences by default, to avoid lists and headings, and to spell out numbers, dates, and currency in speakable form.
Set explicit turn-taking rules in the system prompt. Tell the agent to ask one question at a time, to confirm critical data like names and addresses by repeating them back, and to never fill silence with filler phrases. For barge-in, instruct the model that the caller may interrupt, so when a new utterance arrives mid-response, it should abandon the old answer and respond to the new input rather than finishing its previous thought. Finally, define a fallback behavior for when the model does not understand: a brief apology and a re-ask, not a long clarification paragraph.
Managing Conversation History and Context
The LLM only knows what you send it, so conversation history management is your responsibility. Seed each session with a system message defining the agent's role, tone, and available tools. Then append each turn as it happens: caller transcript, agent response, tool calls and results.
History grows fast, and long contexts cost latency and money. Prune aggressively: keep the system prompt and the last N turns verbatim, and compress older turns into a short summary. For agents that need durable user knowledge, such as a caller's account details across sessions, use a memory layer or retrieval rather than stuffing everything into the context window. VideoSDK's agent framework supports both memory and RAG integrations for exactly this pattern.
Implementing Barge-In and Voice Activity Detection
Barge-in handling is what separates a natural voice agent from a frustrating one. When the caller starts speaking while the agent is talking, the agent must stop its TTS playback immediately, discard the rest of the planned response, and listen.
VAD techniques range from simple energy thresholds to neural classifiers that distinguish speech from background noise, coughs, and music. Modern STT endpoints often include endpointing, which detects end-of-utterance from silence duration and prosody. The key engineering decision is how aggressively you cut in: too eager and the agent interrupts the caller's natural pauses, too slow and every exchange feels sluggish. Tune the end-of-speech silence threshold to your audience's speaking style, and make TTS interruption immediate rather than queued, so the caller hears silence the instant they begin speaking.
Adding Tool Calls and Function Calling
LLM tool calling is what turns a conversational agent into a useful one. You describe each tool to the model with a name, a plain-language description, and the parameters it needs. When the model decides it needs a tool, it emits a structured request instead of, or alongside, a text response.
Your orchestration layer then executes the call. For example, an order lookup tool queries your database and returns the shipment status; a calendar booking tool checks availability and reserves a slot. The result feeds back into the LLM's context, and the model composes a spoken answer from it. Two practices matter here: validate tool parameters before executing anything, and give the model a way to gracefully report failures, such as telling the caller the lookup failed and offering to try again, rather than hallucinating a result. For deterministic multi-step flows, like loan applications or payment collection where every step must happen in order, VideoSDK's Conversational Graph lets you control branching with explicit rules while the LLM handles only the natural language.
Deploying to Production
Localhost and production are different worlds for voice agents. In production you need containerization for reproducible deploys, horizontal scaling for concurrent sessions, and monitoring on the metrics that actually matter: end-to-end response latency, STT word error rate, tool call success rate, and session drop rate.
Security and privacy come first. Keep every API key server-side, never in client code. If your agent handles personal data, which voice conversations almost always do, check your providers' data retention policies and consider self-hosting the LLM for regulated workloads. For phone-based agents, telephony integration with LLMs runs through SIP: VideoSDK's telephony layer bridges SIP trunks from providers like Twilio or Telnyx into your agent's room, so the same agent serves web users and PSTN callers.
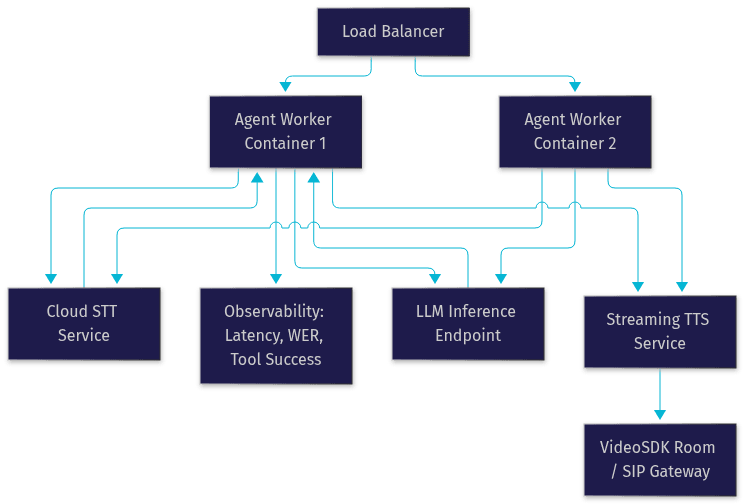
Each agent worker manages one or more live sessions, and the load balancer routes new sessions to healthy workers. Observability feeds back into tuning: if your p95 response latency creeps up, the dashboard tells you whether the bottleneck is STT, the LLM, or TTS.
Testing, Debugging, and Performance Tuning
Test voice agents end to end, not component by component. Record real caller audio, including accents, background noise, and interruptions, and replay it against the pipeline. Benchmark latency at each stage separately so you know where the milliseconds go: time-to-first-transcript, time-to-first-LLM-token, and time-to-first-audio are the three numbers to watch.
Common issues have common causes. Audio clipping usually means your input gain or chunking is misconfigured. Transcript errors on names and numbers point to STT biasing, where you supply expected vocabulary to the recognizer. Long dead-air pauses usually mean you are waiting for the full LLM response before starting TTS, so switch to sentence-level streaming. And agents that talk over callers mean your VAD threshold is too conservative. Fix these in order of user impact: latency first, then turn-taking, then transcription accuracy.
Future Trends and Advanced Topics
Three shifts are worth tracking. Speech-to-speech models, which generate spoken audio directly from spoken input without a text intermediate, promise to cut pipeline latency dramatically, though control and tool calling remain harder. Multimodal agents combine voice with vision, letting a support caller show the agent their broken device over video. And edge-AI deployments are pushing STT and even small LLMs onto devices for offline and privacy-sensitive scenarios. VideoSDK's agent stack already supports vision and multi-modality within live rooms, so these capabilities are closer than they sound.
Definitions Glossary
Voice Activity Detection (VAD): A technique that determines when a speaker has started or stopped talking, used to trigger agent responses and detect barge-in interruptions.
Barge-in: The behavior where a caller interrupts the agent mid-response, requiring the pipeline to stop TTS playback immediately and process the new utterance.
Streaming STT: Speech-to-text that emits partial transcripts while the caller is still speaking, enabling the pipeline to begin reasoning before the utterance ends.
LLM Tool Calling: The mechanism by which a language model requests an external function or API, such as an order lookup, and incorporates the result into its response.
Agent Worker: The server-side process that runs a voice agent's session, managing the STT, LLM, and TTS chain inside a real-time room, as in VideoSDK's AI Agent SDK.
Conversational Graph: A deterministic, graph-based orchestration layer where developers define conversation flow explicitly while the LLM handles only natural language generation.
Key Takeaways
- An LLM voice agent chains streaming STT, LLM reasoning, and streaming TTS, with VAD governing turn-taking and barge-in.
- Latency is the defining engineering constraint: stream at every stage and measure time-to-first-audio, not total response time.
- Prompt for speech, not screen: short sentences, one question at a time, speakable numbers, and explicit barge-in rules.
- Tool calling turns a conversational agent into a useful one, but validate parameters and handle failures gracefully.
- VideoSDK's open-source AI Agent SDK, Conversational Graph, and SIP telephony integration let one agent serve web, mobile, and phone callers from a single deployment.
Conclusion
Learning how to use LLMs for voice agents is really about mastering one loop: listen, reason, act, speak, and repeat, fast enough that the conversation feels human. The LLM supplies the intelligence, but streaming STT, aggressive VAD tuning, sentence-level TTS, and disciplined context management are what make it usable. Start with the VideoSDK AI Agents documentation, grab the open-source agent samples on GitHub, and sign up free at app.videosdk.live/login to get your first agent talking. What are you building with LLM voice agents? Drop a comment, I'd love to hear what kind of use case you're working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ