


TTS latency is the total delay between sending text to a speech engine and hearing the first audible syllable, and you reduce it by attacking four layers: model inference time, audio chunking strategy, network transport, and caching. The two metrics that matter are time-to-first-audio (TTFA) and real-time factor (RTF). VideoSDK's AI agent pipeline pairs low-latency TTS providers with streaming audio delivery into real-time rooms, so optimizing TTFA directly improves how natural your voice agent feels. This guide walks through each latency source and the concrete techniques that fix it.
How to Reduce TTS Latency: An Overview
Latency is the difference between a voice experience that feels human and one that feels like a walkie-talkie. When a conversational AI agent takes 800 milliseconds to respond, users perceive it as attentive. Push that past two seconds and they start talking over it, abandoning the conversation, or assuming the system is broken.
Two metrics define TTS performance. Time-to-first-audio (TTFA) measures the gap between submitting text and hearing the first sound. It dominates perceived responsiveness, because once audio starts flowing, users stop counting. Real-time factor (RTF) measures how long the engine takes to synthesize a second of speech. An RTF below 1.0 means the engine generates audio faster than it plays, which is the threshold for true real-time streaming.
Reducing TTS latency is not a single optimization. It is a systems problem spanning the model you choose, how you compile and run it, how you chunk and buffer the audio, how you transport it, and how aggressively you cache. A team that fixes inference time but ships full-sentence audio buffers will still feel slow. A team that streams perfectly but routes through a distant endpoint loses hundreds of milliseconds to the network.
This guide breaks the problem into its component sources, then gives you a layered playbook: model selection, inference optimization, streaming strategy, network tuning, payload minimization, and caching. By the end you will have a prioritized checklist you can apply to any real-time TTS pipeline, whether you run an open model on your own GPUs or call a managed API.
Understanding the Sources of TTS Latency
Every millisecond of TTS delay comes from one of four places: the model computing audio, the text being prepared, the audio being shaped after generation, or the bytes traveling across the network. You cannot optimize what you have not measured, so start by attributing your current latency to these four buckets.
Model Inference Time
Model inference is usually the largest single contributor. Neural TTS models generate audio through autoregressive or diffusion-style decoding, producing samples in sequence rather than all at once. Larger models with more parameters produce richer, more natural prosody, but each decoding step costs time.
Hardware matters as much as architecture. The same model that runs at an RTF of 0.3 on a modern GPU can crawl at an RTF above 3 on a CPU-only server, which is unusable for real-time conversation. GPU acceleration, batch size, and memory bandwidth all shape the ceiling of what your inference layer can deliver.
Compilation adds a second dimension. Deep learning frameworks like PyTorch traditionally execute operations eagerly, re-planning the computation graph on every call. Compilation tools such as torch.compile analyze the graph once, fuse operations, and generate optimized kernels. CUDA graphs go further by capturing an entire GPU execution sequence and replaying it with near-zero launch overhead. For TTS, where the same decoding loop runs thousands of times per utterance, this removes per-step overhead that quietly accumulates into hundreds of milliseconds.
Text Pre-Processing and Normalization
Before the model sees your text, it gets normalized. Numbers become words, abbreviations expand, dates and currencies get verbalized, and SSML tags get parsed into internal instructions. Each of these steps runs on the request path.
For short prompts this is negligible. For long, punctuation-heavy, or number-dense input, normalization can add tens of milliseconds, and complex SSML parsing can add more. The fix is to keep pre-processing lean: strip optional steps you do not need, avoid deeply nested SSML when plain text works, and pre-normalize predictable content such as product names or scripted phrases before they ever reach the engine.
Audio Post-Processing and Chunking
Generated audio does not leave the engine as one continuous wave. It is sliced into chunks, and those chunks must be joined without audible clicks or gaps. Cross-fade techniques, such as applying a Hann window overlap between consecutive chunks, blend the tail of one chunk into the head of the next so the seam is inaudible.
This blending is necessary for quality but costs time. Format conversion adds more: if the model outputs high-sample-rate float audio and your transport layer wants compressed Opus, transcoding sits on the critical path. Every conversion, resample, and re-encode is latency you pay before the user hears anything.
Network and Transport Delays
The network is the most underestimated source. A round trip from a client in Singapore to an inference endpoint in Virginia adds 150 to 250 milliseconds before a single sample is synthesized. Protocol choice compounds this: opening a fresh connection per request pays handshake costs every time, while a persistent WebSocket or multiplexed HTTP/2 connection amortizes that cost to zero after the first request.
The diagram below shows the full path from text input to audible output, with the latency hotspots called out at each stage:
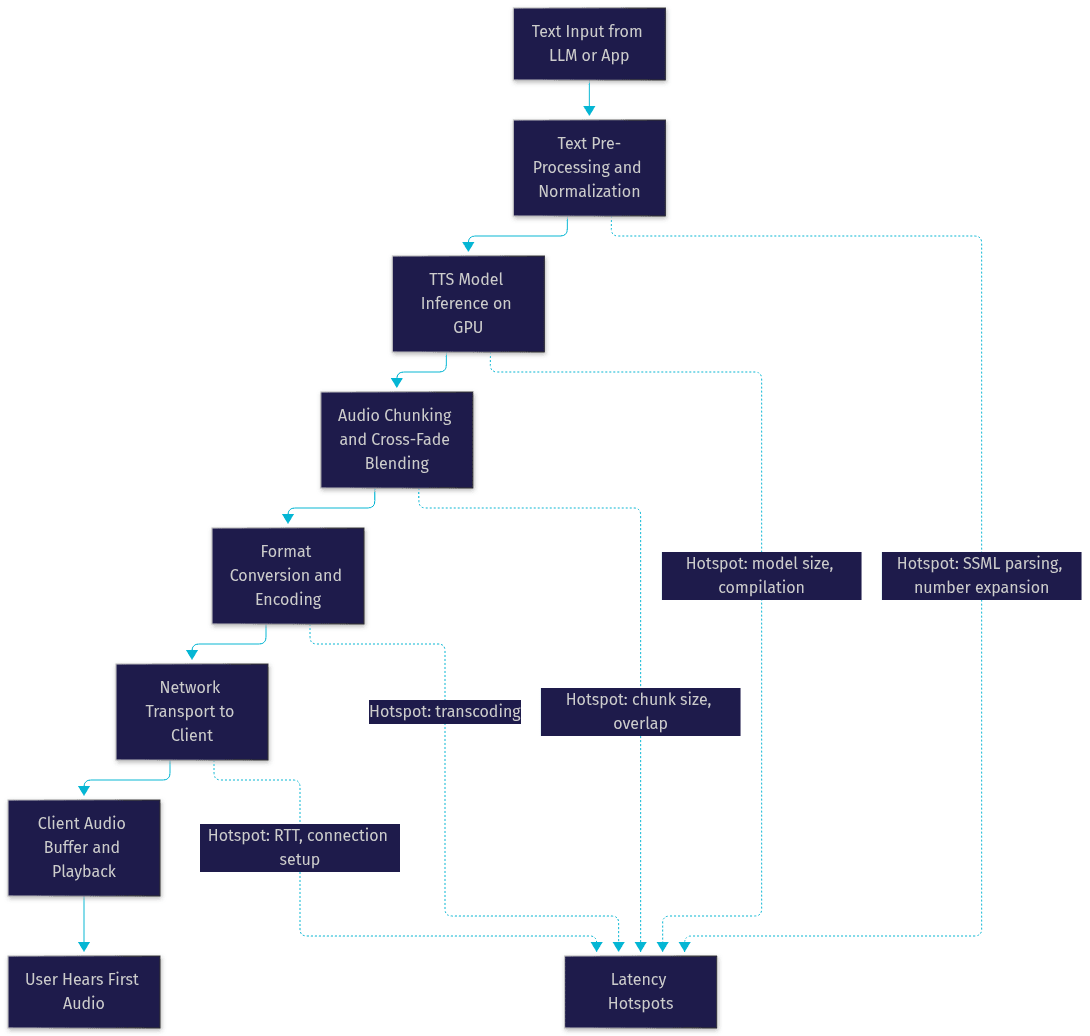
Measure each stage independently before optimizing. Most teams discover their bottleneck is not where they assumed it was.
Choosing the Right TTS Model for Speed
Model selection sets your latency floor before any optimization helps. A large premium model with a 600-millisecond TTFA cannot be tuned into a 150-millisecond TTFA; the architecture itself decides the range.
Streaming-optimized models are built for low TTFA. They emit audio after generating only the first few phonemes, trading a small amount of prosody planning for immediate output. Newer fast models released through 2025 and 2026, such as the streaming variants in the Simba and Mist families from Cartesia, are engineered specifically for sub-100-millisecond first-audio on modern GPUs. Higher-quality but slower alternatives, including large diffusion-based systems, deliver superior expressiveness for narration and long-form content where TTFA is irrelevant.
The decision matrix is straightforward:
| Scenario | Model type to choose | Why |
|---|---|---|
| Real-time voice agent, phone call | Streaming-optimized fast model | TTFA under 150ms keeps conversation natural |
| Live interpretation, live shopping host | Streaming-optimized fast model | Sub-second response expected by audience |
| Audiobook, article narration | Large high-quality model | TTFA irrelevant, quality dominates |
| Voice cloning with fixed persona | Mid-tier streaming model with cloning support | Balances identity fidelity and speed |
| Embedded or offline device | Small quantized model | Runs within local compute budget |
For conversational systems, pick the fastest model that clears your quality bar, not the highest-quality model that clears your speed bar. Users forgive slightly flatter prosody. They do not forgive dead air.
Optimizing Inference with Compilation and GPU Graphs
Once the model is chosen, inference optimization squeezes out the overhead the framework adds. The core idea is to stop paying planning costs on every request.
Compilation works by analyzing the model's computation once and generating fused, optimized execution kernels. In practical terms, you enable compilation mode, let the engine trace a few warm-up requests, and from then on every synthesis call runs the pre-optimized path. Teams applying torch.compile to TTS decoding loops commonly report meaningful reductions in per-utterance inference time, with the largest gains on smaller chunk sizes where per-step overhead was proportionally biggest.
CUDA graphs capture the exact sequence of GPU operations for a decoding step and replay them as a single unit. This eliminates kernel launch overhead, which is significant when a decoding step is short. The practical sequence for a developer is: warm up the model, capture the graph for your fixed chunk shape, then serve traffic through the captured graph. The trade-off is rigidity, because captured graphs assume fixed tensor shapes, so dynamic batch or chunk configurations need separate captures.
Two-phase streaming ties these together. The first phase uses aggressive, low-latency settings to get audio out the door fast. The second phase switches to stable, higher-throughput settings for the remainder of the utterance. This is covered in detail in the next section, because it is as much a streaming strategy as an inference strategy.
Reducing Latency Through Streaming Strategies
Streaming strategy is where the biggest perceived-latency wins usually live. Even a fast model feels slow if it buffers an entire sentence before playing. Conversely, a mediocre model with excellent streaming can feel instant.
Managed vs. Custom Buffering
Managed buffering means the TTS provider or SDK handles chunk assembly, cross-fades, and playback pacing for you. Custom buffering means your application receives raw chunks and manages the queue, overlap blending, and backpressure itself.
Managed buffering wins when you want correctness without audio-engineering effort. The provider has already solved the click-and-gap problems, and you get sane defaults. Its weakness is limited control: if the default buffer depth is too conservative for your use case, you cannot easily shave it down.
Custom buffering wins when you need to squeeze every millisecond, such as in competitive live-auction or trading-floor voice systems where you want the smallest safe playback buffer. Its cost is complexity: you own underflow handling, drift correction, and seam quality. A common pattern is to start managed, measure, and only go custom when profiling proves the managed buffer is your bottleneck.
Two-Phase Streaming
Two-phase streaming attacks TTFA directly. In the first phase, the engine uses aggressive settings: small first chunk, minimal lookahead, fast decode window. The goal is purely to get audible audio to the user as fast as possible, even if the first second of speech is generated less efficiently. Once the first chunks are delivered and the playback buffer has some runway, the engine switches to a second phase with larger chunks and more efficient decoding, because throughput now matters more than first-byte timing.
The timeline below shows how two-phase streaming compresses time-to-first-audio compared to a single conservative configuration:
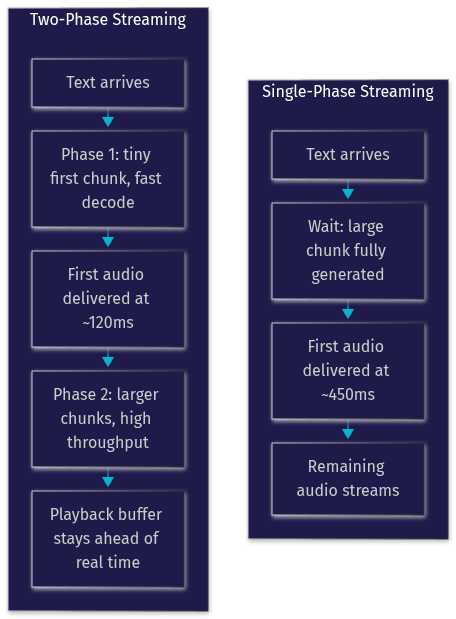
The audible result is that the agent starts speaking almost immediately and never stutters, because phase two refills the buffer faster than it drains.
Chunk Size and Overlap
Chunk size is the most direct TTFA lever. A smaller emit interval means the first chunk completes sooner, so audio starts playing sooner. The trade-off is overhead: more chunks means more blending seams and more per-chunk processing cost, so you shrink the first chunk, not every chunk.
The decode window, the amount of audio the model generates per internal step, interacts with this. A window that is too large delays the first chunk; a window that is too small hurts throughput and can cause buffer under-runs mid-utterance. The practical tuning loop is: set the smallest first-chunk size that produces clean audio, then grow the steady-state chunk size until the playback buffer consistently stays ahead of consumption.
Network-Level Optimizations
After inference and streaming, the network is the remaining variable, and it is often the cheapest to fix.
Regional endpoint selection matters most. Route synthesis requests to the endpoint geographically closest to your inference client, or better, to your end users. If you self-host, deploy TTS inference in the same region as your application servers and, ideally, near your users. Edge deployment for TTS, running smaller quantized models in regional points of presence, can cut round-trip time from hundreds of milliseconds to tens.
Connection reuse eliminates per-request handshake cost. A persistent WebSocket or an HTTP/2 connection with multiplexing means the first request pays the setup cost and every subsequent request rides an already-open channel. For a voice agent making many synthesis calls per conversation, this saves the repeated TCP and TLS handshake overhead on every turn.
Finally, co-locate pipeline stages. If your LLM, your TTS engine, and your media server live in three different regions, you pay inter-region hops on every response. Keeping the STT, LLM, and TTS stages of a voice agent pipeline in one region or one host, as VideoSDK's agent architecture does by running the full pipeline inside a single agent worker connected to a VideoSDK room, removes those hops entirely. You can explore this architecture in the VideoSDK AI agents documentation.
Audio Format and Payload Minimization
Every byte of audio payload adds transport time, and every format conversion adds processing time. Format choice is a small optimization that compounds.
For telephony integrations, ulaw at 8 kHz matches what the phone network actually carries, so you skip transcoding entirely. For web and mobile playback, Opus gives excellent quality at low bitrates, shrinking payloads over constrained connections. Raw PCM is the lowest-latency option when bandwidth is plentiful and the client can play it directly, because it needs no encode or decode step at all.
Trim sample rate and bit depth to what the use case supports. A phone call does not need 48 kHz stereo; synthesizing at 16 kHz mono halves the data volume and often speeds inference too, since the model generates fewer samples per second of speech. Match the synthesis format to the playback format end to end so nothing gets resampled on the critical path.
Caching and Reuse of Frequently Spoken Phrases
The fastest synthesis call is the one you never make. Voice agents repeat themselves constantly: greetings, confirmations, hold messages, error prompts, standard disclaimers. Synthesizing these every time wastes both latency and cost.
Build a cache keyed on the combination of text, voice, model, and audio format. Two identical requests with different voices must produce different cache entries, so the key needs all identity dimensions. Store the resulting audio chunks in fast storage close to your serving layer, and serve repeat hits directly from cache with near-zero TTFA.
The impact on perceived latency is significant. In production voice agents, a large share of turns contain at least one cached phrase, and those phrases play instantly while the model synthesizes only the novel content. Users experience a system that responds immediately, because the first thing they hear is usually the cached part of the response. Invalidate entries when you change models or voices, and monitor hit rates to decide which phrases are worth pre-warming at deploy time.
Monitoring, Benchmarking, and Continuous Improvement
Latency optimization decays. Model updates, traffic growth, and regional changes all shift your numbers, so measurement must be continuous, not a one-time exercise.
Track TTFA and RTF as first-class metrics with percentile breakdowns, because averages hide the tail experiences that frustrate users. A p50 TTFA of 150 milliseconds with a p99 of 900 milliseconds means one user in a hundred hears a sluggish agent. Alert on percentile thresholds, not averages.
Your monitoring checklist:
- Instrument TTFA and RTF per request, per region, and per model version
- Record the latency contribution of each pipeline stage separately
- Alert on p95 and p99 TTFA thresholds crossing your conversational budget
- A/B test configuration changes, such as chunk sizes or endpoints, against a stable baseline before rolling out
- Re-benchmark after every model or SDK version change, since defaults shift
- Log cache hit rates and correlate misses with latency spikes
Treat latency budgets like performance budgets in frontend engineering: explicit, enforced, and reviewed. A common target for conversational voice agents is keeping total response latency, including STT and LLM stages, under 500 to 800 milliseconds, which leaves TTS a TTFA budget of roughly 100 to 200 milliseconds.
Practical Checklist for Reducing TTS Latency
- Choose a streaming-optimized model sized to your quality bar, not above it
- Enable compilation and GPU graph capture to remove per-step inference overhead
- Use two-phase streaming: tiny first chunk, larger steady-state chunks
- Start with managed buffering; go custom only when profiling proves the need
- Route to the nearest regional endpoint and reuse persistent connections
- Co-locate STT, LLM, and TTS stages in one region or one worker
- Match audio format to playback, and trim sample rate and bit depth
- Cache frequent phrases keyed on text, voice, model, and format
- Monitor TTFA and RTF at p95 and p99, and A/B test every change
Definitions Glossary
TTFA (Time-to-First-Audio): The delay between submitting text to a TTS engine and the first audible sample reaching the user. It is the dominant metric for perceived responsiveness in real-time voice applications.
Real-Time Factor (RTF): The ratio of synthesis time to speech duration. An RTF below 1.0 means the engine generates audio faster than it plays, enabling true streaming playback.
Two-Phase Streaming: A TTS strategy that uses aggressive low-latency settings for the first audio chunk, then switches to higher-throughput settings for the rest of the utterance.
Cross-Fade Blending: The technique of overlapping and weighting the edges of consecutive audio chunks, often with a Hann window, so chunk seams are inaudible.
Agent Worker: In VideoSDK's architecture, the Python process that runs an AI agent's full pipeline, including STT, LLM, and TTS stages, inside a single VideoSDK room to eliminate inter-service network hops.
Key Takeaways
- TTS latency is a systems problem across four layers: model inference, text pre-processing, audio chunking, and network transport, and you must measure each before optimizing.
- TTFA is the metric users actually feel, and two-phase streaming with a tiny first chunk is the single most effective technique for improving it.
- Model selection sets your latency floor, so choose the fastest streaming-optimized model that clears your quality bar for conversational use cases.
- Compilation and CUDA graph capture remove per-step inference overhead that accumulates into hundreds of milliseconds across a decoding loop.
- Caching frequently spoken phrases delivers near-zero TTFA for the most common parts of a voice agent's responses.
- Co-locating the full STT, LLM, and TTS pipeline in one worker, as VideoSDK's agent architecture does, removes inter-region hops from every conversational turn.
Conclusion
Reducing TTS latency is iterative engineering, not a one-time fix. Start by attributing your current delay across the four sources, then apply the highest-leverage changes in order: pick a streaming-optimized model, enable compilation, adopt two-phase streaming, tune your network path, and cache what repeats. Every millisecond you shave from time-to-first-audio translates directly into a voice experience users describe as natural rather than robotic. If you are building real-time voice agents, VideoSDK's AI agent pipeline runs your STT, LLM, and TTS stages in a single worker connected to a real-time room, and you can start free at app.videosdk.live. What are you building with real-time voice? Drop a comment, I'd love to hear what kind of latency budget you are targeting.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ