


Handling interruptions in voice AI means detecting when a user speaks over the bot, stopping speech synthesis within roughly 300 milliseconds, and resuming the conversation without repeating content. It combines voice activity detection, echo cancellation, real-time state management, and smart interruption classification. VideoSDK's AI Agent SDK provides built-in turn detection and speech handle controls that manage this barge-in flow across web, mobile, and telephony channels, so you can focus on conversation logic rather than audio plumbing.
Human conversation is messy. We interrupt each other constantly, trail off mid-sentence, and interject with quick acknowledgements like "yeah" or "mm-hm" while someone else is talking. A voice agent that keeps talking over the user feels robotic and, worse, disrespectful of the user's time.
Yet most voice AI pipelines still treat turn-taking as a simple alternation: the bot speaks, finishes completely, then waits. That assumption breaks down the moment a real user interacts with the system. This guide covers how to handle interruptions in voice AI end to end, from the detection layer through recovery strategies, implementation best practices, and evaluation metrics, using platform-agnostic patterns you can apply to Twilio, VAPI, or a fully custom pipeline.
Why Handling Interruptions Matters in Voice AI
Interruption handling is the single most visible difference between a voice bot that feels natural and one that feels broken. When a user tries to correct the bot mid-utterance and the bot keeps talking, the user must either wait out an irrelevant response or shout over synthesized speech. Both outcomes damage trust.
The business case is measurable. Conversations where users can successfully barge in finish faster because users correct course early instead of letting the bot complete a wrong answer. Support teams deploying interruption-aware agents consistently report shorter average handle times and higher task completion rates, because the conversation stays aligned with user intent instead of drifting. In outbound calling and sales scenarios, the effect is even sharper: a prospect who cannot interrupt a scripted pitch tends to disengage entirely.
User satisfaction follows the same pattern. Voice interfaces are judged on conversational feel, and turn-taking is the foundation of that feel. A pipeline that responds to an interruption in under 300 milliseconds feels like a attentive human listener. One that takes two seconds feels like a walkie-talkie. The gap between those two experiences is where most voice AI products win or lose their users.
Core Technical Challenges in Barge-In Handling
Interruption handling looks simple from the outside but involves at least four tightly coupled technical problems.
Detecting user speech during bot output. While the bot is synthesizing speech, the microphone is still picking up audio. You must distinguish the user's voice from the bot's own output leaking back into the mic, from background noise, and from cross-talk. This is the hardest signal-processing problem in the stack.
Filtering noise and echo. Without acoustic echo cancellation, the bot hears itself and either interrupts itself in a loop or becomes deaf to real interruptions. Echo cancellation quality directly determines whether barge-in detection is even possible on speakerphone or telephony lines.
Responding within the latency budget. Research on spoken interaction consistently shows that human turn transitions average around 200 milliseconds, with gaps beyond roughly 500 milliseconds perceived as awkward. For a voice agent, the total budget from user speech onset to bot silence is roughly 300 milliseconds, which must cover VAD detection, interruption decisioning, and aborting the in-flight text-to-speech stream.
Managing conversational state after an interruption. Once the bot stops, what happens next? Should it resume the interrupted sentence, discard it, or ask the user to continue? Without explicit state management, agents repeat themselves, lose context, or produce logically broken responses.
A fifth challenge compounds the rest: streaming architecture. Every component in the chain, speech-to-text, the LLM, and text-to-speech, must support mid-stream cancellation. A pipeline that only produces complete utterances cannot stop quickly enough.
Detection Layer: Voice Activity Detection and Echo Cancellation
The detection layer decides, many times per second, whether the user is currently speaking. Its accuracy determines both how quickly you can react to an interruption and how often you falsely trigger one.
VAD Options and Trade-offs
Voice activity detection is defined as the process of classifying incoming audio frames as speech or non-speech in real time. It works by analyzing short audio windows (typically 30 to 100 milliseconds) and outputting a probability that the window contains human speech.
The main options each carry trade-offs:
- Silero VAD is a lightweight, open-source neural model favored in custom pipelines for its strong accuracy on noisy audio and small footprint. It runs comfortably on a single CPU core, which matters for self-hosted agent workers.
- WebRTC VAD ships with browser and native WebRTC stacks and is the fastest to adopt, but it is a simpler statistical model that struggles with background speech and music, producing more false positives on noisy lines.
- Picovoice Cobra is a commercial engine optimized for always-on listening on resource-constrained devices, with strong performance in embedded and IoT voice scenarios.
Three parameters shape behavior in practice. Sensitivity controls the trade-off between missed interruptions and false triggers. Minimum speech duration requires a sustained burst of speech before flagging, filtering out coughs and clicks. Padding extends the speech window slightly after activity stops, preventing the detector from chopping the tail off a user's sentence. Tuning these three against your real call audio matters more than which engine you pick.
Echo Cancellation as the Silent Hero
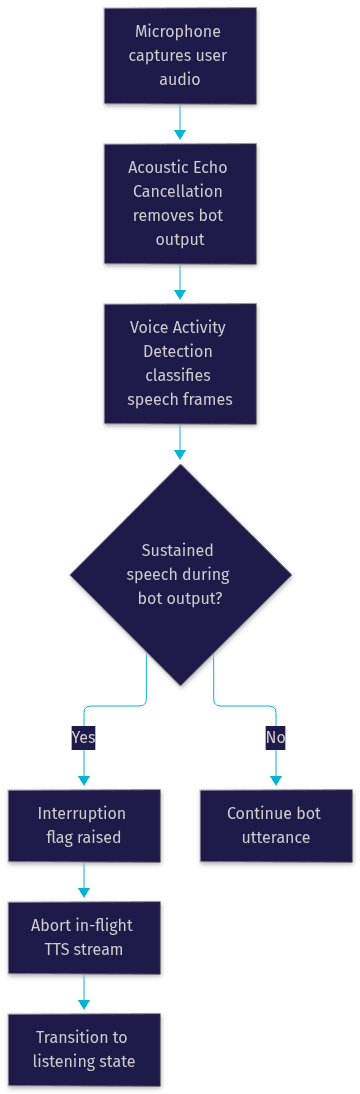
Acoustic echo cancellation (AEC) is the component that removes the bot's own synthesized speech from the microphone signal before it reaches the VAD. Without it, the bot's output appears as continuous "user speech" and interruption detection becomes impossible.
AEC works by maintaining a model of the acoustic path between the speaker and the microphone, estimating what the bot's output will sound like at the mic, and subtracting that estimate from the captured signal. Options include the AEC built into WebRTC stacks (solid and free), the Speex family of DSP components (common in telephony integrations), and hardware or OS-level echo cancellation on mobile devices and headsets, which is often the highest quality when available.
The integration point matters: AEC must run before VAD in the audio path, and the bot's output reference signal must be fed to the canceller in sync with playback. VideoSDK's real-time SDKs handle this layer for you on web and mobile, applying echo cancellation and noise suppression to the media stream before your agent's turn detection logic sees the audio.
Interruption Handling Strategies
Once detection fires, the response strategy determines whether the interruption feels graceful or chaotic. Three coordinated mechanisms make up a robust strategy.
Real-time State Management
A reliable pattern is a three-flag coordination model. The first flag tracks whether the pipeline is currently processing a response, meaning speech-to-text, the LLM, and text-to-speech are all active. The second flag marks that an interruption has been detected and confirmed. The third is a reference to the current speech stream controller, the handle that can abort the in-flight text-to-speech generation.
When the VAD raises an interruption flag, the pipeline first checks whether it is mid-utterance. If so, it signals the stream controller to stop synthesis immediately, marks the interrupted flag, and transitions the agent into a listening state. The critical detail is that the abort must propagate through every layer: the TTS stream stops, the LLM token stream is cancelled so no further tokens are generated, and any queued audio is flushed. A partial abort, where TTS stops but the LLM keeps generating, produces ghost responses that surface seconds later and confuse the dialogue.
VideoSDK's Agent SDK exposes this exact pattern through its speech handle and turn detection components, giving you direct control over preemptive response and mid-stream cancellation without building the coordination layer yourself.
Post-Interruption Recovery
Recovery is where most pipelines fall apart. The naive approach, discarding the interrupted utterance and starting over, leads to the bot repeating information the user already heard, which users find more annoying than the original interruption.
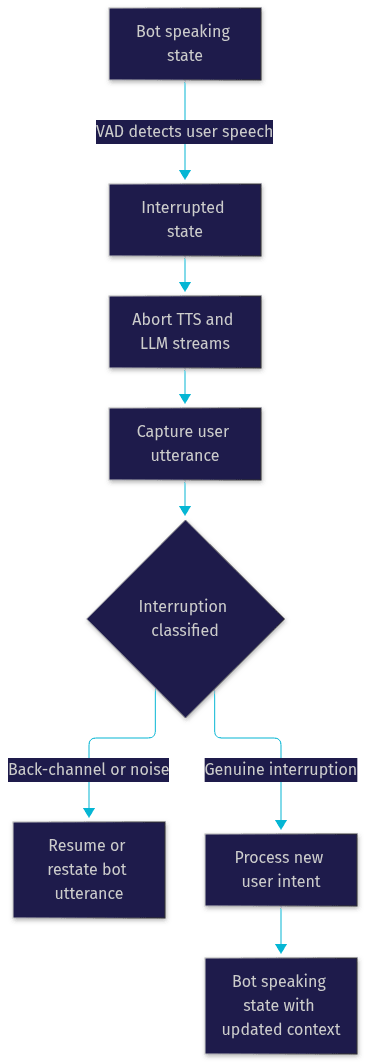
A better recovery model preserves the unfinished bot utterance as structured content. Because most agents generate responses as a stream of semantic units (a greeting, a list item, a question), the pipeline can record which units completed and which were cut off. After the user's interjection is processed, the agent can resume from the last completed unit, restate only the cut-off unit, or skip ahead depending on what the user said.
Merging user fragments is equally important. Users often interrupt with partial thoughts: "wait, what about the..." followed by a pause. The pipeline should hold the fragment open briefly, combine it with the user's next speech segment, and send the merged utterance to the LLM, rather than treating each fragment as a complete turn.
Smart Interruption Classification
Not every speech burst during bot output is a real interruption. Three categories need different handling:
- Background noise and cross-talk should be ignored, which is a matter of VAD sensitivity and duration thresholds.
- Back-channel acknowledgements ("right," "okay," "mm-hm") should be acknowledged subtly or ignored, but must not abort the bot's response.
- Genuine interruptions (corrections, questions, topic changes) should stop the bot and redirect the conversation.
Classification can start with simple heuristics, utterance length and position, and mature into an LLM-assisted classifier that labels each interjection before deciding whether to abort. Verloop's published smart interruption model demonstrates this approach in production voice bots, using semantic classification to distinguish acknowledgements from real conversational turns and cutting false interruptions dramatically. The principle generalizes: treat interruption detection as a two-stage decision, acoustic detection first, semantic classification second.
Implementation Best Practices
Practical implementation is where architecture meets tuning. These patterns apply whether you are building on Twilio, VAPI, a speech-to-speech model, or a custom pipeline.
Set endpointing thresholds deliberately. Endpointing, deciding when the user has finished speaking, typically uses a silence window between 150 and 255 milliseconds. Too short and the agent responds to every pause, chopping up hesitant speakers. Too long and every turn feels sluggish. Start around 200 milliseconds and tune against your real user population.
Use token streaming end to end. Latency accumulates at every stage. Streaming the LLM's output token by token into streaming TTS means the first word of the bot's response starts playing while the rest is still being generated, keeping time-to-first-audio well under a second and leaving more of your 300-millisecond interruption budget for detection.
Combine user fragments before processing. When a user interrupts and then continues speaking, merge the fragments into a single logical utterance before sending it to the LLM. This preserves intent and prevents the agent from answering half a question.
Handle back-channel cues explicitly. Design your dialogue logic so short acknowledgements during bot speech do not trigger a full turn change. A lightweight classifier or a duration-plus-content heuristic handles most cases.
Test on noisy lines, not clean recordings. Speakerphone audio, telephony band-limiting, and office noise change VAD behavior substantially. Build a test set from real call recordings, including echo-heavy and cross-talk scenarios, before tuning thresholds.
Keep patterns platform-agnostic. The three-flag state model, fragment merging, and two-stage classification are conceptual patterns. They port across Twilio Media Streams, VAPI agent configuration, and fully custom Python pipelines, so invest in them as reusable design rather than platform-specific glue.
For teams building on VideoSDK, the AI Agents documentation covers how turn detection, voice activity detection, and speech handles map onto these patterns, and the Python SDK guide explains how to connect custom STT and TTS providers into the same flow.
Testing, Metrics, and Evaluation
You cannot tune what you do not measure. Interruption handling should be evaluated against four concrete metrics.
Interruption response latency is the time from user speech onset to bot audio silence. Target under 300 milliseconds; measure it on real calls, not local recordings, because network jitter on telephony lines adds tens of milliseconds.
Interruption detection accuracy combines two rates: missed interruptions (user spoke, bot kept talking) and false interruptions (bot stopped for noise or an acknowledgement). Track both separately, because tuning always trades one against the other.
User satisfaction through post-call surveys or NPS captures the felt experience. A pipeline can hit every technical target and still feel wrong if recovery logic repeats content.
Conversation efficiency measures turns-to-completion and total handle time. Well-handled interruptions should reduce both, since users correct course early.
Methodologically, A/B test threshold changes on a small traffic slice before rolling out, and set up real-user monitoring that logs every interruption event with its classification, latency, and outcome. Over a few weeks of calls, this log becomes your most valuable tuning dataset.
Emerging Trends and Future Directions
Interruption handling is evolving quickly. LLM-driven turn-taking is the most significant shift: instead of fixed VAD thresholds, models increasingly predict when a turn is ending and when an interjection warrants a response, making barge-in decisions semantic rather than purely acoustic. Real-time multimodal models such as OpenAI's Realtime API and Google's Gemini Live move this logic into the model itself.
Multimodal cues are expanding detection beyond audio. In video-enabled agents, visual signals like the user leaning in or beginning to speak (detected through lip movement) can pre-empt audio-based detection, shaving latency further. VideoSDK's multimodal agent capabilities support combining these channels in a single pipeline.
Finally, standards are consolidating. Through 2025 and into 2026, the industry has converged on shared vocabulary, barge-in, endpointing, back-channeling, and on common latency expectations around sub-300-millisecond response. As speech-to-speech services mature, expect interruption handling to shift from something you build into something you configure, with the differentiator moving to recovery quality and conversation design.
Definitions Glossary
Barge-in: The act of a user speaking over the voice agent while it is still producing output, requiring the pipeline to detect the speech and stop synthesis quickly.
Voice Activity Detection (VAD): The signal-processing component that classifies incoming audio frames as speech or non-speech in real time, forming the acoustic basis of interruption detection.
Acoustic Echo Cancellation (AEC): The process of removing the agent's own synthesized audio from the microphone signal so the agent does not hear itself, enabling reliable barge-in detection.
Endpointing: Deciding when a user has finished speaking, typically based on a silence duration threshold between 150 and 255 milliseconds.
Back-channel: A short acknowledgement such as "yeah" or "okay" from the user during bot speech that should not abort the bot's response.
Speech Handle: In VideoSDK's Agent SDK, the control object that manages an in-flight speech generation stream, allowing mid-stream cancellation when an interruption is confirmed.
Key Takeaways
- Interruption handling requires a full pipeline response under roughly 300 milliseconds, covering detection, decisioning, and aborting in-flight TTS and LLM streams.
- Echo cancellation must run before voice activity detection, or the bot hears itself and interruption detection becomes impossible.
- A three-flag state model (processing, interrupted, stream controller) coordinates clean mid-stream aborts without ghost responses.
- Recovery quality matters as much as detection speed: preserve unfinished utterance units, merge user fragments, and never repeat content the user already heard.
- Classify interjections in two stages, acoustic detection first and semantic classification second, so back-channels and noise do not trigger false interruptions.
- VideoSDK's AI Agent SDK provides turn detection, voice activity detection, and speech handle controls that implement these patterns across web, mobile, and telephony channels.
Conclusion
Handling interruptions in voice AI is not one feature but a chain: echo cancellation feeding a tuned VAD, a fast abort path through your streaming stack, smart classification of what the user actually meant, and recovery logic that resumes the conversation without repeating itself. Teams that treat any link in that chain as an afterthought end up with agents that feel robotic no matter how good the underlying LLM is. Start with the detection layer, instrument your latency and accuracy metrics from day one, and iterate on real call audio. To put these patterns into practice, explore the VideoSDK AI Agents quickstart, browse the code samples, or join the VideoSDK Discord community to compare notes with other builders. What are you building with voice AI? Drop a comment, I'd love to hear what kind of interruption handling use case you're working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ