


The best AI voice API for real-time applications depends on your specific latency, scale, and quality requirements. ElevenLabs Realtime TTS offers sub-100ms time-to-first-byte for expressive, streaming text-to-speech, while Murf Falcon provides high concurrency at a low cost per minute. For developers building production-ready AI voice agents, combining a low-latency TTS provider with VideoSDK's WebRTC infrastructure ensures sub-second voice response and seamless SIP voice gateway integration.
Sub-second voice response is the difference between a conversation that feels natural and one that feels like talking to a machine. For chatbots, virtual assistants, and call-center automation, latency kills engagement. When a user asks a question, they expect an immediate answer. Any delay beyond a second breaks the illusion of intelligence and frustrates the user. Developers building these systems need the best AI voice API for real-time use cases to maintain conversational flow. This article breaks down the top real-time speech synthesis APIs, evaluation criteria, and integration strategies to help you pick the right one. We will explore how providers like ElevenLabs, Murf, and Inworld perform on latency, quality, and cost, and how you can use VideoSDK to deliver these voices over WebRTC and SIP with sub-second voice response. We will also cover cost-optimization strategies and future trends in real-time voice AI.
What Makes a Voice API "Real-Time"?
Real-time in the context of speech means end-to-end latency under one second. This involves streaming over WebSocket or WebRTC, turn-detection, semantic VAD (Voice Activity Detection), and full-duplex audio. Measurable benchmarks like median first-chunk latency and P99 latency are critical for latency-critical voice applications. A real-time API does not wait for the entire text response to be generated before speaking. It streams audio chunks as the text is produced. This streaming text-to-speech approach drastically reduces the time to first audio byte. Semantic VAD goes beyond simple silence detection to understand when a user has finished speaking based on context, preventing premature responses. Turn-detection allows the system to manage the flow of conversation, enabling barge-in where a user can interrupt the AI. Full-duplex audio means the system can listen and speak simultaneously, which is essential for natural conversational dynamics. Without these components, an API is just a standard TTS service, not a real-time voice API. The distinction is crucial because standard TTS APIs introduce significant buffering delays, making them unsuitable for interactive conversational AI. A true real-time API manages the entire audio stream lifecycle, from capturing the user's voice to playing back the synthesized response, with minimal delay.
Evaluation Criteria
Choosing the best AI voice API for real-time applications requires evaluating several technical and business factors. Developers must look beyond marketing claims and measure providers against concrete benchmarks.
- Latency: The most critical factor. Look for sub-200ms first-chunk latency and sub-1s end-to-end response. This includes the time taken by speech-to-text, the LLM, and the TTS provider. If the TTS API takes 300ms to start speaking, the entire pipeline will feel sluggish.
- Audio Quality: Evaluate benchmark scores from independent sources like the Artificial Analysis Speech Arena. Look for expressive prosody, natural intonation, and a low artifact rate. The voice should sound human, not robotic. A low-latency robotic voice is still a bad user experience.
- Scalability: Consider concurrent call handling and cost per minute TTS. If you are building a high-volume call-center, the API must handle thousands of simultaneous streams without degradation. Check the provider's stated concurrency limits and test them under load.
- Multilingual & Voice Cloning: Check the number of supported languages and the turnaround time for voice cloning. Multilingual TTS is essential for global applications. Voice cloning allows you to create custom voices for your brand, but the cloning process should be fast and require minimal training data.
- Integration Flexibility: The API should offer WebSocket TTS, REST endpoints, and SIP voice gateway support. A developer-friendly SDK is a big plus. The easier it is to integrate, the faster you can ship your product.
- Security & Compliance: Ensure the provider supports token-based authentication, data residency options, and necessary certifications like SOC 2, GDPR, and HIPAA for healthcare applications. Never expose your API keys on the client side.
Top Real-Time AI Voice APIs
Let's look at the leading providers in the market and see how they stack up against these criteria.
Inworld Voice API
Inworld offers a production-ready voice API designed for AI voice agents. It provides sub-second latency and is model-agnostic, meaning you can plug in different LLMs and TTS models. Inworld is known for its advanced semantic VAD and turn-detection capabilities, which are built directly into the platform. According to the Artificial Analysis Speech Arena, Inworld ranks highly for its combination of low latency and high audio quality. It also supports voice cloning and multilingual TTS, making it a strong contender for gaming and interactive entertainment. Inworld's focus on character-driven AI makes it unique in the market. Their API is designed to handle the nuances of conversational flow, including interruptions and emotional tone shifts.
ElevenLabs Realtime TTS
ElevenLabs is widely recognized for its expressive voice library and high-quality streaming text-to-speech API. Their realtime TTS endpoint offers sub-100ms time-to-first-byte (TTFB), making it one of the fastest options available. The API streams audio over WebSocket, allowing for immediate playback as text is generated. ElevenLabs uses a pricing model based on characters processed, which can be cost-effective for shorter responses but requires careful monitoring for long conversations. Their developer-friendly SDKs make integration straightforward across multiple platforms. ElevenLabs also excels in voice cloning, allowing users to create highly realistic custom voices with minimal audio samples. This makes it a favorite for developers who prioritize voice quality and expressiveness over raw cost efficiency.
Murf Falcon
Murf Falcon is built for scale and speed. It boasts a 55ms model inference time and sub-130ms end-to-end latency. With a library of over 150 voices across 35 languages, it offers significant variety. One of its standout features is its pricing: approximately 1 cent per minute, which is highly competitive for high-volume applications. Murf Falcon is designed to handle high concurrency, supporting up to 10,000 concurrent calls, making it ideal for large-scale call-center automation. The platform also supports voice cloning and custom voice creation. For developers building enterprise applications that need to handle thousands of calls simultaneously without breaking the bank, Murf Falcon is a compelling choice.
Soniox Web SDK
Soniox focuses on real-time streaming TTS directly in the browser. It uses WebSocket transport and supports temporary API keys for secure client-side connections. Soniox is particularly strong in scenarios requiring semantic VAD and low-latency playback without heavy backend processing. It is a good choice for web-based virtual assistants where minimizing backend infrastructure is a priority. Soniox also offers real-time speech recognition, making it a potential all-in-one solution for developers who want to handle both STT and TTS on the client side. Their focus on browser-based performance makes them unique in a market dominated by backend-heavy solutions.
Azure OpenAI Realtime API
Azure OpenAI Realtime API brings the GPT-4o family of models to the enterprise with built-in speech-in-speech-out capabilities. It uses WebSocket connections and OpenAI-compatible events, making it familiar to developers already using OpenAI's ecosystem. Azure provides enterprise-grade security, data residency options, and compliance certifications like SOC 2 and HIPAA. This makes it the go-to choice for organizations with strict compliance requirements. The API handles the entire pipeline from audio in to audio out, simplifying the architecture for developers. However, this comes at a premium price point compared to standalone TTS providers. For enterprises already invested in the Azure ecosystem, the integration and compliance benefits often outweigh the cost.
ElevenLabs vs. Murf vs. Inworld – Quick Comparison Table
[LINKABLE ASSET — comparison table]
| Provider | Latency (TTFB) | Price | Languages | Voice Cloning | Max Concurrency |
|---|---|---|---|---|---|
| ElevenLabs | Sub-100ms | Per 1M characters | 29+ | Yes | High |
| Murf Falcon | Sub-130ms | ~1¢/minute | 35 | Yes | 10,000+ |
| Inworld | Sub-second | Custom | 20+ | Yes | High |
ElevenLabs wins on raw TTFB and voice expressiveness, while Murf Falcon dominates on cost and concurrency for large-scale deployments. Inworld offers a balanced approach with strong conversational AI features.
How to Choose the Right API for Your Project
Selecting the right API depends on your specific use case, latency priorities, language needs, and budget. A customer-support bot might prioritize integration with existing SIP infrastructure and high concurrency, pointing to Murf Falcon. A multilingual virtual tutor might need the expressive prosody of ElevenLabs. A high-volume call-center with strict compliance needs might require Azure OpenAI Realtime API.
Here is a decision flow to help you visualize the selection process:
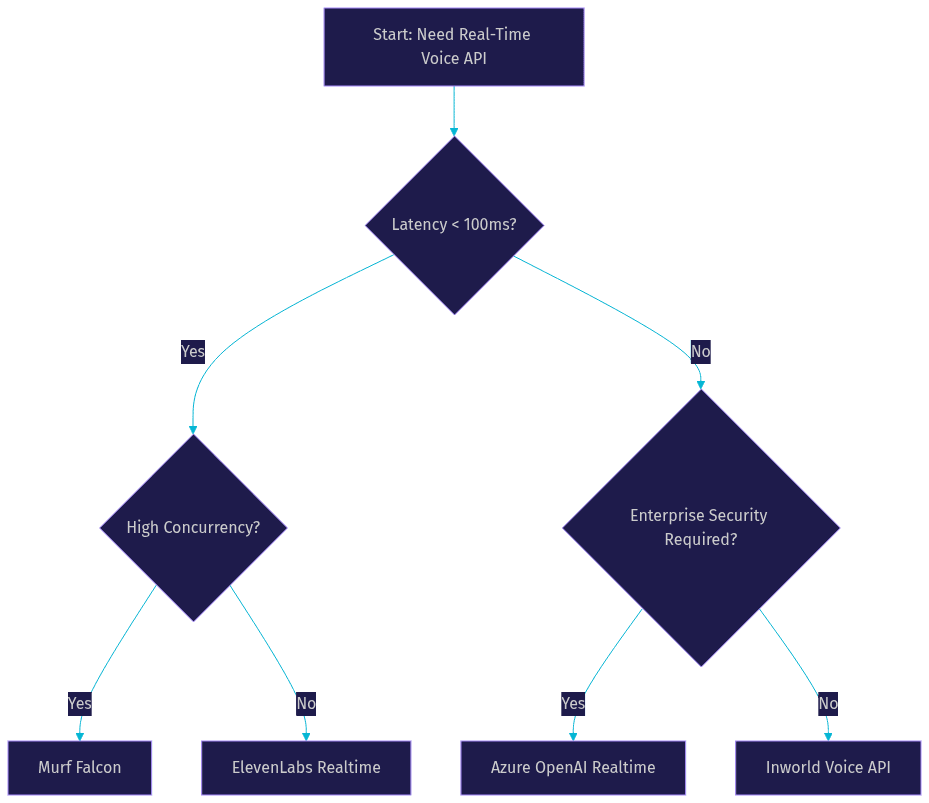
When building these systems, remember that the TTS API is only one part of the pipeline. You need a robust real-time communication layer to deliver the audio to the user. VideoSDK provides the WebRTC voice integration and SIP voice gateway needed to connect your AI voice agents to callers on any device. By using VideoSDK, you can focus on the AI logic while the SDK handles the complex networking and media routing.
Integration Tips for Real-Time Voice
Integrating a real-time voice API requires careful attention to the transport layer and conversation management.
- Choose WebSocket or WebRTC based on your client platform. WebRTC is preferred for mobile and web apps requiring sub-second voice response and full-duplex audio. WebSocket is simpler but lacks built-in audio processing features like echo cancellation and noise suppression. For production applications, WebRTC is almost always the better choice.
- Implement turn-detection and barge-in to avoid audio overlap. The system must be able to stop speaking immediately if the user interrupts. This requires a tight integration between the STT, LLM, and TTS components. If the TTS is still streaming audio when the user starts speaking, the system needs to flush the audio buffer and start processing the new input.
- Secure token generation on the server side is mandatory. Never expose API secrets on the client. Use token-based authentication to grant temporary access. VideoSDK provides a secure token generation mechanism that you can use to authenticate users before they join a call. This ensures that only authorized users can access your voice pipeline.
- Test under realistic network conditions (3G, Wi-Fi, VPN). Network jitter and packet loss can significantly impact perceived latency. Use network emulation tools to simulate poor conditions during testing. This will help you identify bottlenecks in your pipeline and optimize accordingly.
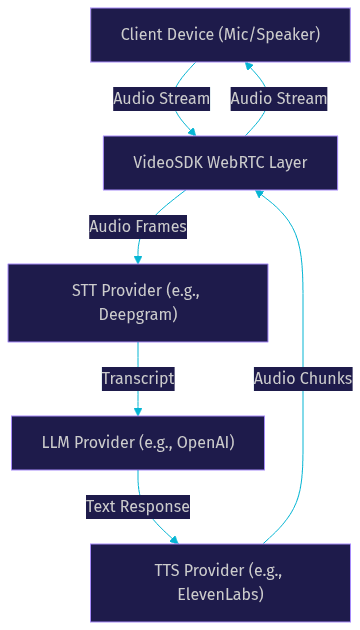
- VideoSDK simplifies this process by providing a unified SDK that handles WebRTC transport, media streaming, and SIP integration. You can connect your chosen TTS provider to a VideoSDK room, and the SDK handles the complex networking logic. This includes managing ICE candidates, handling NAT traversal, and adapting to changing network conditions.
Here is an architecture diagram showing how a real-time voice pipeline integrates with VideoSDK:
Cost-Optimization Strategies
Managing costs is crucial for production voice applications.
- Compare batch-level pricing versus per-character pricing. If your application generates long responses, per-minute pricing like Murf Falcon's might be cheaper than per-character pricing. Analyze your average response length to determine the most cost-effective model.
- Use voice cloning to reduce repeated synthesis. If the same phrases are used frequently, caching the audio can save significant costs. However, be mindful of storage costs for cached audio files.
- Leverage the free tier for prototyping, then scale with volume discounts. Most providers offer a free tier to test the API before committing to a paid plan. Once you are ready for production, negotiate volume discounts based on your expected usage.
- Monitor your usage closely. Unexpected spikes in usage can lead to large bills. Set up alerts to notify you when usage exceeds a certain threshold. Implement rate limiting to prevent abuse.
Future Trends in Real-Time Voice AI
The field of real-time voice AI is evolving rapidly. We are seeing emerging sub-50ms models that will make conversations indistinguishable from human interaction. Multimodal agents that can process audio and video simultaneously are becoming more common. Edge-deployed inference is growing in importance, allowing for privacy-preserving on-device synthesis. This reduces latency further by eliminating the network round-trip. As these trends mature, the definition of "real-time" will become even stricter, pushing providers to innovate faster. We can also expect to see more specialized models for different industries, such as healthcare and finance, with built-in compliance and domain-specific vocabulary. Another emerging trend is the use of speech-to-speech API models, which bypass the text intermediate step entirely, translating directly from input speech to output speech. This can significantly reduce latency and preserve the emotional tone of the original speaker.
Definitions Glossary
Semantic VAD: Voice Activity Detection that uses context and semantics to determine if a user has finished speaking, rather than just detecting silence.
Turn-detection: The mechanism that decides when a user has finished speaking and the AI agent should respond, managing the flow of conversation.
Full-duplex audio: The ability of a system to transmit and receive audio simultaneously, allowing for natural conversational dynamics and barge-in.
TTFB (Time to First Byte): The time interval between sending a request and receiving the first byte of the response, a critical metric for streaming text-to-speech APIs.
WebRTC voice integration: The use of WebRTC protocols to enable real-time, low-latency audio communication between a client and a server.
Key Takeaways
- The best AI voice API for real-time use cases balances sub-second latency, high audio quality, and scalable concurrency.
- ElevenLabs Realtime TTS offers the fastest time-to-first-byte, while Murf Falcon provides the best cost-efficiency for high-volume call centers.
- Azure OpenAI Realtime API is the top choice for enterprise applications requiring strict compliance and data residency.
- Integrating these APIs requires a robust transport layer. VideoSDK provides the WebRTC and SIP infrastructure needed to deliver sub-second voice response to any device.
- Always test under realistic network conditions and use token-based authentication to secure your API keys.
Conclusion
Choosing the best AI voice API for real-time applications is a critical decision that impacts user experience and operational costs. ElevenLabs, Murf Falcon, and Inworld each offer unique strengths depending on your latency, scale, and quality requirements. By combining your chosen TTS provider with VideoSDK's real-time communication infrastructure, you can build production-ready AI voice agents that deliver natural, sub-second conversations. Explore the VideoSDK AI Voice Agents documentation to start building your proof-of-concept today. What are you building with VideoSDK? Drop a comment below.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ