


Background noise cancellation in Python is the process of removing unwanted sounds (fans, traffic, keyboard clicks, room echo) from an audio signal using signal processing or deep learning. Python is the preferred language for this work because it combines mature audio libraries like PyAudio and sounddevice with state-of-the-art denoising models such as DTLN and DeepFilterNet. For production voice apps, VideoSDK also provides built-in noise suppression at the SDK level, so you can skip the DSP work entirely when embedding calls into your product.
Introduction
Every developer who has built anything with live audio has hit the same wall: the microphone picks up everything. The laptop fan, the air conditioner, the construction site two streets over. A recording that sounds fine in your headphones turns into an unusable mess once it passes through a compression codec and lands on someone else's device.
Background noise cancellation in Python has become one of the most practical skills in the audio developer toolkit, and for good reason. Python sits at the intersection of rapid prototyping and production deployment. You can test a spectral gating idea in an afternoon, swap in a neural denoiser the next day, and ship the winning approach as a service or an edge deployment on a Raspberry Pi. The ecosystem is unusually rich: low-latency capture libraries, battle-tested scientific computing stacks, and open-source deep learning models that rank competitively in the Microsoft DNS Challenge.
This guide walks through the full picture. We cover the audio theory you actually need, the libraries worth your time, a complete real-time pipeline architecture, a conceptual implementation walkthrough, evaluation metrics, and the pitfalls that bite people in production.
Understanding Background Noise Cancellation in Python
What is background noise cancellation?
Background noise cancellation is defined as the process of separating a desired signal (usually speech) from unwanted acoustic interference in a captured audio stream. It works by analyzing the spectral and temporal characteristics of the incoming audio, identifying components that look like noise rather than speech, and suppressing or removing those components while preserving the voice content.
There are two broad families. Passive cancellation is physical: microphone placement, directional pickup patterns, and hardware shielding that prevent noise from ever reaching the sensor. Active cancellation, the kind you build in software, works on the digitized signal after capture. This article is about the software kind.
A typical software pipeline runs through a fixed sequence of steps. The raw signal is captured in short frames, transformed into a frequency-domain representation, processed to attenuate noise, transformed back to the time domain, and reassembled into a continuous output stream. The differences between approaches are almost entirely in what happens during the processing step.
Core audio concepts: STFT, spectral gating, and deep learning
The short-time Fourier transform (STFT) is the foundation of nearly all noise cancellation. It works by slicing the audio into overlapping short frames (typically 10 to 32 milliseconds), applying a window function to each frame, and computing a Fourier transform that reveals which frequencies are present during that slice. The result is a time-frequency representation often visualized as a spectrogram.
The STFT output is complex-valued, which means each frequency bin has both a magnitude (how loud that frequency is) and a phase (where in its cycle the waveform is). Most denoising algorithms modify only the magnitude and leave the phase untouched, because human hearing is far less sensitive to phase errors than to magnitude errors. Reconstructing the signal requires both, so the untouched phase is reused during the inverse transform.
Spectral gating is the classical approach: estimate the noise floor (usually from a silent segment), then attenuate any frequency bin whose magnitude falls below a threshold derived from that estimate. Deep learning approaches replace this hand-tuned rule with a neural network that learns a masking function from thousands of hours of noisy and clean speech pairs. Models like DTLN and DeepFilterNet predict, per frequency bin, how much of the signal to keep. The result is dramatically better handling of non-stationary noise, things like keyboard typing or a barking dog, where a static noise floor estimate fails completely.
Popular Python Libraries and Tools
PyAudio and sounddevice for real-time capture
Real-time noise suppression starts with getting audio into Python fast, and two libraries dominate this space. PyAudio is the long-standing standard, wrapping PortAudio to give you blocking and callback-based access to microphones and speakers across Windows, macOS, and Linux. Sounddevice is the more modern alternative, built on the same PortAudio core but with a cleaner API and better support for callback-driven streaming, which matters when you want to process audio while it is being captured rather than in batches afterward.
Both give you control over the parameters that determine latency: sample rate, frame size, and buffer count. For denoising work, a 16 kHz sample rate is the common choice because most speech enhancement models are trained on 16 kHz audio, and capturing at that rate avoids a resampling step in your pipeline.
Noisereduce and speexdsp bindings
The noisereduce package is the most popular entry point for Python audio denoising. It implements a stationary spectral-gate method: you supply a noise profile (or let it infer one from the quietest portions of the signal), and it attenuates frequency bins below an adaptive threshold. It is excellent for offline cleanup of recordings with steady noise like hum or hiss, and it runs in seconds on a laptop.
Speexdsp is the venerable C library from the Speex codec project, and Python bindings expose its preprocessor, which includes noise suppression, automatic gain control, and voice activity detection. It is lightweight, fast on constrained hardware, and a good fit for embedded projects, though its quality trails modern neural models on aggressive noise.
Deep learning models: DTLN and DeepFilterNet
DTLN (Deep Time-Lorentzian Network) is a compact model that placed well in the Interspeech 2020 DNS Challenge. It processes the STFT magnitude through a recurrent network in the frequency domain, then applies a second recurrent layer in the time domain on the learned representation. The full model runs around one million parameters, small enough for real-time CPU inference, and the authors released a real-time streaming variant specifically designed for frame-by-frame processing.
DeepFilterNet takes a different architectural approach. It applies deep filtering, predicting filter coefficients that operate on complex-valued spectral features rather than predicting a simple magnitude mask, which better preserves phase coherence and reduces artifacts. DeepFilterNet2 and DeepFilterNet3 improved both quality and speed, and the project ships with real-time streaming support, making it a strong default choice for production Python pipelines in 2026. It runs comfortably on a modern laptop CPU at well under real-time factor.
Choose a learned model when your noise is non-stationary, when quality is user-facing, or when you are already comfortable managing model weights. Choose spectral gating when you need something that works in ten minutes with zero dependencies on neural network runtimes.
Supporting utilities: numpy, scipy, and librosa
The scientific Python stack does the heavy lifting underneath everything above. NumPy handles the array math for framing, windowing, and the STFT itself. SciPy provides signal processing primitives, including window functions, resampling, and filter design. Librosa is the go-to for audio-specific utilities: loading files at a consistent sample rate, computing spectrograms, and writing cleaned output. None of these denoise audio on their own, but every pipeline you build will lean on them.
Designing a Real-Time Background Noise Cancellation Pipeline
A real-time denoising pipeline is a streaming system, and thinking about it that way from the start saves weeks of rework. The architecture below shows the canonical data flow from microphone to output.
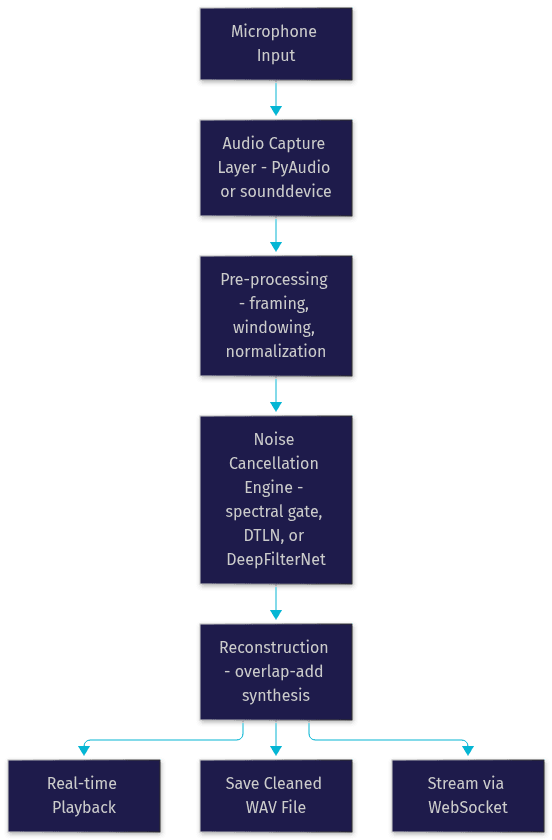
The capture layer delivers fixed-size frames on a strict schedule. Pre-processing converts each raw frame into the representation the engine expects: a windowed time-domain buffer or a complex spectrogram slice. The engine produces a cleaned representation, reconstruction stitches frames back into a continuous signal, and the output stage routes that signal wherever it needs to go.
Choosing the right engine: spectral gate vs. DTLN vs. DeepFilterNet
The engine choice drives every other decision in the pipeline. A spectral gate has near-zero startup cost, runs on anything, and adds only a few milliseconds of latency, but it only handles stationary noise well. DTLN adds roughly 20 to 40 milliseconds of algorithmic latency depending on frame configuration, runs in real time on a modest CPU, and handles non-stationary noise far better. DeepFilterNet offers the best published quality among the three, runs in real time on CPU with a similar latency budget, and includes built-in streaming support, but requires managing model weights and a more involved integration.
For a Raspberry Pi or edge deployment, DTLN's small footprint is often the winner. For a server-side pipeline cleaning call recordings, DeepFilterNet's quality advantage justifies the overhead. For a quick script that fixes a noisy podcast recording, noisereduce is still the fastest path to a result.
Handling latency and buffer management
Latency is the defining constraint of real-time audio. For conversational applications, the generally accepted target is keeping total round-trip audio latency under about 150 milliseconds, and the denoising stage should consume well under 100 milliseconds of that budget. Three levers control it.
Chunk size determines how much audio you process at once. Smaller chunks mean lower latency but more per-call overhead and less context for the model. A 20 to 32 millisecond frame at 16 kHz is the sweet spot for most neural denoisers, since it matches their training configuration.
Overlap-add is the reconstruction technique that makes framed processing seamless. Because windowing attenuates the edges of each frame, consecutive frames are captured with 50 percent overlap and summed during synthesis, so the attenuated edges cancel out and the output is continuous. Getting the overlap and window pairing wrong produces audible artifacts, typically a periodic buzzing at the frame rate.
Buffer discipline is the operational side. If your processing thread cannot keep up with the capture rate, buffers overflow and audio glitches. The rule of thumb: your engine's real-time factor (processing time divided by audio duration) must stay comfortably below one, ideally below 0.5, to leave headroom for garbage collection pauses and OS scheduling.
Step-by-Step Implementation Guide (Conceptual)
1. Capture audio in short frames
Open the microphone through your capture library at a fixed sample rate, 16 kHz for neural models, 44.1 or 48 kHz if you are targeting general audio. Request frames of a consistent length, and use the callback-based streaming mode rather than reading in a loop. The callback guarantees a steady supply of frames paced by the audio hardware clock, which is exactly the rhythm a streaming denoiser expects. Inconsistent frame lengths are the number one cause of garbled output when feeding neural models, because the frame size is baked into the model's internal configuration.
2. Apply pre-processing: windowing and normalization
Each incoming frame gets a Hann window applied before any frequency-domain work. The Hann window tapers the frame edges to zero, which suppresses spectral leakage, the smearing of energy across frequency bins that would otherwise distort the noise estimate. Normalization, scaling samples to a consistent amplitude range, keeps the model's input distribution close to what it saw during training. Skipping normalization is a common cause of a model that works brilliantly on test clips and poorly on real microphones, which often deliver much lower input levels.
3. Run the chosen denoising algorithm
For a spectral-gate approach, the flow is: compute the STFT of the windowed frame, compare each frequency bin's magnitude against the running noise floor estimate, attenuate bins below the threshold by a fixed factor, and keep the phase untouched. The noise floor can be estimated from the first few hundred milliseconds of presumed silence or updated continuously with a slow-adapting minimum tracker.
For a DTLN or DeepFilterNet model, the flow is: load the model weights once at startup, convert each frame into the model's expected input representation (a magnitude spectrogram slice for DTLN, complex features for DeepFilterNet), run a single inference step, and collect the predicted mask or filter coefficients. The critical implementation detail is state: these models are recurrent or stateful across frames, so the model instance must persist between frames and process them strictly in order. Recreating the model per frame destroys the temporal context and collapses quality to worse than a spectral gate.
4. Reconstruct the cleaned signal
Apply the predicted mask or filter to the original complex spectrum, run the inverse STFT to return to the time domain, and use overlap-add synthesis to merge consecutive frames into a continuous output stream. A light post-filter, such as a single-pole smoothing of the gain applied to each frequency bin across time, reduces the musical noise artifact, the warbling isolated tones that appear when a gate flickers rapidly on and off at the frame rate.
5. Output options: playback, file saving, and streaming
The cleaned stream can go three places. Direct playback through the same audio library gives you an instant feedback loop during development, and hearing your own denoised voice in real time is the fastest way to catch pipeline bugs. Saving to a WAV file suits offline batch processing, cleaning archived recordings or uploaded podcasts. Streaming over a WebSocket suits live applications: a browser client captures mic audio, sends compressed frames to a Python service running the denoiser, and receives cleaned audio back. This is also the pattern to use when you want denoised audio feeding into a VideoSDK room, where the SDK's real-time communication infrastructure handles the transport, and its built-in noise suppression can handle the cleanup server-side instead.
Evaluating Performance and Quality
Objective metrics: SNR improvement, PESQ, and MOS
You cannot improve what you do not measure. Signal-to-noise ratio improvement compares the ratio of speech energy to noise energy before and after processing; it is easy to compute with numpy from paired noisy and cleaned signals, but it correlates only loosely with perceived quality.
PESQ (Perceptual Evaluation of Speech Quality) is the industry-standard objective metric. It models human auditory perception to score processed speech against a clean reference on a scale from roughly 0.5 to 4.5. Python implementations exist via the pesq package, and the standard evaluation protocol is to mix clean speech with noise at a known SNR, denoise, and measure PESQ before and after. The DNS Challenge used a variant called DNSMOS, a neural network that estimates MOS without a clean reference, which is essential when you only have real-world noisy recordings.
MOS (Mean Opinion Score) is the subjective gold standard: humans rate samples from 1 to 5. Objective metrics approximate it; they do not replace it.
Subjective listening tests
For informal evaluation, build a small comparison rig: take five to ten representative noisy clips (office, street, cafe, keyboard typing, fan hum), process them with each candidate engine, and listen to the pairs in a randomized order without knowing which is which. Better still, recruit a few colleagues and track preferences. A model that wins on PESQ but loses consistently in blind listening is the wrong model.
Profiling CPU and GPU usage and latency
Profile before optimizing. Python's built-in cProfile reveals where time goes in a CPU pipeline and will quickly show whether the bottleneck is inference, the STFT, or data marshaling between the audio callback and the processing thread. For GPU pipelines, vendor profiling tools show kernel-level timings. The thresholds that matter: real-time factor below 0.5, end-to-end added latency below 100 milliseconds, and no buffer overruns during a sustained ten-minute run. If you miss those numbers, reduce frame overlap, shrink the model, or move inference off the audio callback thread entirely.
Common Pitfalls and Troubleshooting
Sample-rate mismatches are the most frequent bug: capturing at 48 kHz while the model expects 16 kHz produces chipmunk-speed garbage. Always resample explicitly at the boundary. Buffer underruns and overruns show up as clicks or dropouts; they almost always mean your processing thread is too slow or is being blocked, so move inference off the callback thread and use a bounded queue between capture and processing. Model incompatibility, feeding a streaming model with variable frame sizes, or forgetting to persist recurrent state between frames, silently degrades quality. Finally, double windowing (applying a window in pre-processing and again inside a library that windows internally) attenuates your signal twice; check what each stage does to the frame edges.
Future Directions in Python-Based Noise Cancellation
The field is moving quickly. Transformer-based denoisers are pushing quality further, with attention mechanisms capturing longer temporal context than recurrent models, at the cost of higher compute. The current research frontier, visible in recent DNS Challenge entries and Interspeech papers, is closing that gap on edge devices through distillation, quantization, and pruning, so that flagship-model quality runs on a phone or a Raspberry Pi.
For developers, two practical currents matter. First, the best open-source models now ship with streaming-first designs, so real-time integration is getting easier every release. Second, if you are building voice applications rather than audio research, platforms like VideoSDK's AI agent infrastructure handle noise suppression, de-noise, and full STT-LLM-TTS pipelines as built-in capabilities, which means the bar for rolling your own DSP keeps rising. Stay current by following the DNS Challenge results, the DeepFilterNet repository, and the VideoSDK Python SDK for production voice infrastructure.
Definitions Glossary
STFT (Short-Time Fourier Transform): A method that slices audio into short overlapping frames and transforms each into the frequency domain, producing a time-frequency view of the signal that most denoising algorithms operate on.
Spectral Gating:** A classical noise reduction technique that estimates the noise floor per frequency band and attenuates any bin whose energy falls below a threshold derived from that estimate.
DTLN: A compact recurrent neural network for real-time speech enhancement, around one million parameters, that processes spectral features in two stages and runs in real time on CPU.
DeepFilterNet: A family of neural speech enhancement models that predict complex filter coefficients rather than magnitude masks, achieving strong quality with real-time CPU inference and built-in streaming support.
Overlap-Add: The synthesis technique that reassembles processed frames into continuous audio by overlapping consecutive frames by half their length and summing them, canceling the edge attenuation introduced by windowing.
Real-Time Factor: The ratio of processing time to audio duration; a value below one means the pipeline keeps up with live audio, and values below 0.5 leave healthy headroom.
Key Takeaways
- Background noise cancellation in Python spans a spectrum from simple spectral gating (noisereduce) to neural models (DTLN, DeepFilterNet), and the right choice depends on whether your noise is stationary and whether you can afford model inference.
- A real-time pipeline is a streaming system: consistent frame sizes, persistent model state, and overlap-add reconstruction are the three details that separate working implementations from garbled output.
- Target a real-time factor below 0.5 and added latency under 100 milliseconds, and profile with cProfile before assuming your bottleneck is the model.
- Evaluate with PESQ or DNSMOS for objectivity, but never ship a denoiser that has not survived blind listening tests on your actual noise conditions.
- If you are building voice or calling features rather than audio research, VideoSDK provides built-in noise suppression across its video and audio calling SDKs, letting you skip the DSP work entirely.
Conclusion
Background noise cancellation in Python is one of those problems where the ecosystem has matured faster than most tutorials have caught up. With sounddevice for capture, noisereduce for quick offline cleanup, and DTLN or DeepFilterNet for real-time neural suppression, you can go from a noisy microphone to a production-quality pipeline in days, not months. Start with the architecture here, measure honestly, and let listening tests make your final engine choice. And if your end goal is embedding clean voice into an application, try VideoSDK's free tier at app.videosdk.live where noise suppression comes built in. What are you building with Python audio processing? Drop a comment, I'd love to hear what kind of noise cancellation use case you're working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ