


An AI voice agent WebRTC API is a real-time communication interface that connects a user's microphone and speaker to a speech-to-text, LLM, and text-to-speech pipeline over a low-latency WebRTC audio stream. VideoSDK provides this through its open-source Python Agent SDK, which manages sessions inside WebRTC rooms and lets you swap STT, LLM, and TTS providers like OpenAI, Deepgram, and ElevenLabs without touching your client code. The result is a voice agent that responds in well under a second instead of the multi-second delays of HTTP-based approaches.
Voice interfaces have crossed the threshold from novelty to production infrastructure. In 2026, the combination of fast speech-to-text, capable large language models, and natural text-to-speech has made real-time conversational AI genuinely shippable. What used to be a research demo is now a customer support line, an interactive tutor, or an in-game companion.
The hard part is not the intelligence. It is the plumbing. An ai voice agent webRTC api has to move raw microphone audio from a browser or phone to a processing pipeline and stream synthesized speech back, all while keeping round-trip latency low enough that the conversation feels human. HTTP polling and REST-based audio exchange cannot do this. WebRTC can, and it has become the default transport for serious voice agent deployments.
This guide breaks down the architecture, the backend stack options, the integration workflow, and the production practices that separate a working demo from a reliable product. By the end, you will understand how to design, secure, and scale a WebRTC-based voice agent, and where modular platforms like VideoSDK's AI Agent SDK fit in.
What Is an AI Voice Agent WebRTC API?
An AI voice agent WebRTC API is defined as a programmatic interface that combines real-time audio transport (WebRTC) with a conversational AI pipeline (STT, LLM, TTS) so developers can embed spoken AI interactions into web and mobile applications. The API handles the two hardest problems in voice AI simultaneously: moving audio with sub-second latency, and orchestrating the model chain that turns speech into intelligent responses.
The WebRTC layer works by establishing a peer connection between the client and a media server or agent worker, negotiating codecs and network paths through a signaling endpoint, then exchanging bidirectional audio streams over SRTP. Because WebRTC was designed for live conversation, it handles jitter, packet loss, and bandwidth adaptation natively, which is exactly what a voice agent needs when a user is speaking over a flaky mobile connection.
The AI layer works by chaining three model types: a speech-to-text engine transcribes incoming audio in real time, a large language model reasons over the transcript and decides what to say or do, and a text-to-speech engine converts the response into natural spoken audio. VideoSDK provides this full chain through its Agent SDK, where a Python Agent Worker manages the session inside a VideoSDK room and streams the synthesized voice back to the participant.
Core Building Blocks
Every production voice agent, regardless of vendor, is assembled from the same four components.
Speech-to-Text engines convert the user's raw audio stream into text. Real-time STT engines like Deepgram's streaming models or OpenAI's Realtime transcription emit partial hypotheses as the user speaks, so the agent can start reasoning before the sentence finishes.
LLM orchestration sits in the middle. The language model receives the running transcript plus conversation history and produces either a spoken reply or a tool call. Orchestration layers also handle turn detection, deciding when the user has actually finished speaking rather than merely paused.
Text-to-Speech synthesis turns the model's output into audio. Low-latency TTS providers such as ElevenLabs and Cartesia stream audio in chunks so playback can begin before the full sentence is synthesized.
WebRTC signaling and media transport carries everything. The signaling endpoint exchanges session descriptions (offer and answer) and ICE candidates, after which audio flows directly over the negotiated connection with encryption built in.
Why Use WebRTC Over Traditional HTTP?
WebRTC beats HTTP for voice because it was built for exactly this workload: live, bidirectional, latency-sensitive media.
Latency is the first reason. An HTTP-based flow requires the client to record a full utterance, upload it, wait for processing, and download a response, which typically produces 3 to 10 seconds of dead air. WebRTC streams audio in 20-millisecond frames, so a well-tuned pipeline achieves end-to-end response times under one second, which is the threshold where a conversation feels natural.
Bandwidth efficiency is the second. WebRTC uses efficient audio codecs like Opus that adapt their bitrate to network conditions, so a voice session consumes a fraction of the bandwidth of repeatedly uploading raw audio files.
Finally, WebRTC handles the messy realities of real networks: NAT traversal through STUN and TURN infrastructure, automatic jitter buffering, and packet loss concealment. With HTTP you would rebuild all of that yourself. For a deeper grounding, the W3C WebRTC specification defines the offer/answer and ICE model every implementation follows.
Choosing the Right Backend Stack
The backend stack is where most architectural decisions get made, and in 2026 you have two broad paths: assemble open-source components yourself, or adopt an API-first voice platform that bundles the plumbing.
Open-source frameworks like LiveKit's agent stack and FastRTC give you maximum control. You run your own media servers, pick your own models, and own the deployment. The trade is operational burden: you maintain SFU infrastructure, TURN servers, and the agent runtime yourself.
API-first platforms like VideoSDK, Pinecall, and CallMissed flip the model. The platform owns rooms, signaling, token auth, and media routing, and you configure the AI pipeline on top. VideoSDK's approach is distinctive because the Agent SDK itself is open source, so you get managed infrastructure without a black-box agent runtime, and you can deploy the worker to VideoSDK Agent Cloud or self-host it with Docker or Kubernetes.
When evaluating any stack, weigh four criteria. First, model support: can you swap STT, LLM, and TTS providers without rewriting your agent? Second, authentication: does it support short-lived, scoped tokens rather than long-lived API keys exposed in the browser? Third, scalability: how does it behave at 10, 100, and 1,000 concurrent sessions? Fourth, language coverage: does the STT and TTS chain support the languages your users actually speak?
Swappable STT/TTS/LLM Backends
Modularity is the single most important property of a voice agent backend. Model quality moves fast, and the best STT engine this quarter may be overtaken next quarter.
A well-designed stack treats each model slot as a plugin. For STT, developers commonly pair streaming engines like Deepgram or OpenAI Whisper with fallback options. For LLM reasoning, the choice spans OpenAI's models, Anthropic's Claude, Google Gemini, and self-hosted options like Ollama when data privacy demands on-premise inference. For TTS, ElevenLabs and Cartesia dominate on naturalness, while OpenAI TTS and AWS Polly offer solid lower-cost alternatives.
VideoSDK's Agent SDK is built around exactly this pattern: each provider is a swappable plugin, and a fallback adapter can automatically switch to a secondary model when the primary fails or times out. That means your voice agent survives a provider outage instead of going silent.
Authentication & Token Management
Every serious ai voice agent webRTC api uses token-based authentication, and the pattern is consistent across platforms: a JWT is minted server-side from your API key and secret, then presented by the client when joining a session.
The rules matter more than the mechanism. Never embed your API secret in frontend code; it will be extracted. Generate tokens on a server endpoint, keep them short-lived (minutes, not hours), and scope each token to a single room or session so a leaked token cannot be replayed elsewhere. For multi-tenant products, embed the participant's identity and permissions in the token claims so the media layer can enforce access control without a second round trip.
VideoSDK follows this model exactly: tokens are generated server-side, validated on join, and can carry role and permission claims. The same discipline applies whether you use VideoSDK, LiveKit tokens, or any other WebRTC platform, because the underlying security model is shared.
Implementing the API: Step-by-Step Workflow
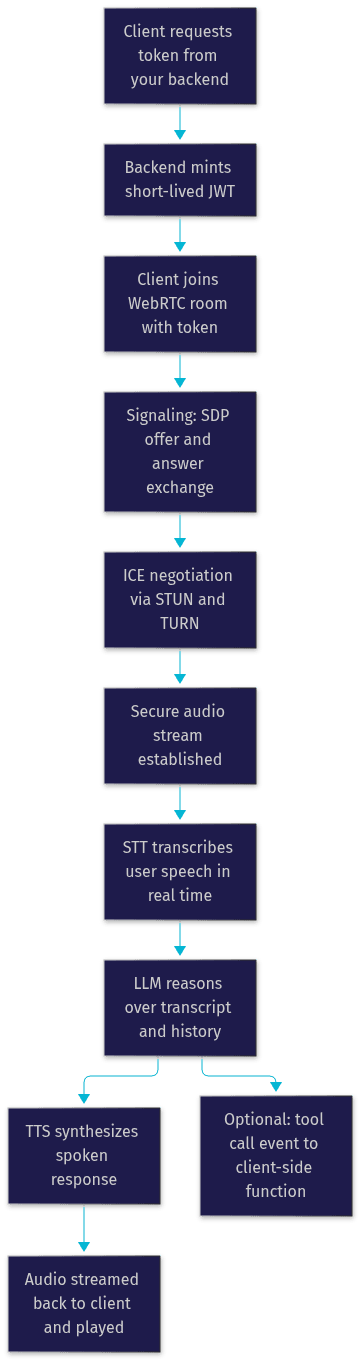
The integration flow for a WebRTC voice agent follows a consistent sequence across platforms: mint a token, negotiate a connection, stream audio through the pipeline, and handle events. Here is how each stage works in practice.
The overall flow looks like this:
1. Server-Side Token Generation
Your backend exposes a secure endpoint that authenticates the user through your normal application auth, then mints a short-lived JWT scoped to the voice session. The token encodes the room identifier, the participant's role, and an expiry. The client receives this token and never sees your API secret. Expect this step to complete in a few milliseconds, since it is a local cryptographic operation.
2. Client-Side Signaling
With the token in hand, the client initiates the WebRTC connection. The client creates a session description (the offer) declaring its audio capabilities and sends it to the signaling endpoint, which responds with an answer from the server side. In parallel, both sides exchange ICE candidates so the connection can find the best network path, using STUN for direct paths and TURN as a relay fallback when NATs or firewalls block direct media. Once negotiation completes, the audio stream is live.
3. Media Pipeline
Once connected, the client's microphone audio flows to the agent worker in continuous frames. The STT engine transcribes it as it arrives, emitting partial results the moment words are recognizable. When turn detection concludes the user has finished, the transcript plus conversation history goes to the LLM, which produces a response. The TTS engine converts that text to audio, streamed back in chunks so playback starts immediately. The user hears the reply while the tail of the sentence is still being synthesized, which is how the best implementations keep perceived latency under a second.
4. Event Handling & Tool Calls
The LLM does not only speak; it can act. When the model decides to check an order status or book an appointment, it emits a function-call event. In VideoSDK's Agent SDK, function tools let the model invoke client-side or server-side logic, and the result is fed back into the conversation so the agent can continue naturally.
Best Practices for Production Deployments
A demo that works on localhost over a wired connection is not a product. Production voice agents fail in specific, predictable ways, and the following practices address them.
Latency tuning comes first. Measure the full round trip: time to final transcript, LLM time to first token, and TTS time to first audio chunk. Enable TTS caching for common phrases like greetings and confirmations, and prefer streaming models over batch ones at every stage. VideoSDK's Agent SDK includes TTS caching and pre-emptive response features specifically to shave these milliseconds.
Security hardening means HTTPS everywhere (browsers refuse microphone access on insecure origins), scoped short-lived tokens, server-side validation of every join, and IP allowlisting for self-hosted deployments. For regulated industries, geo-fencing media routing to specific regions keeps data residency requirements satisfied.
Scaling with Multiple Agents
Scaling a voice agent platform is mostly about worker orchestration. Each concurrent session consumes a dedicated agent worker process holding live STT, LLM, and TTS connections, so you scale horizontally by running more workers behind a load balancer. Multi-tenant deployments should scope tokens per tenant so one customer's traffic cannot touch another's rooms, and you should load-test at your real concurrency target, not your average, because voice traffic spikes hard during campaigns or business hours.
Fallback & Model Versioning
Graceful degradation keeps the agent talking when a provider stumbles. Configure a fallback adapter that switches from your primary LLM to a secondary provider on timeout or error, and pin model versions explicitly rather than accepting whatever a provider's alias currently points to. When a vendor deprecates a model, your versioned configuration makes the migration a deliberate change instead of a silent quality regression.
Monitoring & Debugging
Track four metric families from day one: network health (round-trip time, jitter, packet loss), pipeline latency (each STT, LLM, and TTS stage separately), quality (transcription accuracy on sampled sessions), and engagement (interruption rate and session length). Sudden packet loss spikes usually point to TURN relay fallback; rising LLM latency usually points to provider load. VideoSDK's pipeline observability exposes these stage-level metrics natively.
Real-World Use Cases
Customer support is the flagship scenario. A voice agent answering inbound calls through a WebRTC gateway can authenticate the caller, look up their order through function tools, and resolve routine issues without a human, escalating to a warm transfer when it hits its limits. VideoSDK's telephony integration extends the same agent to SIP trunks and phone numbers, so one agent serves web users and phone callers alike.
Interactive tutorials show the pattern in education. An edtech platform can embed a voice tutor that listens to a student read aloud, corrects pronunciation through real-time STT feedback, and adapts difficulty based on the conversation, all inside the same WebRTC session the platform already uses for live classes.
In-game voice assistants push latency requirements to their extreme. A companion character that responds to spoken commands needs sub-second reactions to feel alive, which is exactly the regime WebRTC streaming was designed for.
On the implementation side, the ecosystem offers multiple entry points. A React frontend can use a hook-based client to capture the microphone and join the agent session, while a FastAPI backend handles token minting and session orchestration. VideoSDK's code samples include ready-made quickstarts for web, React Native, Flutter, and telephony-based agents, so you can start from a working reference rather than a blank editor.
Definitions Glossary
Agent Worker: The Python process that runs a VideoSDK AI agent, managing its session lifecycle and its STT, LLM, and TTS connections inside a WebRTC room.
STT (Speech-to-Text): The model component that converts a user's live audio stream into text, typically emitting partial transcriptions as speech is still in progress.
TTS (Text-to-Speech): The model component that converts an LLM's text response into natural spoken audio, ideally streamed in chunks to minimize perceived latency.
Signaling Endpoint: The server-mediated exchange where WebRTC peers trade SDP offers and answers plus ICE candidates before media can flow directly.
STUN/TURN: The NAT traversal infrastructure in WebRTC. STUN helps peers discover direct network paths; TURN relays media when direct paths are blocked by firewalls or strict NATs.
Meeting Token: A short-lived JWT generated server-side that authenticates a participant's access to a WebRTC room, scoped to a single session and carrying permission claims.
Turn Detection: The mechanism that decides when a user has finished speaking and the agent should respond, distinguishing genuine turn ends from pauses.
Key Takeaways
- An AI voice agent WebRTC API combines low-latency audio transport with a swappable STT, LLM, and TTS pipeline, and WebRTC is the only mainstream transport that keeps spoken conversations under the one-second response threshold.
- Token-based authentication with short-lived, server-minted JWTs is non-negotiable; never expose API secrets in frontend code.
- Modularity is the core architectural value: the best stacks let you swap Deepgram for Whisper or Claude for GPT without touching your client, and fallback adapters keep the agent talking through provider outages.
- Production readiness means stage-level latency monitoring, horizontal worker scaling, model version pinning, and TURN fallback for hostile networks.
- VideoSDK's open-source Agent SDK plus managed WebRTC rooms gives you both control over the pipeline and infrastructure you do not have to run yourself.
Conclusion
Building a production-grade ai voice agent webRTC api is now an integration problem, not a research problem. The winning architecture is consistent: WebRTC for sub-second bidirectional audio, a modular STT, LLM, and TTS chain you can swap as models improve, server-minted tokens for security, and observability at every pipeline stage. Platforms like VideoSDK package this entire pattern, from open-source agent tooling to managed rooms and telephony gateways, so you can focus on your agent's behavior instead of its plumbing. Start with the AI Agents documentation, grab a quickstart from the code samples, and ship your first voice agent on the free tier at app.videosdk.live. What are you building with VideoSDK? Drop a comment, I'd love to hear what kind of voice agent use case you're working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ