


An AI voice agent for automotive is a specialized conversational AI system designed to operate within vehicle environments, enabling hands-free control of infotainment, navigation, and cabin functions. Unlike generic smart speakers, these systems leverage edge AI voice processing and hybrid AI architectures to handle noisy cabin conditions and sub-500ms voice command latency. Developers and OEMs can build and deploy these agents using platforms like VideoSDK AI Voice Agents to ensure driver safety and seamless vehicle integration.
The modern vehicle is no longer just a mode of transportation. It is a rolling computing platform. In 2026, the expectation for a voice-first vehicle UX has shifted from a novelty to a baseline requirement. Drivers want to control climate, navigation, and media without taking their eyes off the road or hands off the wheel. For developers and automotive OEMs, building an AI voice agent for automotive applications presents a unique set of engineering challenges. You are not just building a chatbot. You are building a real-time, safety-critical system that must operate in a high-noise, multi-user environment with strict latency constraints. This guide breaks down the architecture, technologies, and implementation roadmap for deploying production-grade automotive AI assistants.
What is an AI Voice Agent for Automotive?
An AI voice agent for automotive is defined as a voice-controlled AI system specifically engineered to function inside a vehicle cabin. It differs significantly from a generic smart speaker or phone assistant. A standard home assistant operates in a relatively quiet, stationary environment with a single primary user. An automotive AI assistant must contend with road noise, passing traffic, wind, and multiple passengers speaking simultaneously.
These systems work by capturing audio through strategically placed microphones, processing the audio locally or in the cloud, and executing commands that range from adjusting the temperature to finding the nearest charging station. The core differentiator is the deep integration with vehicle hardware. The agent communicates directly with the car's internal networks, translating natural language into mechanical and digital actions. VideoSDK provides foundational real-time communication infrastructure that supports these advanced agent workflows, allowing developers to bridge the gap between raw audio capture and intelligent cloud processing.
Key Benefits for Automakers and Drivers
The adoption of an automotive AI assistant delivers tangible value across the driving experience and the automaker's business model. The most immediate benefit is enhanced safety and reduced distraction. By enabling a robust driver safety voice interface, drivers can keep their hands on the wheel and eyes on the road. Voice commands replace complex touchscreen interactions, reducing the cognitive load required to operate infotainment systems.
Beyond safety, these agents create a highly personalized in-cabin experience. The system can recognize individual voices, recall user preferences, and adjust seat positions, mirror angles, and climate settings automatically. This level of personalization transforms the vehicle into a customized environment.
Automakers also unlock new revenue streams through voice commerce in vehicles. Drivers can order coffee, pay for fuel, or reserve parking spots using natural language commands. This turns the vehicle into a transaction platform. Furthermore, the aggregated, anonymized data from these interactions provides OEMs with data-driven insights into how drivers use their vehicles, informing future design and software updates.
Core Technologies Behind Automotive AI Voice Agents
Building a production-grade in-car voice assistant requires orchestrating several advanced technologies. The system must accurately hear, understand, and act, all within milliseconds.
Speech Recognition (STT)
Speech-to-text automotive processing is the foundational layer. Modern neural STT models must be trained on diverse acoustic data to handle the noisy cabin environment. Unlike a quiet office, a car cabin has variable acoustic profiles depending on speed, road surface, and window positions. Developers use acoustic echo cancellation and noise suppression algorithms to clean the audio feed before it hits the STT engine. Real-time speech recognition is critical. The STT engine must transcribe audio streams with high accuracy, even when the speaker is speaking quickly or using domain-specific vocabulary like specific street names or vehicle function names.
Natural Language Understanding (NLU) & LLMs
Once the speech is transcribed, natural language understanding in cars takes over. Traditional NLU systems relied on rigid intent matching. If a user said a phrase that did not match a predefined template, the system failed. In 2026, large language models (LLMs) have transformed this layer. An LLM-powered automotive AI assistant can handle complex, multi-turn conversations. It can infer intent from context. If a driver says "I am cold," the agent understands the intent is to raise the temperature, not to search for the definition of cold. The LLM generates natural, conversational responses, making the voice-first vehicle UX feel less like a command line and more like a conversation with a co-pilot.
Edge vs. Cloud Processing
The debate between edge and cloud processing defines modern automotive voice architecture. Edge AI voice processing runs the STT and NLU models directly on the vehicle's head unit or a dedicated AI accelerator. This guarantees low latency and functionality even in tunnels or areas without cellular coverage. However, edge hardware has computational limits, making it difficult to run massive LLMs locally. Cloud processing offers near-infinite compute power but introduces network latency and dependency on connectivity. The solution is rarely one or the other. It is a hybrid approach.
Multilingual Support
For global OEMs, multilingual voice AI is a hard requirement. A vehicle sold in Europe might need to understand English, French, German, and Italian seamlessly. Building a multilingual system involves more than translating a lexicon. The STT and NLU models must understand regional accents, dialects, and local colloquialisms. Furthermore, the system must switch languages dynamically based on the driver's profile or manual selection, ensuring the conversational AI for cars feels native to the user.
Data Privacy & Security
In-cabin audio is highly sensitive data. Drivers want the convenience of voice control without feeling surveilled. Privacy-by-design automotive architecture is essential. This means processing wake words and basic commands entirely on-device. When cloud processing is necessary, data must be encrypted in transit. Token-based authentication ensures that only authorized vehicle systems can interact with the cloud backend. OEMs must retain strict data ownership, ensuring that voice data is not used to train third-party advertising models. Developers can use secure token generation services, like those provided by VideoSDK authentication, to manage secure access to cloud-based voice processing pipelines.
Hybrid Architecture: Edge + Cloud
The hybrid AI architecture represents the state of the art for automotive voice agents. In this model, the vehicle handles wake-word detection, basic STT, and local intent extraction on the edge. If the command is simple, like "turn up the volume," the edge processor executes it immediately, ensuring sub-500ms latency. If the query is complex, like "Find a restaurant that serves vegan food and is open right now," the edge system packages the transcribed text and sends it to the cloud. The cloud-based LLM processes the complex intent, queries external APIs, and returns the result. This architecture balances the speed of edge computing with the power of cloud-based AI.
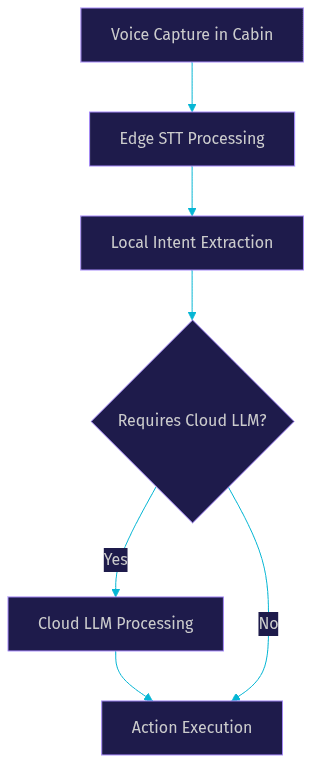
This vertical flow illustrates how a command is routed. Local processing handles immediate safety and comfort functions, while the cloud handles knowledge retrieval and generative tasks. Developers building this architecture can leverage VideoSDK AI Voice Agents to manage the real-time media stream between the vehicle's edge hardware and the cloud-based agent worker.
Design Considerations for In-Car Deployment
Deploying an AI voice agent for automotive requires solving physical and mechanical challenges that software developers rarely face in web or mobile contexts.
Noise Handling & Beamforming
The vehicle cabin is an acoustically hostile environment. Noise handling relies heavily on microphone arrays and beamforming techniques. Beamforming uses multiple microphones to create a directional listening pattern. The system electronically focuses on the sound coming from the driver's seat while rejecting noise from the rear seats or the windows. This spatial filtering is crucial for accurate STT processing at highway speeds.
Latency Requirements (sub-500ms target)
Voice command latency is a critical safety metric. If a driver gives a command and the system takes two seconds to respond, the driver might assume the system failed and repeat the command, leading to conflicting inputs. The target for core vehicle commands is sub-500ms. This means the time from the end of the user's speech to the start of the system's action or response must be under half a second. Achieving this requires highly optimized edge processing and efficient network protocols for cloud fallback.
Wake-Word Customization
Wake-word customization allows OEMs to brand their voice interface. Instead of a generic wake word, an automaker might use their brand name or a specific model name. This requires training a small, highly efficient neural network to detect the specific acoustic pattern of the wake word. This model runs continuously on the edge hardware, listening for the trigger phrase while ignoring other conversations in the cabin.
Multi-User & Seat Detection
A modern vehicle often has multiple occupants. Multi-seat voice detection ensures the system knows who is speaking. By combining beamforming with speaker recognition, the system can restrict certain commands to specific seats. For example, a passenger in the back seat can ask to change the rear climate control, but they cannot unlock the doors or disable the traction control. This seat-level personalization enhances both convenience and safety.
Integration with Vehicle Systems (CAN, APIs)
The final piece of the puzzle is voice AI integration with CAN bus. The Controller Area Network (CAN) bus is the central nervous system of the vehicle. When the AI agent decides to lower the window, it must send a structured message over the CAN bus to the body control module. Developers must build a secure middleware layer that translates the AI agent's intent into the specific CAN message IDs required by the vehicle's hardware. This integration requires close collaboration between software teams and mechanical engineering teams.
Implementation Roadmap
Building and shipping an automotive AI assistant requires a structured approach. Here is a practical AI voice agent deployment roadmap for 2026.
1. Define Use Cases & Success Metrics
Start by defining the exact AI voice agent use cases. Will the system focus on navigation, media control, climate, or a combination? Define success metrics early. These should include voice command latency percentiles, STT accuracy rates in various noise conditions, and user satisfaction scores. Without clear metrics, the project will lack focus.
2. Choose an AI Voice Agent Platform
Select a platform that supports the hybrid architecture you need. Options include specialized automotive platforms like Cerence or SoundHound, or developer-centric platforms like VideoSDK. VideoSDK AI Voice Agents provide an open-source SDK that connects LLMs, STT, and TTS providers to real-time communication channels, making it ideal for building custom automotive assistants. You can review the VideoSDK AI Agents documentation to understand the platform's capabilities.
3. Set Up Secure Token Service & Authentication
Your cloud-based AI agent needs secure access control. Set up a token service that generates short-lived JWTs for authenticating vehicle sessions. Never hardcode API keys in the vehicle's firmware. The vehicle should request a token from your secure backend, which validates the vehicle's identity before issuing the token. This ensures data security in in-cabin AI systems.
4. Train/Customize the Language Model for Automotive Domain
Generic LLMs do not understand vehicle-specific terminology. You need to fine-tune or customize the LLM using automotive domain data. This includes owner's manuals, navigation system documentation, and common driver queries. If you are using a Conversational Graph for deterministic flows, define the nodes and transitions for critical tasks like navigation routing and phone call initiation. Learn more about deterministic flows in the Conversational Graph guide.
5. Conduct Simulated Cabin Testing
Before putting the system in a real car, test it in a simulated environment. Use an acoustic test chamber that mimics the noise profile of a moving vehicle. Test multi-seat voice detection by playing audio from different spatial locations. Measure the voice command latency under simulated highway noise. This stage is critical for catching integration bugs before hardware deployment.
6. Deploy to Edge Hardware and Cloud
Deploy the edge components to your target automotive hardware, such as NVIDIA DRIVE or Qualcomm Snapdragon Automotive platforms. Deploy the cloud components to a scalable infrastructure. If you are using VideoSDK Agent Cloud, you can deploy the agent worker without managing the underlying servers. Ensure the edge and cloud components can communicate securely and reliably over cellular networks.
7. Monitor, Iterate, and Scale
Once deployed, monitor the AI voice agent performance metrics in real-time. Track STT accuracy, intent recognition rates, and latency percentiles. Use this data to identify failure cases and retrain models. Over-the-air (OTA) updates allow you to push improved models and new features to the vehicle fleet without requiring a service center visit.
Real-World Case Studies Overview
Looking at existing deployments provides valuable context for your own build.
Cerence Assistant is a leading OEM voice platform used by major automakers. It relies heavily on a hybrid architecture, processing core commands on-device while leveraging cloud services for complex knowledge retrieval. Its deployment scale spans millions of vehicles globally, proving the viability of large-scale automotive voice deployments.
Mihup AVA focuses on a fully offline, edge-first approach. By running the entire STT and NLU pipeline on the edge, Mihup guarantees zero latency and complete privacy. This architecture is ideal for regions with poor connectivity or for users with strict privacy requirements.
Kardome Spatial Hearing tackles the multi-seat voice detection problem. Their technology uses advanced beamforming to isolate individual speakers in a noisy cabin. By providing a clean audio stream to the STT engine, Kardome significantly improves recognition accuracy for all passengers, not just the driver.
SoundHound OASYS leverages their deep expertise in music recognition to build a conversational AI for cars. Their platform excels at natural language understanding, allowing users to ask complex questions like "What is the weather like at our destination?" without rigid command structures.
Future Trends in Automotive AI Voice Agents
The landscape of in-car voice AI is evolving rapidly. Continual learning on-device will allow the agent to adapt to a specific driver's voice and habits over time, without sending raw audio to the cloud. Multimodal fusion will combine voice with vision. The agent will use camera data to see if the driver is looking at the road or at a passenger, adjusting its response modality accordingly. Federated privacy models will allow OEMs to train global models on aggregated, anonymized data from the fleet without compromising individual user privacy. Finally, voice-first commerce ecosystems will mature, turning the vehicle into a seamless transaction platform for tolls, fuel, and drive-through services.
Definitions Glossary
Edge AI Voice Processing: The execution of speech recognition and natural language understanding models directly on the vehicle's local hardware, ensuring low latency and offline functionality.
Hybrid AI Architecture: A system design where simple, safety-critical voice commands are processed on the edge, while complex, knowledge-intensive queries are routed to cloud servers.
Wake-Word Customization: The ability to train a dedicated neural network to recognize a specific brand or model name as the activation phrase for the voice assistant.
Multi-Seat Voice Detection: The use of microphone arrays and beamforming to identify which passenger in a vehicle is speaking, enabling seat-specific permissions and personalization.
Voice AI Integration with CAN bus: The middleware layer that translates digital intents from the AI agent into mechanical or electronic actions by sending structured messages over the vehicle's Controller Area Network.
Key Takeaways
- An AI voice agent for automotive requires a hybrid architecture that balances the low latency of edge processing with the computational power of cloud-based LLMs.
- Achieving sub-500ms voice command latency is critical for driver safety and user trust, requiring optimized STT and NLU pipelines on local hardware.
- Multi-seat voice detection and beamforming are essential for accurate speech recognition in the noisy, multi-user environment of a vehicle cabin.
- Developers can leverage platforms like VideoSDK AI Voice Agents to build the real-time communication bridge between vehicle hardware and cloud-based AI models.
- Data privacy must be engineered into the system from the start, using token-based authentication and on-device processing for sensitive audio.
Conclusion
The integration of an AI voice agent for automotive applications is a complex but highly rewarding engineering challenge. By adopting a hybrid architecture, focusing on sub-500ms latency, and ensuring robust data security, developers can build systems that significantly enhance driver safety and user experience. The roadmap from defining use cases to simulated cabin testing and final edge deployment requires careful planning, but the tools to execute it are available today. If you are ready to start building, explore the VideoSDK AI Voice Agents documentation and join our Discord community to connect with other developers. What are you building with VideoSDK? Drop a comment below, I would love to hear what kind of automotive voice use case you are working on.
FAQ