


WebSockets for voice streaming is the technique of sending live audio over a persistent, bidirectional WebSocket connection instead of HTTP polling or one-way download protocols. It works by keeping a single long-lived channel open between the client and server, so audio frames flow in both directions with minimal overhead. VideoSDK applies the same principle inside its real-time communication SDKs, where voice rooms and AI voice agents exchange audio with sub-second latency, and you can explore the full architecture in the VideoSDK docs.
Real-time voice has quietly become the interface layer for a huge slice of modern software. Voice bots answer support calls, AI agents hold spoken conversations, contact center supervisors listen in on live calls, and telehealth apps connect doctors to patients with spoken word, not text. What almost all of these systems share is the transport decision underneath them: how do you move raw audio from a microphone to a server, and back, fast enough that a conversation still feels human?
For a growing number of engineering teams, the answer is WebSockets for voice streaming. A WebSocket gives you a persistent, full-duplex channel that stays open for the entire session, which is exactly the shape of a voice conversation. You avoid the request-response overhead of HTTP polling, you can push audio frames the instant they are captured, and the same channel can carry call control messages alongside the media itself.
By the end of this article you will understand how WebSocket voice transport actually works, which architectural patterns fit which use cases, how to pick a codec, how to secure and tune the stream, and how AI voice agents consume WebSocket audio in production.
How WebSockets Enable Voice Streaming
WebSockets enable voice streaming by providing a single persistent channel that carries audio frames in both directions without per-message connection overhead. That single sentence is the core of the whole pattern, and everything else in this article builds on it.
Core WebSocket Mechanics
A WebSocket session begins with an HTTP handshake. The client requests an upgrade, the server agrees, and from that point the connection stops behaving like HTTP and becomes a raw, persistent, full-duplex channel. Both sides can send messages at any time, with no polling loop and no repeated headers.
For audio, this matters for three reasons. First, latency: a captured microphone frame can be written to the socket immediately, rather than waiting for the next HTTP request cycle. Second, efficiency: there is no connection setup cost per message, which matters when you are sending dozens or hundreds of small audio frames per second. Third, symmetry: the server can push audio back down the same channel, so a two-way voice conversation needs exactly one connection per participant.
HTTP polling for audio is effectively dead on arrival for conversational use. Even aggressive polling introduces queuing delay, and the request-response model fights the natural rhythm of speech, where either party may talk at any moment.
Voice-Specific Extensions
Two design decisions dominate voice-over-WebSocket implementations: frame format and codec.
WebSockets support both text frames and binary frames. Voice audio should always use binary frames. Encoding PCM samples as text, such as base64, inflates the payload by roughly a third and adds avoidable encoding and decoding work on both ends. Binary frames carry the raw samples directly, which keeps bandwidth and CPU costs where they should be.
Codec negotiation is the second decision. Common choices include µ-law and A-law (the classic telephony codecs, 8 kHz, 8 bits per sample), linear PCM16 (uncompressed 16-bit samples, typically at 16 kHz for speech recognition), and Opus for higher-fidelity, bandwidth-efficient transport. The right choice depends on where the audio is going: telephony bridges speak µ-law and A-law natively, while most speech-to-text engines expect PCM16 at 16 kHz. Frame sizing is the third lever. Smaller frames mean lower latency but more overhead and more sensitivity to packet loss; larger frames smooth the network but add delay. Voice systems typically settle in the 20 to 100 millisecond range per frame.
Architectural Patterns for Voice Streaming
The architecture you choose for WebSocket voice streaming depends on where the audio originates and how many systems need to consume it. Three patterns cover nearly every production deployment.
Direct Client-to-Server Streaming
In the direct pattern, a web or mobile application captures microphone audio locally and streams it straight to a backend WebSocket endpoint. The browser captures audio through its media APIs, packages it into frames, and writes each frame to the open socket. The server does the reverse for playback.
This pattern is the natural fit for in-app voice features: voice chat inside a product, in-browser voice bots, dictation, and live coaching tools. The client owns the microphone, so you control capture quality, frame size, and preprocessing such as noise suppression before the audio ever leaves the device.
The main architectural responsibility on the server side is session management. Each open socket represents one live voice session, and the server must track which socket belongs to which user, route audio to the right downstream consumer, and clean up reliably when the socket closes. VideoSDK's Rooms-based architecture handles this shape natively: participants join a room, and their audio tracks are routed to other participants, recorders, or AI agents without you building the fan-out yourself. You can see this in the VideoSDK audio calling guide.
SIP/Telephony Bridge to WebSocket
Not all voice starts in your app. A large share of real-world voice traffic still arrives over the phone network, via SIP trunks and PSTN calls. The bridge pattern converts that telephony audio into a WebSocket stream your software can process.
Providers such as Telnyx, SignalWire, and Wavix expose this as a media streaming feature: you point your phone number's call handling at a WebSocket endpoint you control, and the provider forwards the call's audio frames to that endpoint over a secure WebSocket while the call is live. Your server receives telephony-coded audio (usually µ-law or A-law at 8 kHz), processes it, and can send audio back to be played into the call.
This pattern is the backbone of AI phone agents. The caller dials an ordinary number, the bridge converts the call into a WebSocket stream, and your AI stack consumes it exactly as if the audio came from an app. VideoSDK's telephony integration takes the same idea further, bridging SIP calls directly into VideoSDK rooms where AI agents and human participants can coexist.
Multi-Stream Fan-Out
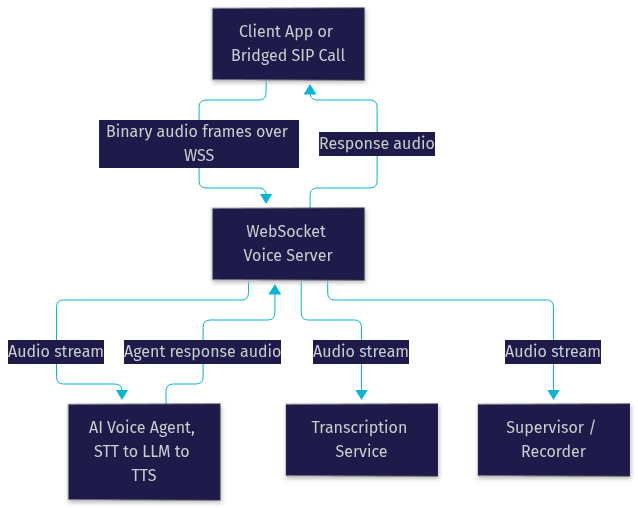
In production, one audio stream rarely goes to one place. The same live audio often needs to reach a transcription service, an AI agent, a recorder, and a human supervisor simultaneously. Multi-stream fan-out means the WebSocket server, or the room infrastructure behind it, duplicates the incoming stream to every subscribed consumer. This is where a room-based architecture pays off: fan-out, ordering, and cleanup become platform features rather than code you maintain.
The diagram below shows the full picture: a client (or a bridged phone call) streaming over a WebSocket into a server, which fans the audio out to an AI agent, a transcription service, and a supervisor listening in.
Choosing the Right Codec and Audio Format
Codec choice determines bandwidth, latency, and whether downstream consumers can actually read your audio. The wrong codec is the single most common cause of "the agent hears silence" bugs.
Uncompressed PCM16 at 16 kHz is the default for AI voice pipelines. Most speech-to-text engines, including those used by VideoSDK's AI voice agents, are trained on 16 kHz linear PCM, so sending it directly avoids a transcoding step. µ-law and A-law are the telephony standards: if your audio arrives from a SIP bridge, it will almost certainly be one of these, and you will need to convert it before feeding a speech model. Opus is the choice when bandwidth is constrained or fidelity matters, such as music or multi-party voice rooms, at the cost of encode and decode work on both ends.
| Codec | Sample rate | Bitrate (approx.) | Typical use case |
|---|---|---|---|
| PCM16 | 16 kHz | 256 kbps | AI voice agents, STT pipelines |
| µ-law | 8 kHz | 64 kbps | North American telephony, SIP bridges |
| A-law | 8 kHz | 64 kbps | European telephony, SIP bridges |
| Opus | 6 to 48 kHz | 6 to 510 kbps | Bandwidth-constrained apps, high-fidelity voice rooms |
The practical rule: match the codec to the consumer, not to the network. Transcoding on the server is cheap and routine; a speech model that cannot decode your format is a hard failure.
Implementing Secure, Low-Latency Streams
A working prototype over plain WebSockets is easy. A production voice stream needs three things the prototype usually skips: encryption, latency tuning, and resilient reconnection.
TLS/WSS Enforcement
Voice is biometric data. A spoken conversation can identify the speaker, leak personal details, and in contact centers often contains payment information. Transporting it over an unencrypted WebSocket is a compliance failure waiting to happen.
The fix is WSS, WebSockets over TLS. It is the standard secure variant, it is required by browsers on HTTPS pages anyway, and there is no meaningful performance penalty on modern hardware. Enforce it at the edge: reject plain WebSocket upgrade requests in production, terminate TLS at your load balancer or CDN, and treat any plain-text voice endpoint as a defect. Enterprise deployments should also look at IP whitelisting and geo-fencing on the voice infrastructure itself, both of which VideoSDK supports for its real-time media endpoints.
Frame Buffering and Latency Tuning
Latency in a voice stream is dominated by frame duration and jitter buffering. Frame duration is how much audio you pack into each message: 20 millisecond frames feel instant but multiply message overhead, while 100 millisecond frames are efficient but add a perceptible floor to round-trip delay.
The jitter buffer is the counterweight. Networks deliver frames at irregular intervals, so the receiving side holds a small buffer of incoming audio and plays it out at a steady rate. A deeper buffer absorbs more network jitter and packet loss, but adds direct latency. A shallower buffer feels snappier but stutters when the network wobbles.
For conversational voice, target end-to-end latency under about 300 milliseconds, the threshold beyond which people start talking over each other. In practice that means 20 to 40 millisecond frames with a modest adaptive jitter buffer, and letting the infrastructure adapt to real-time bandwidth conditions rather than fixing parameters statically. VideoSDK's network-adaptive streaming does exactly this for its voice and video rooms, adjusting bitrate and frame handling as conditions change.
Reconnection and Error Handling
Sockets drop. Mobile clients change networks, laptops sleep, load balancers time out idle connections. A production voice client needs an automatic reconnection strategy with exponential back-off: retry immediately, then progressively slower, capped at a reasonable interval, so a transient blip is invisible while a real outage does not hammer your server.
Two details separate robust implementations from fragile ones. First, resume rather than restart: carry a session identifier so the server can reattach the reconnected client to its existing room or call state instead of creating a new session. Second, surface status: give the UI clear connected, reconnecting, and failed states, and use the WebSocket's close codes to distinguish clean shutdowns from errors. Server-side, treat socket closure as a first-class event that triggers cleanup of the session's downstream consumers, recordings, and agent processes.
Integrating AI Voice Agents over WebSockets
AI voice agents are the biggest driver of WebSocket voice streaming adoption, because the entire agent pipeline, speech-to-text, an LLM, and text-to-speech, is a streaming system that wants audio in and audio out continuously.
Protocol Adapters
You do not have to build the bridge between your WebSocket audio and an AI model yourself. An ecosystem of protocol adapters already exists. Twilio Media Streams forwards live call audio to your WebSocket endpoint. OpenAI's Realtime API accepts streaming audio and returns streaming speech over a persistent connection. Deepgram and AssemblyAI both accept real-time audio streams and return live transcripts. Each adapter defines its own expectations for codec, sample rate, and framing, so your job is mostly format plumbing.
VideoSDK's open-source AI Agent SDK sits in this same layer, but goes further: it connects your choice of STT, LLM, and TTS providers into a single managed pipeline running inside a VideoSDK room, so the agent joins as a participant and speaks with users over the same real-time infrastructure. The agent documentation covers the full component model, including turn detection, function tools, and call transfer.
Turn-Taking and VAD
Natural conversation depends on knowing when someone has finished speaking. Voice activity detection, or VAD, solves this by analyzing the incoming audio stream and signaling speech start and speech stop events. The agent pipeline uses those signals to decide when to stop listening and start responding, and to support interruption: when the user speaks again mid-response, the agent should stop its TTS playback and listen.
Without VAD, an agent either waits for fixed timeouts (feeling slow and robotic) or responds to every silence gap (interrupting constantly). Modern implementations combine VAD with semantic turn detection, where the LLM itself judges whether the user's utterance is complete. VideoSDK's agent pipeline includes both, along with configurable turn detection sensitivity.
PCI/PII Masking
One governance detail that is easy to miss: when a caller reads out a credit card number, that audio is heading straight for third-party AI providers. Compliance-aware pipelines redact or mask sensitive segments before they leave your infrastructure, either by muting the stream during detected payment flows, or by keeping sensitive audio on-premise and sending only the redacted transcript upstream. Design this in from the start; retrofitting redaction into a live audio pipeline is painful.
Monitoring and Metrics
You cannot tune what you do not measure, and voice quality problems are notoriously hard to diagnose from user complaints alone. Four metrics cover most of what matters.
Time-to-first-audio measures how long from session start until the first audio frame flows, which captures handshake, authentication, and media setup cost combined. Round-trip latency measures the full loop: user speech captured, processed by the agent, and response audio played back. Packet and frame loss measures how much audio never arrives or arrives too late to be useful. Jitter measures the variance in inter-frame arrival time, which predicts buffer underruns before users feel them.
Expose these through your existing observability stack. Prometheus counters and histograms per session, aggregated by region and client type, will surface patterns like a single cloud region with elevated latency or a mobile client version with a reconnection bug. If you are running on managed infrastructure, use the built-in session analytics rather than rebuilding them: VideoSDK's REST APIs expose per-session participant and quality data you can pull into your own dashboards.
Common Pitfalls and How to Avoid Them
Most WebSocket voice streaming failures fall into a short list of recurring mistakes.
Codec mismatch is the champion: the bridge sends µ-law, the speech model expects PCM16, and the result is silence or garbage. Fix it by validating the format at session setup and transcoding at the edge. Firewall and proxy blocking is next: some corporate networks and proxies mishandle WebSocket upgrades or long-lived WSS connections. Fix it by testing against real corporate networks, using standard ports, and falling back to a relay when upgrades fail. Audio drift, where playback slowly desynchronizes from capture, appears in long sessions when frame timestamps are ignored; fix it by timestamping frames and pacing playback against the capture clock. Text-frame encoding, base64-wrapping audio out of convenience, silently costs a third of your bandwidth; use binary frames. And finally, missing reconnection logic turns every transient network blip into a dropped call; build back-off and session resume in from day one.
Definitions Glossary
WebSocket: A persistent, full-duplex communication channel that begins as an HTTP upgrade handshake and then stays open, allowing both client and server to send messages at any time without repeated requests.
WSS: WebSockets over TLS, the encrypted variant of the protocol. It is mandatory for transporting voice data in production because spoken audio is sensitive personal and often biometric information.
PCM16: Uncompressed 16-bit linear pulse-code-modulated audio, typically sampled at 16 kHz. It is the standard input format for most speech-to-text engines and AI voice agent pipelines.
Voice Activity Detection (VAD): The mechanism that analyzes an incoming audio stream and signals when speech starts and stops, enabling natural turn-taking and interruption handling in AI voice agents.
Jitter Buffer: A small playback buffer on the receiving side of a voice stream that absorbs irregular network delivery, trading a fixed amount of latency for smoother, gap-free audio playback.
SIP-to-WebSocket Bridge: A telephony component that converts live SIP or PSTN call audio into a WebSocket stream, letting software and AI agents process ordinary phone calls in real time.
Key Takeaways
- WebSockets for voice streaming work because a single persistent, full-duplex channel matches the shape of a conversation: both parties can send audio at any time with no per-message overhead.
- Always use binary frames for audio; base64 or text encoding inflates bandwidth by roughly a third and adds needless CPU cost on both ends.
- Match your codec to the consumer: PCM16 at 16 kHz for AI pipelines, µ-law or A-law for telephony bridges, Opus when bandwidth or fidelity drives the decision.
- Production voice streams require WSS encryption, 20 to 40 millisecond frames with an adaptive jitter buffer, and automatic reconnection with exponential back-off and session resume.
- AI voice agents are the dominant consumer of WebSocket audio, and platforms like VideoSDK's AI Agent SDK manage the full STT, LLM, and TTS pipeline inside a real-time room alongside human participants.
Conclusion
WebSockets for voice streaming have become the default transport for real-time audio because they get the fundamentals right: one persistent channel, bidirectional flow, binary frames, and latency low enough for natural conversation. The engineering work is in the details, codec matching, jitter buffering, secure WSS enforcement, and resilient reconnection, and each of those is a solved problem once you know the patterns.
If you are building a voice application, start with the VideoSDK quickstart to see room-based audio in action, then explore the AI agents documentation for voice agent pipelines, or the telephony guide for bridging phone calls into your app. You can create a free account at app.videosdk.live and prototype today. What are you building with real-time voice? Drop a comment, I would love to hear what kind of voice streaming use case you are working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ