


WebRTC for voice agents is the practice of using the browser-native real-time communication protocol to stream full-duplex audio between a user and an AI pipeline of speech-to-text, an LLM, and text-to-speech. WebRTC delivers sub-500ms round-trip audio, built-in encryption, and firewall traversal, which makes it the transport layer of choice for interruptible, low-latency voice AI. VideoSDK's AI Agent SDK builds on this foundation, connecting STT, LLM, and TTS providers to managed WebRTC rooms.
Voice-first AI has moved from demo to production. In 2026, users expect to open a browser tab or tap a phone number and hold a natural, interruptible conversation with an AI agent, not wait through the five-second round trips of legacy telephony or HTTP polling. That expectation puts enormous pressure on the transport layer, and this is exactly where WebRTC for voice agents earns its place as the backbone of real-time voice AI.
The reason is simple: WebRTC was engineered for live human conversation, with sub-second media delivery, continuous two-way audio, and encryption by default. Those same properties are what a voice agent needs to feel alive. By the end of this article, you will understand the core WebRTC concepts, the full architecture of a voice agent pipeline, the session lifecycle from token to teardown, and the best practices that separate a laggy prototype from a production-grade conversational agent.
What is WebRTC and How It Powers Voice Agents?
WebRTC is defined as a free, open standard and API set that enables real-time audio, video, and data exchange directly between peers, typically a browser and a media server. WebRTC works by negotiating a media connection through a signaling handshake, traversing networks with ICE, STUN, and TURN, and then streaming encrypted audio over a dedicated channel that bypasses the ordinary HTTP request-response cycle.
Core WebRTC Concepts
WebRTC's peer-to-peer media model means audio flows over the shortest viable path rather than through a chatty application server. ICE is the framework that gathers every possible network route to the remote peer. STUN servers help a peer discover its public network address, while TURN servers act as encrypted relays when direct paths fail, such as behind strict corporate firewalls. Data channels run alongside media, carrying low-latency messages like transcripts, agent state, or UI events. Together these pieces give voice agents a transport that behaves like a phone call but runs on web infrastructure.
Why WebRTC Is Ideal for Voice Agents
Four properties make WebRTC the default choice for real-time voice agents. First, latency: media flows over UDP with congestion control tuned for live conversation, typically achieving round-trip audio well under half a second. Second, full-duplex streaming: the user and the agent can speak simultaneously, which is essential for natural barge-in behavior. Third, browser compatibility: every modern browser ships WebRTC support, so a voice agent needs no plugin or native install. Fourth, security: all WebRTC media is encrypted via SRTP by default, so voice data is protected end to end without extra engineering. For a deeper treatment, the W3C WebRTC specification is the authoritative reference.
Architecture of a WebRTC-Based Voice Agent
A WebRTC voice agent architecture connects a browser client to a server-side pipeline through a managed media connection, with each stage adding latency that must be budgeted carefully. The browser captures microphone audio and streams it into a WebRTC room; a server-side agent worker pulls that audio, transcribes it, reasons over it with an LLM, and returns synthesized speech on the same connection.
High-Level Component Diagram
The diagram below shows the canonical flow: the browser client joins a WebRTC room after token authentication, the agent worker consumes the audio stream, and the STT, LLM, and TTS stages form the reasoning pipeline. An optional digital-human avatar stage can render the agent's speech as a talking video track delivered back over the same WebRTC connection.
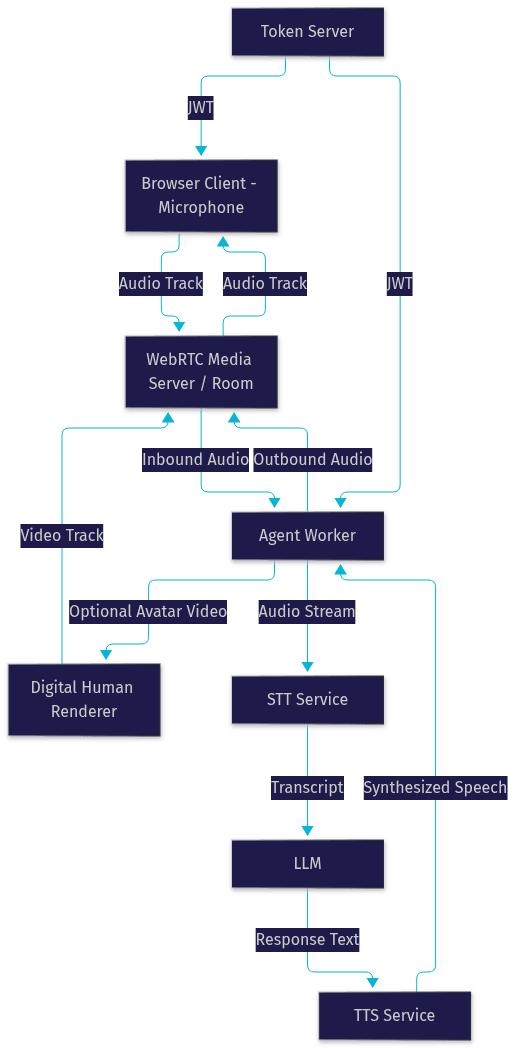
The critical design decision is where the agent worker runs. Keeping transcription, reasoning, and synthesis in one colocated process minimizes the hops between stages, because every network jump between STT, LLM, and TTS adds tens to hundreds of milliseconds. Platforms like VideoSDK's Agent Cloud host this worker for you, or you can self-host it with Docker and Kubernetes.
Session Lifecycle Step-by-Step
A voice agent session follows a predictable lifecycle. First, token acquisition: the client requests a short-lived JWT from your token server, which authenticates it against a specific room and role. Second, room creation and join: the room exists as the media hub, and the client attaches its microphone track. Third, media negotiation: ICE candidates are exchanged through signaling, and an encrypted audio path is established. Fourth, the conversation loop: turn detection monitors the inbound stream, the pipeline transcribes, reasons, and speaks, and interruptions cancel in-flight speech. Fifth, cleanup: when the user leaves, the room emits a participant-left event, your worker finalizes the transcript, and the session state is persisted for analytics. Handling this lifecycle gracefully, especially mid-call disconnects and reconnection, is what separates production agents from demos.
Building Blocks: Key Technologies and Open-Source Projects
The WebRTC voice agent ecosystem in 2026 is mature enough that you rarely build from raw peer connections. You assemble from libraries, speech services, and agent frameworks.
WebRTC Libraries and SDKs
LiveKit is a popular open-source WebRTC stack with server, client, and agent components. OpenAI's Agents SDK provides transport-agnostic agent primitives that pair well with WebRTC media. VideoSDK offers a managed WebRTC room layer with SDKs across JavaScript, React, Python, and mobile platforms, plus an open-source agents SDK on GitHub that handles the room-to-pipeline wiring for you. Each of these handles signaling, ICE, and reconnection so you can focus on conversation logic.
Speech-to-Text and Text-to-Speech Services
On the STT side, Deepgram's streaming models, OpenAI Whisper, Google Cloud STT, and AssemblyAI all offer real-time transcription endpoints suited to live audio. For TTS, ElevenLabs leads on naturalness, with OpenAI TTS, Google Cloud TTS, Azure Speech, and Cartesia offering strong streaming alternatives. The key selection criterion for both is streaming behavior: you want partial transcription results and chunked synthesis, not batch responses, because batch round trips destroy the latency budget. Verify current model names and pricing before committing, since this market moves quickly.
Agent Frameworks That Already Use WebRTC
Several frameworks have converged on WebRTC as their default transport. Pipecat is an open-source Python framework for voice agent pipelines with WebRTC transport support. Mastra offers live voice agent tooling with WebRTC integration for TypeScript developers. VideoSDK's Agent SDK provides the full pipeline with turn detection, barge-in, TTS caching, and multi-agent switching built in, plus a Conversational Graph layer for deterministic flows like loan applications or appointment booking. The pattern across all of them: you describe the pipeline, and the framework manages the WebRTC session.
Implementation Guide: Creating Your First WebRTC Voice Agent
This walkthrough explains the full implementation path in plain language, covering what each step does and why it matters. The same flow applies whether you use VideoSDK, LiveKit, or a custom stack.
Prerequisites
You need a JavaScript or Python runtime for the client and worker, API keys for your chosen STT and TTS providers, and an account with your WebRTC platform of choice. Decide upfront whether your agent worker runs on a managed cloud or self-hosted containers, because that choice shapes your token server and scaling story. Budget roughly 300 milliseconds for the full voice-to-voice loop; every component choice should be evaluated against that budget.
Step 1: Set Up Signaling and Room Tokens
WebRTC connections require signaling, the exchange of connection metadata before media can flow. Your first step is a token endpoint on your server that authenticates the user and issues a short-lived JWT scoped to a specific room and participant role. The client then uses that token to join the room, and the room handles the underlying offer-and-answer negotiation and ICE candidate exchange. Never issue tokens from the client or embed long-lived secrets in frontend code; tokens should expire within minutes and be scoped to a single session. VideoSDK's authentication guide covers this pattern in detail.
Step 2: Capture and Stream Microphone Audio
Once joined, the client requests microphone access through the browser's media permission prompt and publishes the audio as a WebRTC track into the room. The expected behavior: the user grants permission once, and their voice streams continuously to the room without further interaction. On the worker side, voice activity detection monitors the stream so silence is not transcribed and the agent knows when the user has actually finished speaking rather than merely pausing. Handle the permission-denied case gracefully with a clear fallback message, since it is one of the most common failure points in browser-based voice agents.
Step 3: Connect STT, LLM, and TTS
The agent worker subscribes to the inbound audio track and pipes it to your streaming STT service, which returns partial and final transcripts. Each final transcript becomes user input to the LLM, which produces the agent's response text. That text feeds the TTS engine, whose synthesized audio publishes back to the room as an outbound track the user hears in real time. The important architectural point: keep these three stages as close together as possible, ideally in the same worker process, because inter-service network hops are the largest avoidable latency source.
Step 4: Handle Interruptions (Barge-In)
Natural conversation means users interrupt. When voice activity detection detects user speech while the agent is talking, the worker should immediately cancel the in-flight TTS playback, stop synthesizing the remainder of the response, and begin transcribing the user's new utterance. This cancel-and-listen behavior is what makes an agent feel responsive rather than robotic. VideoSDK's agent pipeline implements this natively through its turn detection and speech handle mechanisms.
Step 5: Deploy and Scale
For production, containerize the agent worker and orchestrate it with Kubernetes so worker instances scale with concurrent sessions. Use a room-per-session model so each conversation gets isolated media and state, and let your orchestration layer spin workers up and down as rooms are created and destroyed. Multi-region deployment of both the media layer and the worker layer keeps latency low for geographically distributed users. VideoSDK supports both managed Agent Cloud deployment and self-hosted Docker and Kubernetes options.
Best Practices and Performance Tips
Latency is the product metric for voice agents, and every practice here serves it.
Reducing Latency
Use STT and TTS services with edge or regional endpoints close to your media server, because cross-continent speech calls add hundreds of milliseconds per round trip. Keep media packets small and favor hardware-accelerated audio codecs like Opus, which WebRTC negotiates by default and which is highly efficient for voice. Enable streaming transcription and chunked synthesis so the agent can begin speaking before the full response is generated. Finally, cache common TTS outputs, such as greetings and standard phrases, so repeated utterances play instantly.
Security Considerations
Treat every voice session as sensitive data. Enforce short token expiration with room-scoped claims, run all signaling over TLS, and require authentication on your TURN servers so they cannot be abused as open relays. Log transcripts with user consent and store them encrypted. For regulated industries, consider geo-fencing media routing to keep voice data within jurisdiction boundaries, a capability VideoSDK supports natively.
Monitoring and Cost Management
Track session minutes, transcription volume, and synthesis volume per session, because STT and TTS are metered services and runaway loops can inflate bills fast. Set usage caps and alerts at the session and account level. Log transcript metadata, such as turn count, interruption frequency, and latency per turn, because these metrics reveal both cost anomalies and conversation quality problems before users complain.
Real-World Use Cases
WebRTC voice agents are already deployed across several high-value scenarios. Customer support agents handle first-line triage on websites, deflecting routine tickets while escalating complex ones to humans with full transcript context. Virtual assistants act as voice interfaces for internal knowledge bases, letting employees ask questions hands-free. Digital-human agents pair the WebRTC audio pipeline with a rendered avatar video track for brand-facing experiences in retail and education. Tele-health triage agents collect symptoms and schedule appointments, where WebRTC's encryption and low latency are non-negotiable. Outbound AI phone agents extend the same pipeline to the telephone network through SIP integration, which VideoSDK's telephony support provides out of the box.
Definitions Glossary
WebRTC: An open standard and browser API for real-time, encrypted audio, video, and data exchange between peers, forming the transport layer for live voice agents.
ICE, STUN, and TURN: The WebRTC connectivity framework. ICE gathers network routes, STUN discovers public addresses, and TURN relays media when direct connections fail behind firewalls.
Agent Worker: The server-side process that subscribes to a WebRTC room's audio, runs the STT, LLM, and TTS pipeline, and publishes the agent's speech back to the room.
Barge-In: The ability of a user to interrupt a speaking agent, triggering cancellation of in-flight speech synthesis and immediate re-listening.
Turn Detection: The mechanism, usually voice activity detection based, that decides when a user has finished speaking and the agent should respond.
Room: A WebRTC media hub that participants, including AI agents, join to exchange streams, managed in VideoSDK through SDKs and REST APIs.
Key Takeaways
- WebRTC provides the four properties real-time voice agents require: sub-second latency, full-duplex audio, browser compatibility, and encryption by default.
- The canonical architecture is a browser client, a token-authenticated WebRTC room, and a colocated agent worker running the STT, LLM, and TTS pipeline.
- Barge-in handling, canceling in-flight speech the moment the user speaks, is the single biggest factor in making an agent feel natural.
- Token security, TLS signaling, TURN authentication, and transcript handling are mandatory for production voice deployments.
- VideoSDK's AI Agent SDK and Agent Cloud handle the WebRTC room layer, turn detection, and pipeline wiring so you can focus on conversation logic.
Conclusion
WebRTC for voice agents is the foundation that makes real-time, interruptible, human-quality AI conversation technically achievable in a browser. The architecture is well understood, the speech services are mature, and the frameworks, from Pipecat to VideoSDK's open-source agents SDK, mean you can ship a working agent in days rather than months. Start with the VideoSDK AI Agents documentation, grab a free tier at app.videosdk.live, and join the VideoSDK Discord community to compare notes with other builders. What are you building with WebRTC voice agents? Drop a comment, I'd love to hear what kind of voice-first use case you're working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ