


A reflexive agent is an AI system that maintains an internal self-model, reflects on its past actions and outcomes, and adjusts future behavior based on that introspection. Unlike standard LLM agents that respond to prompts without self-awareness, reflexive agents store episodic memories, convert feedback into natural-language summaries, and evaluate their own confidence before acting. This metacognitive pattern, sometimes called verbal reinforcement learning, enables continuous self-improvement without weight updates. VideoSDK's AI Voice Agent SDK supports similar introspective patterns through its pipeline hooks and session observability features, allowing developers to build agents that learn from each interaction.
Introduction
AI agents have moved beyond simple prompt-response pipelines. Developers building production systems in 2026 increasingly need agents that can look at their own performance, recognize where they went wrong, and do better next time. That capability sits at the heart of what researchers now call a reflexive agent.
The concept draws from metacognitive AI research, where the agent doesn't just act but also reflects on its actions. Think of it as the difference between a developer who writes code and ships it immediately versus one who reviews their own pull request, notes what worked, and keeps a personal log of mistakes to avoid. The second developer improves over time. The first one repeats the same errors.
Reflexive agents matter because they address a fundamental limitation of large language models: without weight updates, an LLM has no mechanism to learn from its mistakes across sessions. A reflexive loop layers that learning on top of the model by capturing outcomes, summarizing them in natural language, and feeding those summaries back into future prompts. This approach, known as verbal reinforcement learning, turns every interaction into a training signal without touching model parameters.
For developers building autonomous systems, voice agents, or coding assistants, this pattern dramatically improves reliability. Instead of hoping the model gets it right, you engineer a system that catches its own errors and adapts.
What Is a Reflexive Agent?
A reflexive agent is defined as an AI agent that maintains a structured self-model and uses introspective reflection to guide its decision-making process. The agent doesn't just execute tasks. It evaluates its own capability to execute those tasks, records what happened, and uses that record to inform future actions.
Standard LLM agents operate in a feed-forward pattern: prompt comes in, response goes out, context resets. A reflexive agent breaks that cycle by inserting a reflection phase between action and the next prompt. After taking an action and observing the outcome, the agent generates a natural-language summary of what went well, what failed, and what it should do differently. That summary gets stored in an episodic memory buffer and retrieved when a similar situation arises.
The core idea is self-model-driven decision making. The agent maintains a representation of its own capabilities, confidence levels, and known limitations. Before attempting a task, it consults this self-model to decide whether it can handle the request, whether it should ask for clarification, or whether it should delegate to another system. This is what researchers call capability-aware behavior, and it separates reflexive agents from their non-reflexive counterparts.
VideoSDK's Conversational Graph touches on a related concept: instead of letting the LLM freely control conversation flow, developers define structured states and transitions. A reflexive agent adds another layer by letting the agent itself evaluate whether it handled each state well.
Core Components of Reflexive Agents
Reflexive agents rely on four interconnected components that form a closed loop between action, observation, and adaptation. Each component plays a distinct role in enabling the agent to learn from its own behavior without requiring model retraining.
Episodic Memory Buffer
The episodic memory buffer is the storage layer where a reflexive agent keeps records of past actions, outcomes, and reflections. Each entry typically includes the original task or prompt, the action the agent took, the result or feedback received, and the natural-language reflection the agent generated about that experience.
Think of it as a structured journal. When the agent encounters a new task, it queries this buffer for relevant past episodes using semantic similarity or keyword matching. If the agent previously failed at a similar task and recorded why, that reflection becomes part of the context for the new attempt. The buffer needs careful management: too many entries and the context window overflows, too few and the agent loses valuable learning. Developers typically implement pruning strategies that keep high-signal reflections and discard routine successes.
Verbal Feedback Loop
The verbal feedback loop converts feedback signals into natural-language summaries that the LLM can reason about. Feedback can come in many forms: a scalar reward from an environment, a success or failure flag from a test suite, or free-form text from a human user. The reflexive agent transforms all of these into a consistent verbal format.
For example, if a code generation agent writes a function that fails three unit tests, the verbal feedback loop converts those test failures into a summary like "The generated function failed to handle empty input arrays, causing a null reference error. Future implementations should include input validation for edge cases." This natural-language summary is far more useful to an LLM than a raw error code or a negative reward signal.
Self-Model Representation
The self-model is a structured artifact that captures what the agent knows about its own capabilities. It includes a list of skills or task types the agent can handle, confidence scores for each skill, known failure modes, and limitations the agent has discovered through past experience.
This isn't just a static configuration file. The self-model evolves as the agent accumulates reflections. If the agent notices it consistently fails at tasks involving a particular API or domain, it lowers its confidence score for that category. If it succeeds repeatedly at a task type, its confidence rises. This dynamic self-assessment enables the agent to make informed decisions about whether to attempt a task, ask for help, or decline entirely.
Goal Alignment Mechanism
Before taking action, a reflexive agent compares its current state to the desired goal state. This goal-state reflection prevents the agent from charging ahead with an action that might be technically correct but contextually wrong. The agent asks itself: does this action move me closer to the goal? Have I made progress since the last step? Is there a better path?
This mechanism is particularly valuable for multi-step tasks like web navigation or complex code generation. Without it, agents can get stuck in loops, repeating the same failed action. With it, the agent recognizes it isn't making progress and tries a different approach.
How Reflexive Agents Learn from Feedback
Learning from feedback is the mechanism that makes reflexive agents improve over time. The process involves receiving feedback, transforming it into a usable format, and retrieving relevant past reflections when needed. Each stage shapes how effectively the agent adapts.
Scalar vs. Free-Form Feedback
Feedback comes in two broad categories, and each has different implications for agent learning. Scalar feedback provides a numerical signal: a reward score, a pass or fail flag, a latency measurement. It's compact and easy to aggregate but carries no diagnostic information. The agent knows it failed but not why.
Free-form feedback, such as a human user explaining what went wrong or a test framework outputting error messages, is richer but harder to process consistently. Reflexive agents benefit from a hybrid approach: use scalar signals to trigger reflection and free-form text to populate the reflection content. When a scalar signal indicates failure, the agent probes the environment or asks the user for more detail, then synthesizes both into a verbal summary.
Incorporating Feedback into Context
Once the agent generates a verbal summary of the feedback, that summary needs to enter the context window for the next LLM call. The typical approach is to prepend relevant reflections to the system prompt or insert them as additional context blocks before the user's new request.
The key challenge is context window management. If every reflection from every past episode gets included, the prompt grows unmanageably long. Developers solve this by selecting only the most relevant reflections based on semantic similarity to the current task, recency, and impact score. Some implementations use a separate retrieval step that ranks stored reflections and includes only the top few.
This is where the verbal reinforcement learning pattern becomes concrete. The LLM doesn't just see the new prompt. It sees the new prompt plus a curated set of lessons learned from similar past situations. Those lessons shape the response without any model weight changes.
Episodic Memory Retrieval
Retrieving the right reflections at the right time is what separates a useful reflexive agent from one that drowns in its own memory. The retrieval strategy matters as much as the storage strategy.
Common approaches include semantic similarity search using embeddings, where the current task description is compared against stored episode descriptions to find the closest matches. Another approach is recency-weighted retrieval, which prioritizes recent reflections on the assumption that they reflect the agent's current capability level. Some systems combine both, retrieving reflections that are both semantically relevant and recent.
A more sophisticated approach involves impact-based filtering, where reflections are tagged with an impact score based on how much the outcome deviated from expectations. High-impact reflections, whether positive or negative, get retrieval priority because they carry the most learning signal.
Designing and Implementing a Reflexive Agent
Building a reflexive agent requires thoughtful design across four areas: the capability model, the reflection prompt, memory lifecycle management, and integration with existing LLM pipelines. Each area presents specific decisions that shape how well the agent learns and adapts.
Defining the Capability Model
Start by enumerating the tasks your agent is expected to handle. For a coding assistant, this might include categories like writing functions, debugging existing code, explaining algorithms, and generating tests. For a voice agent built on VideoSDK's AI Voice Agent SDK, categories might include answering factual questions, booking appointments, transferring calls, and handling edge-case queries.
For each category, assign an initial confidence score. These scores don't need to be precise. They serve as a starting point that the reflexive loop will adjust over time. The agent should also track known limitations: tasks it has consistently failed at, domains where it produces unreliable output, and scenarios where it tends to hallucinate.
The capability model should be serializable and versioned. As the agent learns, the model changes, and you want to be able to inspect what the agent believes about itself at any point. This is also valuable for debugging: if the agent starts refusing tasks it should be able to handle, you can check whether its confidence scores have drifted too low.
Building the Reflection Prompt
The reflection prompt is the instruction that tells the LLM to analyze its own performance after an action. This prompt needs to elicit honest, specific, and actionable self-analysis rather than generic statements.
A well-designed reflection prompt asks the agent to address specific questions: What was the intended outcome? What actually happened? What was the gap between intention and result? What specific change would improve performance next time? Is this a recurring failure pattern or a one-off issue?
The prompt should also constrain the output format. Free-form reflections are harder to retrieve and use later. A structured format that includes a task category tag, a success or failure indicator, a brief description of what happened, and a specific lesson learned makes the memory buffer far more useful.
Managing Memory Lifecycle
Reflections accumulate quickly. Without active management, the episodic memory buffer becomes a liability rather than an asset. Three lifecycle operations keep it healthy: expiration, pruning, and versioning.
Expiration policies remove reflections older than a certain age, on the assumption that they may no longer reflect the agent's current capabilities or the current state of the environment. Pruning removes low-value reflections to keep the buffer within a target size. Versioning tracks changes to the self-model over time, so you can audit how the agent's self-assessment has evolved.
A practical approach is to run a cleanup pass periodically, perhaps every hundred interactions. During cleanup, the agent reviews its own memory buffer, identifies redundant or outdated entries, and consolidates similar reflections into higher-level lessons. This meta-reflection step, where the agent reflects on its reflections, is a powerful pattern for keeping memory manageable.
Integrating with Existing LLM Pipelines
The reflexive loop needs to slot into your existing API call flow without disrupting the primary task pipeline. The standard pattern is to run reflection asynchronously after the main response is delivered, so the user doesn't experience additional latency. The reflection and memory update happen in the background, and the stored lessons become available for the next interaction.
For voice agents, this integration requires careful timing. VideoSDK's Agent SDK provides pipeline hooks and observability features that let developers attach post-interaction processing without blocking the real-time conversation flow. The agent processes the user's request, responds in real time, and then asynchronously reflects on the interaction quality while the session continues.
The diagram below shows how the reflexive loop fits into a typical agent architecture:
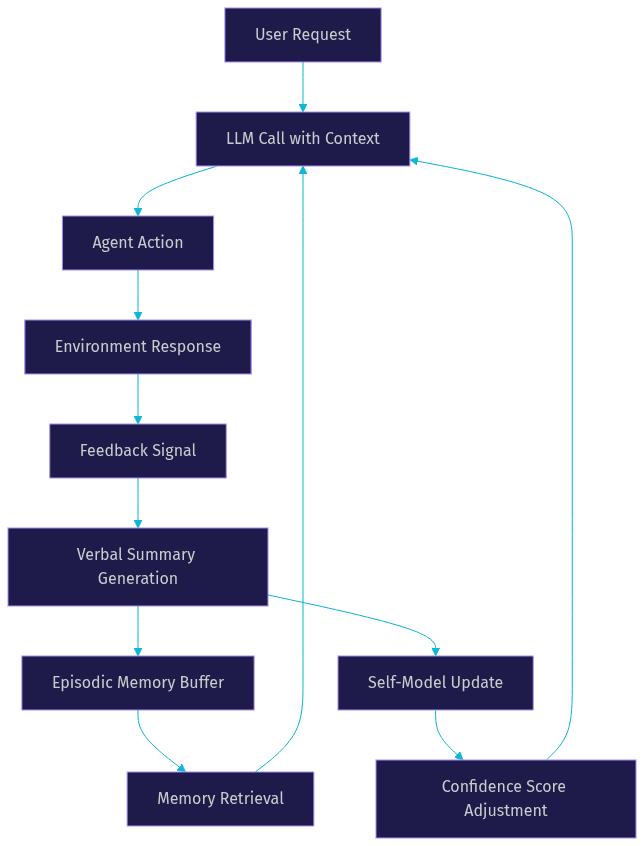
This architecture shows the two feedback paths that make the agent reflexive: the memory retrieval path that brings past lessons into the next LLM call, and the self-model update path that adjusts confidence scores based on the latest outcome.
Real-World Applications
Reflexive agents are moving from research papers into production systems across several domains. The pattern proves valuable wherever agents operate autonomously and errors carry real consequences.
Code Generation Assistants
Code generation is one of the most natural fits for reflexive agents. When a coding agent writes a function, the test suite provides immediate, objective feedback. A reflexive code agent captures test failures, generates a verbal summary of what went wrong, and stores it. The next time it encounters a similar coding task, it retrieves that reflection and adjusts its approach.
Research on reflexive code generation has shown meaningful improvements in pass@1 scores, which measure whether the agent's first attempt at a coding problem is correct. The reflexive loop helps the agent avoid repeating specific categories of mistakes, like forgetting to handle null inputs or misusing library APIs.
Interactive Chatbots
Chatbots powered by LLMs often struggle with scope creep. Users ask questions outside the bot's domain, and the bot either hallucinates an answer or gives an unhelpful response. A reflexive chatbot uses its self-model to recognize when a query falls outside its capabilities and responds honestly.
The self-model tracks which topics the bot has handled well in the past and which have led to poor outcomes. When a user asks about an unfamiliar topic, the agent's confidence score for that domain is low, and it can redirect the user or escalate to a human. This is capability-aware agent behavior in practice.
Autonomous Tools
Web agents and other autonomous tools benefit from goal-state reflection. A web agent navigating a site to complete a purchase needs to evaluate whether each click moves it closer to checkout. Without reflection, the agent can get stuck clicking the same button repeatedly or navigating to irrelevant pages.
The reflexive loop lets the web agent compare its current state to the goal state after each action. If progress stalls, the agent reflects on what went wrong, stores that reflection, and tries a different navigation path. Over multiple sessions, the agent builds a memory of which navigation patterns work and which don't.
Knowledge-Work Assistants
For repetitive knowledge-work tasks like summarizing documents, extracting data, or generating reports, reflexive agents improve through accumulated experience. Each completed task generates a reflection on quality, and the agent gradually learns which summary formats users prefer, which data extraction patterns produce errors, and which report structures get approved without revision.
This continuous improvement pattern is especially powerful when combined with VideoSDK's Python SDK for backend AI pipeline integration, which can handle post-call transcription and analysis to feed the reflexive loop with structured interaction data.
Challenges and Best Practices
Building reflexive agents isn't without friction. Four challenges consistently emerge in production deployments, and each has practical mitigations.
Memory Drift
Stored reflections can become stale when the underlying environment changes. If an API the agent interacts with gets updated, past reflections about that API may no longer apply. The agent needs a mechanism to detect when reflections are outdated.
One approach is to tag reflections with environment version metadata. When the environment changes, reflections tagged with the old version get deprioritized in retrieval. Another approach is to monitor performance trends: if the agent's success rate on a task category suddenly drops, it may indicate that stored reflections for that category are misleading the agent.
Feedback Quality
The reflexive loop is only as good as the feedback that drives it. Noisy, inconsistent, or biased feedback produces poor reflections that can degrade agent performance over time. User feedback is particularly unreliable because users often rate based on factors unrelated to task quality.
Best practice is to combine multiple feedback sources. Use objective signals like test results or task completion flags as the primary driver, and treat user feedback as a secondary signal. When feedback sources disagree, the agent should weight objective signals more heavily.
Computational Overhead
Reflection adds latency and token cost to every interaction. The reflection prompt, the verbal summary generation, the memory storage, and the retrieval step all consume resources. For real-time applications like voice agents, this overhead can be problematic.
The solution is asynchronous reflection. Run the main response through the fast path, and handle reflection in a background process. VideoSDK's Agent SDK supports this pattern through its pipeline observability features, which let developers attach post-response hooks without blocking the real-time conversation.
Evaluation Metrics
Standard accuracy metrics don't capture what makes a reflexive agent valuable. An agent might have lower pass@1 on its first attempt but improve significantly over multiple attempts due to its reflexive loop. Evaluation needs to measure improvement trajectories, not just single-shot accuracy.
Useful metrics include improvement rate (how much the agent's performance improves over N attempts at similar tasks), reflection quality (whether stored reflections correlate with future success), and self-model accuracy (whether the agent's confidence scores match its actual performance). These metrics give a fuller picture of reflexive agent value.
Future Directions
The field of reflexive agents is evolving rapidly, and three directions stand out for 2026 and beyond.
Multi-Agent Reflexivity
When multiple agents collaborate, sharing self-models creates opportunities for coordinated improvement. If one agent discovers it's bad at a task and another is good at it, they can dynamically redistribute work based on mutual self-model awareness. This requires standardized self-model formats and protocols for inter-agent capability exchange.
Continuous Learning Pipelines
Current reflexive agents require manual tuning of reflection prompts and memory management policies. The next step is automating these adjustments. An agent could periodically review its own performance trends and adjust its reflection prompt template, memory pruning thresholds, and confidence scoring formula without human intervention.
Standardized Benchmarks
The community needs shared evaluation suites for reflexive agents. Current benchmarks measure single-shot task completion, but reflexive agents are designed to improve over time. A proper benchmark would present an agent with a series of related tasks and measure improvement across the sequence. Initiatives like Artificial Analysis's Speech Arena and LMSYS Chatbot Arena are starting to explore multi-turn evaluation, but reflexive-specific benchmarks remain an open opportunity.
Definitions Glossary
Reflexive Agent: An AI agent that maintains a self-model, reflects on past actions through verbal summaries, and uses episodic memory to improve future decision-making without model weight updates.
Episodic Memory Buffer: A structured storage layer that records past agent actions, outcomes, and natural-language reflections, queried by similarity or recency when new tasks arrive.
Verbal Reinforcement Learning: A learning pattern where feedback signals are converted into natural-language summaries and injected into future LLM prompts, enabling behavioral improvement without gradient updates.
Self-Model Representation: A structured artifact tracking an agent's capabilities, confidence scores, known limitations, and failure modes, updated dynamically as the agent accumulates experience.
Goal-State Reflection: The process of comparing current state to desired outcome before taking action, enabling agents to detect stalled progress and change strategies.
Key Takeaways
- Reflexive agents improve over time by converting feedback into natural-language reflections stored in an episodic memory buffer, enabling learning without model retraining.
- The four core components (episodic memory, verbal feedback loop, self-model, and goal alignment) form a closed loop that makes agents self-aware of their capabilities and limitations.
- Asynchronous reflection is critical for real-time applications like voice agents, where added latency would degrade user experience.
- Evaluation of reflexive agents should measure improvement trajectories across related tasks, not just single-shot accuracy.
- VideoSDK's AI Voice Agent SDK and Conversational Graph provide infrastructure for building agents with introspective capabilities, including pipeline hooks for post-interaction reflection and session observability for tracking agent performance over time.
Conclusion
Reflexive agents represent a practical shift from static LLM pipelines to systems that genuinely learn from experience. By layering self-models, verbal feedback loops, and episodic memory on top of any LLM, developers can build agents that catch their own mistakes, calibrate their confidence, and improve with every interaction. The pattern doesn't require model fine-tuning or expensive retraining. It requires thoughtful prompt design, disciplined memory management, and a willingness to let the agent evaluate itself honestly. If you're building AI agents with VideoSDK, the AI Voice Agent SDK and Conversational Graph provide the pipeline hooks and state management primitives you need to start experimenting with reflexive loops today. You can sign up for free at app.videosdk.live/login and join the VideoSDK Discord community to discuss agent architecture with 3,000-plus developers. What are you building with reflexive agents? Drop a comment, I'd love to hear what kind of self-improving AI use case you're working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ