


A multimodal agent combines vision, audio, and other sensor inputs with large-language-model reasoning and long-term memory to perceive, remember, and act in complex environments. VideoSDK's real-time communication stack can serve as the low-latency backbone for such agents, while modern MLLM-World-Model frameworks provide the semantic and dynamic core.
Introduction
Building AI that interacts with the real world requires more than text processing. A multimodal agent processes simultaneous streams of visual, auditory, and textual data to make decisions and take actions. Developers building these systems face unique challenges in data fusion, memory management, and real-time inference. When an agent can both see and hear, its ability to ground its responses in reality improves dramatically. This shift from text-only models to systems that understand the physical world represents a major leap in artificial intelligence.
Traditional language models excel at parsing text but fail when asked to interpret a live video feed or react to a sudden audio cue. A multimodal agent bridges this gap by treating text, images, and audio as different views of the same underlying reality. This capability unlocks a new class of applications, from robots that navigate human spaces to virtual assistants that read a user's facial expressions during a video call.
The complexity of a multimodal agent stems from its need to synchronize and reason over asynchronous data streams. A video frame arrives at 30 frames per second, while audio chunks might arrive at 50 times per second. Text inputs arrive unpredictably. The agent must fuse these streams into a single coherent understanding of the world, decide on an action, and execute it before the world changes. This requires a robust architecture and a deep understanding of both AI models and real-time communication protocols.
This article explores the architecture, training, and deployment of multimodal agents. We will cover perception, memory, reasoning, and action loops, along with practical considerations for integrating these agents using real-time communication infrastructure. By the end, you will understand how to structure a multimodal agent architecture and how VideoSDK can serve as the sensory nervous system for your AI applications.
What Is a Multimodal Agent?
A multimodal agent is defined as an AI system that perceives its environment through multiple sensory inputs, processes them through a unified reasoning engine, and takes actions based on that combined understanding. Unlike unimodal agents that process only text or only images, a multimodal agent fuses disparate data types into a coherent state representation. This allows the agent to understand nuances that single-modality systems miss, such as the relationship between a visual event and a simultaneous sound.
A multimodal agent works by ingesting raw video, audio, and text streams, encoding them into a shared latent space, and using a multimodal large language model (MLLM) to reason over that state. The agent then generates an action, which could be a text response, a robotic movement, or a change in a software environment. The MLLM acts as the brain, interpreting the fused sensory data and deciding what to do next.
Recent research trends highlight frameworks like M3-Agent, ModularAgent, and OmniAgent, which emphasize modular perception and dynamic reasoning. These frameworks allow developers to plug in different perception models without retraining the entire system. VideoSDK provides the underlying real-time audio and video SDK that streams these perceptual inputs to the agent's processing pipeline with sub-second latency, ensuring the agent reacts to the world as it happens.
Core Capabilities of Modern Multimodal Agents
Modern multimodal agents share a set of core capabilities that distinguish them from simpler AI systems. These capabilities form the foundation of how the agent interacts with the world.
Perception Across Modalities
Perception is the gateway to a multimodal agent's understanding. The system must process vision, audio, and sensor streams concurrently to build an accurate picture of its environment. Vision streams provide spatial awareness and object recognition. Audio streams offer temporal cues and emotional context. Sensor streams, like depth cameras or LiDAR, add physical measurement data.
Developers typically employ fusion techniques to combine these inputs. Early fusion merges raw data before encoding, which preserves fine-grained details but requires massive compute and tightly synchronized inputs. Late fusion processes each modality independently and merges the final embeddings, offering flexibility at the cost of cross-modal nuance. Hybrid approaches, like mid-fusion, strike a balance by merging data at intermediate layers. For real-time applications, VideoSDK's custom video tracks allow developers to inject processed sensor feeds directly into the agent's perception layer, maintaining high fidelity while controlling bandwidth.
Long-Term Memory Management
A stateful multimodal agent needs memory to maintain context over long interactions. Without memory, an agent resets its understanding at the end of every interaction, making sustained collaboration impossible. Developers implement this using episodic memory for specific past events and semantic memory for general knowledge. Episodic memory allows the agent to recall what happened in a specific previous session, while semantic memory stores facts learned over time.
Entity-centric storage and retrieval allow the agent to recall facts about specific objects or users. According to research on multimodal memory architectures, experience replay mechanisms significantly improve an agent's ability to ground its actions in historical context. VideoSDK's real-time transcription and post-call summary features can serve as a data pipeline for populating these long-term memory stores, converting live interactions into structured text and metadata that the agent can query later.
Designing a Multimodal Agent Architecture
Designing a multimodal agent architecture requires orchestrating perception, memory, reasoning, and action into a continuous loop. The architecture must integrate Multimodal Large Language Models (MLLMs) with World Models (WMs) to predict the consequences of actions. An MLLM understands the current state, while the World Model simulates how that state will change if the agent takes a specific action. This combination allows the agent to plan ahead.
The World Model is a crucial component that separates a reactive agent from a planning agent. It simulates the physics and dynamics of the environment, allowing the agent to test potential actions in its imagination before executing them. For example, a robot agent can use the World Model to predict whether a certain grasp will succeed or drop the object. Task-aware dynamic joint learning involves forward pathways for prediction and backward pathways for goal evaluation. The forward pathway predicts the next state, while the backward pathway evaluates whether that state aligns with the user's goal.
Bidirectional coupling ensures that the agent's perception influences its reasoning, and its reasoning influences what it chooses to perceive next. This creates an active perception loop where the agent directs its sensors based on its current goals.
Practical considerations dictate the architecture's viability. Latency is critical. If an agent takes three seconds to process a visual cue and generate a voice response, the interaction feels broken. Token limits in MLLMs force developers to compress visual context intelligently, often using dynamic resolution or region-of-interest cropping. Modality alignment ensures that audio cues match visual frames, requiring precise timestamp synchronization.
Production deployment adds another layer of complexity. Developers must handle HTTPS requirements, TURN server fallbacks for restrictive networks, and token-based security. The VideoSDK Agent Worker manages the lifecycle of these sessions. It handles the connection between the user's device and the agent's processing pipeline, ensuring that media streams are delivered reliably. The Agent Worker also manages turn detection and voice activity detection, which are critical for natural conversational flow. By offloading these infrastructure concerns to VideoSDK's AI Voice Agent pipeline, developers can focus on the core MLLM and World Model logic.
Training Strategies and Data Requirements
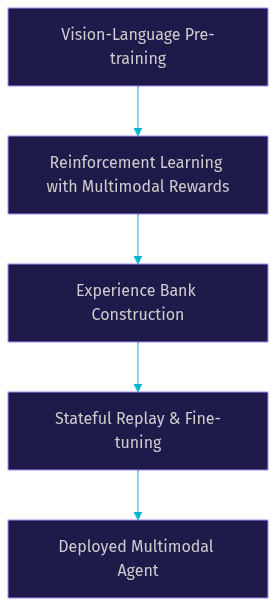
Training a multimodal agent involves multiple stages, each building on the last. Supervised pre-training on massive vision-language datasets teaches the model basic cross-modal correlations. The model learns that the word "dog" corresponds to the visual features of a dog. Reinforcement learning with multimodal rewards refines the agent's behavior, allowing it to learn from environmental feedback. For example, a robot agent receives a positive reward when it successfully picks up an object it was instructed to retrieve.
Experience-bank construction and stateful replay enable the agent to learn from past trajectories without forgetting. The agent stores successful and failed interactions in an experience bank, then samples from this bank during training to reinforce good behavior and avoid repeating mistakes. This approach is crucial for agents that need to learn from sparse rewards.
Data quality is paramount. A multimodal agent trained on poorly aligned audio-visual data will struggle to understand the relationship between what it sees and what it hears. Developers must curate datasets carefully, ensuring that timestamps are synchronized and that the data covers a wide range of scenarios. Experience replay mechanisms must balance exploration and exploitation, ensuring that the agent does not get stuck in a local optimum.
Benchmark suites like M3-Bench, VisTarget-Bench, and LVBench provide standardized evaluation environments. M3-Bench tests the ability to follow multi-step instructions across different modalities. VisTarget-Bench focuses on visual targeting and grounding. LVBench evaluates long-video understanding, which is critical for agents that need to maintain context over extended interactions. These benchmarks provide a standardized way to compare different architectures and training strategies.
Developers building agents with VideoSDK can use the Python SDK to connect their custom training pipelines directly to live media streams, generating synthetic training data from real interactions. The Python SDK also supports cloud recordings, which can be used to build large datasets of multimodal interactions. This creates a flywheel where deployed agents generate data that improves future versions.
Real-World Applications
Multimodal agents are moving from research labs to production environments across several industries. In embodied robotics, home assistants and warehouse bots use multimodal perception to navigate dynamic spaces safely. A warehouse bot must see an obstacle, hear a warning alarm, and adjust its path simultaneously. Multimodal search agents perform visual-text retrieval, allowing users to search for items using a combination of images and natural language queries. This powers advanced e-commerce and asset management systems.
Interactive live streaming benefits from on-the-fly perception. A host agent can analyze live video feeds and audience chat to generate real-time responses, creating engaging and interactive broadcasts. VideoSDK's Interactive Live Streaming (ILS) provides the sub-second latency required for these interactive scenarios, allowing viewers to be promoted to active participants. In live shopping, a multimodal agent can demonstrate a product visually while answering verbal questions about its features.
AI-driven telepresence and virtual agents use VideoSDK's telephony and SIP integration to bridge traditional phone lines with WebRTC, enabling voice agents that can see and hear. A telehealth agent could visually assess a patient's condition while conversing with them over a standard phone call. For structured interactions like appointment booking or insurance claims, developers can use VideoSDK's Conversational Graph to enforce deterministic flows while the multimodal agent handles the natural language and visual processing.
For developers looking to build a multimodal agent interface quickly, VideoSDK's Prebuilt UI Kit offers a zero-code embedding option. This allows teams to prototype a video calling interface with a single component, letting them focus on the agent's backend logic. Once the prototype is validated, they can switch to a custom UI using the full VideoSDK React or Flutter SDKs.
Common Challenges and Open Research Questions
Building production-grade multimodal agents presents significant hurdles. Scaling memory while keeping inference fast is a constant battle. As context windows grow to accommodate longer video streams, the compute required for attention mechanisms scales quadratically. Developers must implement efficient memory retrieval mechanisms, like vector databases with approximate nearest neighbor search, to keep latency low. Aligning visual and auditory context windows is another challenge. Visual frames and audio chunks have different sampling rates, requiring careful temporal synchronization to ensure the agent does not mismatch a visual event with a delayed audio cue.
Robustness to noisy sensor data is critical for real-world deployment. Agents must handle dropped frames, static audio, and sudden lighting changes without hallucinating or failing. VideoSDK's network-adaptive streaming helps mitigate some sensor noise by automatically adjusting bitrate and resolution based on real-time bandwidth, ensuring the agent receives a usable stream even on poor connections.
Evaluation metrics for multimodal agents must go beyond simple word-error-rate or image-classification accuracy. Developers need to measure how well the agent grounds its responses in the visual and auditory context. For example, if an agent is asked to describe a scene, does it mention the most salient objects and actions? Latency is another critical metric. In real-time applications, an agent that takes too long to respond is useless, even if its response is perfect. Developers must measure end-to-end latency, from the time a sensor captures an input to the time the agent generates an action. Security and privacy also become more complex when agents process video and audio of real people. Token scoping and room access control, like the features offered by VideoSDK, are essential for protecting user data.
Future Directions
The future of multimodal agents points toward native active perception cycles. Agents will continuously query their environment for missing information rather than passively waiting for inputs. If an agent cannot see an object clearly, it will move its camera or ask the user for clarification. Integration with real-time video SDKs will become standard for embodied agents, providing the sensory nervous system they need to operate in the physical world.
Emerging standards for multimodal agent interoperability will allow developers to swap out MLLMs, memory stores, and perception modules seamlessly, much like how VideoSDK's open-source AI Agent SDK supports modular integration of different STT, LLM, and TTS providers. As these standards mature, we will see a proliferation of specialized agents that can collaborate on complex tasks. The combination of deterministic flow control via Conversational Graph and flexible multimodal reasoning will define the next generation of AI applications.
Definitions Glossary
Multimodal Agent: An AI system that processes multiple sensory inputs like vision and audio to reason and act in an environment.
Multimodal Large Language Model (MLLM): A language model extended to process and generate content across text, images, and audio streams.
Episodic Memory: A memory type that stores specific past events and experiences, allowing an agent to recall contextual history.
Early Fusion: A data fusion technique that merges raw inputs from different modalities before feature extraction.
Experience Replay: A training mechanism where an agent learns from stored past experiences to improve future decision-making.
Key Takeaways
- A multimodal agent integrates vision, audio, and text to understand and interact with complex environments.
- Architecture design must balance latency, token limits, and modality alignment to maintain real-time responsiveness.
- Training relies on supervised pre-training, reinforcement learning, and experience replay using benchmarks like M3-Bench.
- VideoSDK provides the low-latency real-time communication backbone for streaming perceptual data to these agents.
- Future development will focus on active perception cycles and modular interoperability standards.
Conclusion
Building a multimodal agent requires orchestrating perception, memory, and reasoning into a cohesive, real-time system. Developers must navigate fusion techniques, memory management, and rigorous training strategies to create agents that operate effectively in the real world. The challenges of latency, modality alignment, and robustness are significant, but the payoff is an AI that can truly interact with human environments. VideoSDK provides the essential real-time communication infrastructure, from video calling APIs to AI voice agents, enabling these systems to perceive and act with sub-second latency. What are you building with VideoSDK? Drop a comment. I would love to hear what kind of multimodal agent use case you are working on. You can start building today by signing up at app.videosdk.live/login.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ