


A multi agent system (MAS) is a group of autonomous AI agents that share an environment, exchange messages, and coordinate to achieve goals no single agent could handle alone. Developers adopt MAS when one agent hits limits in context, expertise, or latency. VideoSDK's open-source AI Agent SDK supports multi-agent switching and orchestration, making it a practical starting point for voice and conversation pipelines.
Autonomous AI agents went from research demos to production workloads in under two years. By 2026, most teams shipping LLM-powered products have hit the same wall: a single agent with one context window, one prompt, and one set of tools eventually buckles. It forgets earlier instructions, averages its competence across every domain you throw at it, and turns every request into a serial queue.
The industry's answer has been multi agent systems: split the work across specialized agents that reason independently and coordinate through messages. But this trade introduces real engineering problems, from choosing a coordination pattern to handling partial failures across a distributed pipeline.
This guide answers the core question developers face: when should you move from a single agent to multi agent systems, and how do you architect the transition without drowning in orchestration complexity? You'll get the three dominant architectural patterns, a decision framework, engineering considerations, real production use cases, and a language-agnostic implementation blueprint.
What Are Multi Agent Systems?
A multi agent system is defined as a collection of autonomous agents that operate in a shared environment, communicate through defined protocols, and pursue collective goals through coordination rather than central control. Each agent has its own role, its own tools, its own reasoning loop, and often its own model. What makes the system "multi agent" rather than "one big program" is that each agent can act independently and the global behavior emerges from their interactions.
Multi agent systems work by decomposing a complex task into specialized sub-tasks, assigning each to an agent with a narrow domain and a small, focused context, then routing information between them through a communication layer such as a message bus, event stream, or direct function calls. Distributed reasoning across several small contexts often outperforms stuffing everything into one giant prompt.
Consider an e-commerce support operation. Instead of one agent that handles every question, a MAS deploys a customer-query agent that classifies intent, an order-processing agent that queries and modifies orders, an inventory-check agent that verifies stock across warehouses, and a shipping-planner agent that estimates delivery windows. Each agent stays sharp because it only sees the data relevant to its job.
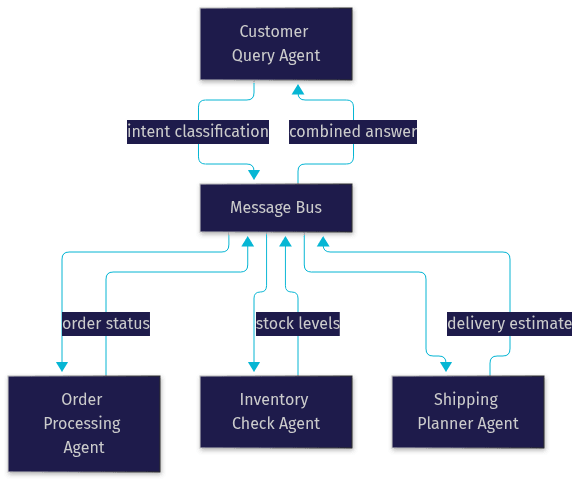
VideoSDK provides multi-agent capability through its AI Agent SDK, which supports multi-agent switching, agent sessions, and pub/sub messaging between agents and users over real-time rooms.
Core Architectural Patterns for Multi Agent Systems
Every multi agent system design starts with one decision: how do agents coordinate? Three patterns dominate production deployments in 2026, and nearly everything else is a variation of them.
Supervisor Pattern
The supervisor pattern places a central coordinator agent above a set of specialist agents. The supervisor receives the incoming request, decides which specialist should handle it (or handles routing across several in sequence), dispatches the task, collects results, and composes the final answer. It is the most common starting point because it maps cleanly onto how teams already think about orchestration.
The strengths are observability and control. One component knows the full plan, so tracing, debugging, and enforcing business rules stay straightforward. The weakness is the supervisor itself: it can become a bottleneck, a single point of failure, and a prompt-engineering headache as routing logic grows. Use the supervisor pattern when tasks have a clear decomposition and you need deterministic control, such as compliance-driven loan underwriting or customer support triage.
Hierarchical Structure
A hierarchical MAS architecture generalizes the supervisor pattern into a tree. Top-level agents decompose large goals into sub-goals, delegate to mid-level agents, which decompose further into leaf-level specialist agents. Results aggregate back up the tree. This is how you scale a supervisor pattern beyond a handful of agents without one coordinator holding every routing decision in its head.
Hierarchies shine for deep, multi-stage workflows: a research agent that spawns sub-teams per topic, or an underwriting pipeline where a lead agent delegates to credit-risk, fraud, and compliance leads, each with their own sub-agents. The cost is latency, since every tree level adds a round trip, and debugging becomes harder because a failure three levels down may surface as a vague error at the root. Checkpointing at each level mitigates this.
Peer-to-Peer Agent Network
A peer-to-peer agent network removes the central controller entirely. Agents communicate directly with each other, often through a shared message bus or publish-subscribe protocol, and coordination emerges from agent-to-agent negotiation rather than a plan issued from above. This is the classic distributed-systems shape applied to autonomous AI agents.
Peer-to-peer maximizes fault tolerance and horizontal scalability, since no single coordinator can fail or bottleneck. It trades away global visibility and makes deterministic behavior harder to guarantee, which matters in regulated domains. It fits environments with many similar agents doing local optimization, such as robotics fleets or dynamic logistics routing.
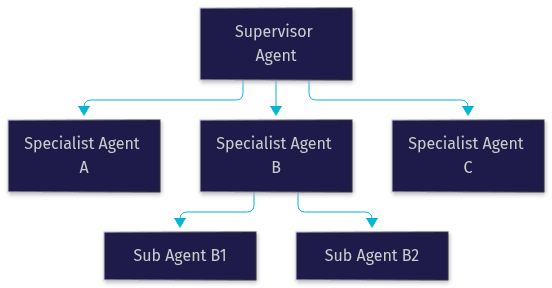
The diagram above shows the supervisor and hierarchical shapes. In a true peer-to-peer mesh, every agent connects to every other agent through the bus with no node on top.
Choosing the Right Multi Agent Pattern
Pattern selection is an engineering trade-off, not a fashion choice. Ask four questions before committing. How complex is the task decomposition? How latency-tolerant is the user experience? What are your fault-tolerance requirements? And how large will the agent fleet grow?
If tasks decompose cleanly and you need auditability, start with a supervisor. If the workflow is deep and multi-stage, go hierarchical. If you need many agents doing local decisions with no central dependency, go peer-to-peer. When in doubt, prototype with a supervisor and evolve toward hierarchy only when routing complexity forces it.
| Pattern | Scalability | Complexity | Failure Impact | Best For |
|---|---|---|---|---|
| Supervisor | Moderate | Low to medium | High, coordinator is a single point of failure | Deterministic workflows, compliance, support triage |
| Hierarchical | High | High | Medium, contained per subtree but harder to debug | Deep multi-stage pipelines, research, underwriting |
| Peer-to-peer | Very high | Medium to high | Low, no central coordinator to fail | Robotics, logistics, dynamic routing |
The most important row is failure impact. Teams consistently underestimate how a supervisor outage or a poisoned routing prompt can stall an entire pipeline, so if your MAS handles revenue-critical flows, plan supervisor redundancy from day one.
Key Engineering Considerations
Architecture is the easy part. The hard part is the plumbing between agents: messaging, context, failure handling, and cost.
Agent Communication and Messaging
Agent communication protocols determine reliability. Production MAS deployments favor event-driven architectures with message queues or publish-subscribe backbones, where each agent subscribes to the events it cares about and publishes results back to the stream. This decouples agents, lets you add or replace one without touching the rest, and provides durable delivery when an agent crashes mid-task. Cloud services like Amazon EventBridge and Amazon MQ give you this without building infrastructure. The rule: never let agents call each other synchronously in a chain longer than two hops, or one slow agent stalls the whole system.
Context Management and Window Saturation
Context window saturation is the silent killer of single-agent designs. As conversation history, retrieved documents, and tool outputs accumulate, the model's effective reasoning degrades, instructions drift out of attention, and costs climb because every token is re-sent on every turn. Splitting work across agents is the primary mitigation: each agent holds only the slice of context its role requires, and inter-agent messages carry distilled state rather than raw transcripts. VideoSDK's Agent SDK addresses this with explicit context management and context window controls, letting you bound what each agent session carries.
Fault Tolerance and Recovery
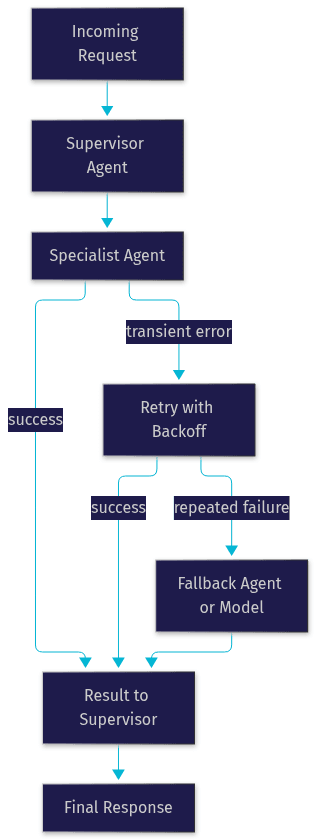
Distributed reasoning means distributed failure. A robust MAS treats failure as expected: retries with exponential backoff for transient errors, checkpointing so a failed subtree resumes instead of restarting, fallback adapters that switch to an alternate model or provider when the primary degrades, and graceful degradation where the system returns a partial answer rather than nothing. The MAST failure taxonomy, introduced in recent MAS research, gives teams a shared vocabulary for classifying multi-agent failures, from specification and design issues to inter-agent misalignment, and is worth adopting for your incident reviews.
Cost and Performance
Every agent turn costs tokens, and orchestration layers cost money too. AWS Step Functions bills per state transition, EventBridge per event published, and each LLM call per input and output token. Estimate per-agent cost by multiplying expected turns, average context size, and model pricing, then multiply by agent count. Latency stacks the same way: three sequential agents each taking two seconds yield a six-second response, which is fatal for voice interfaces. Run agents in parallel wherever the task graph allows.
Real-World Multi Agent Use Cases
Three industries show the patterns in production.
FinTech: Automated Loan Underwriting
A lender deploys a supervisor-pattern MAS for loan decisions. A lead underwriting agent receives the application and delegates to a credit-risk agent that analyzes financials, a fraud-detection agent that screens for anomalies, and a compliance agent that verifies regulatory requirements. Each specialist holds only its domain context, keeping reasoning sharp and audit trails clean. The business value: decision turnaround drops from days to minutes, with every delegation step logged for regulators. Deterministic agent behavior in the compliance path is non-negotiable here, which is why VideoSDK's Conversational Graph, a deterministic flow engine layered over the agent pipeline, fits compliance-driven conversations well.
HealthTech: Patient Triage
A telehealth platform combines a symptom-analysis agent, a medical-record lookup agent, and an appointment-scheduling agent under a hierarchical coordinator. The symptom agent gathers structured information, the records agent pulls relevant history, and the scheduler books the right care pathway. Value: nurses handle only escalations, and patients get guidance in seconds. Security and compliance for multi-agent pipelines, including HIPAA-grade data handling and role-scoped access to records, is a first-class requirement, not an afterthought.
Supply-Chain: Dynamic Routing
A logistics operator runs a peer-to-peer agent network where inventory agents at each warehouse, a demand-forecast agent, and logistics agents negotiate routing in near real time. No central coordinator exists; agents publish local state and bid on shipments. Value: the network reroutes around a port closure or stockout without a human in the loop, and the mesh survives individual agent failures by design.
Implementation Blueprint for Multi Agent Systems
Here is a language-agnostic roadmap from zero to a working pilot.
Step 1: Define agent roles from your task decomposition. Map your workflow's distinct sub-tasks, then assign each to a named agent with a narrow role, a bounded context, and a minimal tool set. Resist creating agents for steps a simple function could handle.
Step 2: Choose an orchestration platform. Open-source frameworks like LangChain, CrewAI, LangGraph, and the Microsoft Agent Framework cover most custom builds, while AWS Step Functions with EventBridge and Amazon MQ gives you managed durability. If your agents interact by voice or phone, VideoSDK's Agent SDK and Agent Cloud handle the real-time session layer, including multi-agent switching and call transfer.
Step 3: Set up reliable messaging. Wire agents through an event-driven backbone with durable delivery, so a crashed agent's work resumes rather than vanishes. Define your message schemas before writing agent logic.
Step 4: Implement monitoring and observability. Track throughput, latency per agent, success rate, and cost per request from day one. Pipeline observability, including per-agent traces, is what turns MAS debugging from guesswork into engineering.
Step 5: Run a pilot and iterate. Launch on a narrow, low-risk workflow, measure against your evaluation metrics, and expand agent scope only when the pilot's success rate and latency hold. The VideoSDK code samples include multi-agent examples worth studying before you build.
Common Pitfalls and How to Avoid Them
Four mistakes account for most failed MAS projects.
Over-orchestrating. Teams add a fifth agent where a conditional in an existing agent would do. Every agent adds latency, cost, and a failure surface. Mitigation: start with the fewest agents that cover the domain, and split only when a specific agent demonstrably underperforms.
Ignoring latency stacking. Sequential agent chains produce multi-second responses that kill voice and chat experiences. Mitigation: parallelize independent agents in the task graph and set per-agent timeouts.
Poor error handling. An unhandled failure in one agent poisons the whole pipeline. Mitigation: retries, fallbacks, and checkpointing at every delegation boundary, plus a failure taxonomy so incidents get classified consistently.
No evaluation harness. Teams ship MAS changes with vibes instead of metrics. Mitigation: define success rate, latency, and cost benchmarks before the pilot, and gate every change against them.
Definitions Glossary
Multi Agent System (MAS): A collection of autonomous agents sharing an environment and coordinating through messages to achieve goals beyond a single agent's capacity. VideoSDK supports MAS through multi-agent switching and pub/sub messaging in its Agent SDK.
Supervisor Pattern: An architecture where a central coordinator agent routes tasks to specialist agents and composes their results. Best for deterministic, auditable workflows.
Hierarchical MAS Architecture: A tree-shaped delegation structure where higher-level agents decompose goals into sub-tasks for lower-level agents, with results aggregating upward.
Peer-to-Peer Agent Network: A fully distributed coordination model with no central controller, where agents negotiate directly through a shared message bus for maximum fault tolerance.
Context Window Saturation: The degradation that occurs when an agent's context fills with history and tool outputs, causing instruction drift and rising cost. Splitting work across agents is the primary mitigation.
Agent Worker: The process that runs an AI agent and manages its session lifecycle. In VideoSDK, the Agent Worker is a Python process managing sessions inside real-time rooms.
Key Takeaways
- Multi agent systems solve the three limits of single agents: context window saturation, shallow cross-domain expertise, and serial latency.
- The supervisor pattern offers control and auditability, hierarchies scale deep workflows, and peer-to-peer meshes maximize fault tolerance at the cost of determinism.
- Reliable inter-agent messaging, checkpointing, and fallbacks matter more than which LLM you pick.
- Estimate cost and latency by multiplying per-agent turns, context size, and model pricing across the whole task graph before committing to an architecture.
- VideoSDK's open-source AI Agent SDK provides the real-time session layer for multi-agent voice experiences, including multi-agent switching, call transfer, and pipeline observability.
Conclusion
Multi agent systems are the natural next step once a single autonomous agent hits its limits in context, expertise, or responsiveness. Adopt them when your task genuinely decomposes into specialties, choose the supervisor pattern for control, hierarchies for depth, and peer-to-peer for resilience, then invest early in messaging reliability, observability, and evaluation metrics. To prototype quickly, explore the VideoSDK AI Agents documentation, grab a free account at app.videosdk.live/login, and join the VideoSDK Discord community to compare notes with other builders. What are you building with multi agent systems? Drop a comment, I'd love to hear which coordination pattern you chose and why.
Conclusion
Multi-agent systems aren't just theoretical — they’re actively shaping the future of AI across industries. From autonomous driving and AI assistants to enterprise workflows and intelligent automation, the ability of agents to collaborate, negotiate, and adapt makes them ideal for solving large-scale problems.
As the field matures, expect to see multi-agent systems become the foundation for how businesses build intelligent, modular, and scalable AI solutions.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ