


A knowledge based agent is an AI agent that grounds its reasoning and decisions in a structured knowledge base, typically a knowledge graph, rather than relying solely on the parametric memory of a large language model. The agent retrieves verified facts, reasons over them, and executes actions through connected tools. This approach dramatically reduces hallucinations and makes agent behavior auditable. VideoSDK applies the same grounding principle to real-time voice agents through its deterministic Conversational Graph, where business rules, not LLM judgment, control conversation flow.
LLM-driven agents have exploded in popularity, and so has a familiar failure mode: the agent that confidently plans a workflow using facts that simply do not exist. A logistics agent books a carrier that retired in 2023. A support bot cites a refund policy the company replaced six months ago. These are not model bugs; they are grounding failures. The model had no structured source of truth to consult, so it improvised.
That is the problem the knowledge based agent solves. Instead of treating the LLM as an oracle, you treat it as a reasoning engine that must consult a curated knowledge base before acting. In this article, you will learn what a knowledge based agent is, how knowledge graphs empower it, how to design one, the challenges you will hit in production, and where these agents are already delivering value in 2026.
What Is a Knowledge Based Agent?
A knowledge based agent is defined as an autonomous AI system whose decisions are derived from an explicit, structured knowledge base combined with a reasoning engine, typically an LLM. The agent works by first parsing user intent, then retrieving relevant facts from the knowledge base, then reasoning over those facts to produce a plan or answer, and finally executing actions through connected tools and APIs.
This contrasts with a pure LLM agent, which relies on what the model memorized during training. Parametric memory is static, expensive to update, and prone to hallucination when queried outside its training distribution. A knowledge based agent externalizes the facts. When the world changes, you update the knowledge base, not the model. That single architectural decision is what makes these agents controllable, auditable, and trustworthy enough for production use.
Core Components of a Knowledge Based Agent
Every knowledge based agent, regardless of vendor or framework, is assembled from three cooperating layers. Understanding the division of labor between them is the foundation for designing one that behaves predictably under real workloads.
Knowledge Base
The knowledge base is the agent's source of truth. In modern architectures, this is usually a knowledge graph: a network of entities connected by typed relationships, stored as triples in the form of subject, predicate, and object. For example, a support knowledge graph might contain a triple stating that a specific subscription tier includes a specific refund window. Triples are compact, machine-readable, and composable, which means thousands of them can encode an entire product policy set. Alongside graphs, knowledge bases often include vector indexes for semantic search over unstructured documents, giving the agent both precise factual lookup and fuzzy contextual retrieval.
Reasoning Engine
The reasoning engine is where the LLM earns its keep. Rather than answering directly from memory, the LLM interacts with the knowledge base through retrieval-augmented generation or explicit tool calls. The agent translates a user query into a structured graph query, fetches the relevant triples or document chunks, and instructs the LLM to reason only over the retrieved evidence. This is agentic reasoning with guardrails: the model plans, but the facts come from somewhere verifiable. Confidence thresholds and verification steps can be layered in so that low-evidence answers get escalated rather than guessed.
Action Execution Layer
Decisions are worthless until they change something in the world. The action execution layer translates the agent's reasoned plan into concrete operations: calling a REST API, updating a database record, sending a notification, or joining a real-time communication session. This layer enforces permissions and logging, so every action the agent takes is attributable and reversible where possible.
How Knowledge Graphs Empower Agents
Knowledge graphs give agents something vector search alone cannot: explicit, traversable relationships between facts. This section explains why that matters technically.
Graph traversal enables multi-hop reasoning, the ability to answer questions that require chaining several facts together. A question like "which suppliers of part X were affected by the factory closure last quarter?" requires connecting a closure event to a factory, the factory to its suppliers, and those suppliers to the part. Vector similarity can surface loosely related documents, but a graph query walks the exact relationship path and returns a provably complete answer set.
Most production systems expose the graph through a query interface in the style of SPARQL or property-graph query languages. The LLM's job is to translate natural language into a well-formed graph query, and the graph engine's job is to execute it deterministically. This split is powerful: the nondeterministic component (the LLM) handles language, while the deterministic component (the graph) handles facts.
The typical flow looks like this:
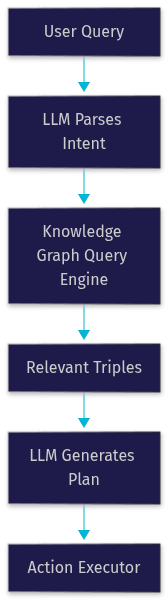
A practical pattern seen across production deployments is the knowledge graph executor: a dedicated component that validates every LLM-generated graph query before execution, rejecting malformed or out-of-scope queries. Developers building voice-based agents on platforms like VideoSDK's AI Agents apply the same idea through function tools, where the agent can only invoke pre-registered, schema-validated actions.
Designing an Effective Knowledge Based Agent
Design is where most knowledge based agent projects succeed or fail. Three areas deserve deliberate attention before you write any integration logic.
Data Preparation
The quality ceiling of your agent is the quality of your triples. Curation means more than scraping data into the graph; it means aligning entities to a consistent schema, deduplicating records that describe the same real-world thing, and verifying coverage against the questions your users actually ask. A common failure is a graph that is structurally sound but semantically sparse: the relationships exist, but not the ones your queries need. Start with a narrow domain, build the schema for it, validate retrieval quality against a test question set, and only then expand coverage.
Memory Management
Agents need two kinds of knowledge memory. Short-term memory holds the current session: recent user statements, retrieved facts, and intermediate reasoning steps, typically cached and discarded when the conversation ends. Long-term memory persists across sessions: user preferences, historical outcomes, and durable facts. The hard problem is forgetting. Unbounded memory degrades retrieval precision and inflates latency, so production systems use recency-weighted scoring, summarization of stale context, and explicit expiry on volatile facts. A policy document, for instance, should be evicted from cache the moment a newer version is ingested, or the agent will confidently cite superseded policy.
Tool and API Integration
Tool integration is the orchestration challenge: connecting the agent to external search, databases, and SaaS systems without turning it into an uncontrolled shell. The reliable pattern is a registry of named tools, each with a declared input schema, an output contract, and permission scope. The reasoning engine selects a tool, the execution layer validates the request against the schema, and the result flows back into the reasoning loop as new evidence. Every invocation is logged for audit. When the action involves real-time communication, such as an agent escalating to a human on a live call, platforms like VideoSDK provide the call transfer and warm transfer primitives so the handoff happens without dropping the session.
Common Challenges and Practical Solutions
Every team deploying knowledge based agents hits the same three walls. Here is how experienced practitioners get over them.
Scalability and Latency
Graph traversal cost grows with graph size and query depth, and multi-hop queries over millions of triples can blow past interactive latency budgets. The standard mitigations are graph indexing (precomputing frequent traversal paths), approximate nearest-neighbor search for the vector side of retrieval, and aggressive caching of hot query results. Teams also shard the knowledge base by domain so that a support agent never pays the latency cost of traversing an unrelated logistics subgraph. Measure end-to-end retrieval latency as a first-class metric, because users perceive agent slowness as agent stupidity.
Hallucination and Consistency
Grounding reduces hallucination but does not eliminate it; the LLM can still over-generalize from retrieved evidence or fabricate a bridge between two true facts. Hallucination mitigation in production means verification steps: after the LLM produces an answer or plan, a separate check confirms every factual claim traces back to a retrieved triple or document. Confidence thresholds route uncertain outputs to a human or a clarification question instead of an action. This is the same philosophy behind VideoSDK's Conversational Graph, where deterministic nodes and transitions guarantee that compliance-critical steps always happen in order, with the LLM confined to natural language generation.
Knowledge Updates
A stale knowledge base is worse than none, because the agent's answers carry false authority. The solution is an incremental ingestion pipeline: sources feed a processing stage that extracts entities and relationships, merges them into the graph, and triggers a memory refresh so cached facts are invalidated. The update loop should be event-driven, not batch-only, so a policy change published at 9 a.m. is live in the agent by 9:05.
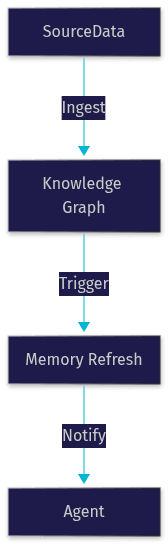
Dynamic knowledge update is a genuine differentiator in 2026: the agents that win in production are not the ones with the biggest models, but the ones whose facts go stale the slowest.
Real-World Applications of Knowledge Based Agents
Three domains show the pattern working at scale.
Customer support. Support bots grounded in a live policy knowledge graph answer questions about refunds, coverage, and eligibility with citations to the exact current policy version. When the policy changes, the graph is updated and the bot's answers change with it, with no retraining. Teams running voice-based support agents pair this grounding with real-time infrastructure, using VideoSDK's telephony and SIP integration to let the same knowledge-grounded agent answer phone calls and transfer to humans when confidence drops.
Enterprise search. Knowledge based search assistants combine document retrieval with graph reasoning, so a query about "all contracts with the payment clause that expired this quarter" returns an exact answer set, not ten PDFs to read. The graph encodes the relationships between contracts, clauses, dates, and counterparties; the LLM translates the question and narrates the result.
Autonomous planning. Logistics and operations agents use knowledge-based planning over graphs of locations, capacities, constraints, and schedules. Because the plan is derived from explicit facts, every step is traceable to a triple, which makes these agents auditable enough for regulated environments. Game AI applies the same architecture, where world-state graphs drive non-player character decision-making.
Future Trends for Knowledge Based Agents
Three trends are shaping the next wave. First, hybrid retrieval-augmented models are collapsing the boundary between retrieval and reasoning, with models trained to interleave graph queries and generation natively rather than through bolted-on tool calls. Second, multimodal knowledge is entering the graph: images, tables, and diagrams are being encoded as first-class entities, so an agent can reason over a chart or a floor plan as easily as a policy paragraph. Third, self-improving graph embeddings are emerging, where the system learns from user feedback and failed queries to propose new triples and relationships automatically, shrinking the manual curation burden that currently limits scale.
Definitions Glossary
Knowledge Based Agent: An autonomous AI agent whose reasoning and actions are grounded in an explicit, structured knowledge base rather than the LLM's parametric memory alone.
Knowledge Graph: A network of entities and typed relationships, stored as subject-predicate-object triples, that machines can traverse to answer multi-hop questions deterministically.
Retrieval-Augmented Generation (RAG): A technique where an LLM generates answers using evidence fetched at query time from an external knowledge source, reducing hallucination.
Multi-Hop Reasoning: Chaining several facts or graph relationships together to answer a question that no single fact resolves on its own.
Conversational Graph: VideoSDK's deterministic orchestration layer that defines voice agent conversation flow as a directed graph of nodes and transitions, keeping the LLM confined to language generation.
Key Takeaways
- A knowledge based agent separates facts (the knowledge base) from reasoning (the LLM) from action (the execution layer), making each component independently improvable and auditable.
- Knowledge graphs enable multi-hop reasoning and provably complete answers, something vector similarity search alone cannot deliver.
- Memory management and dynamic knowledge updates are production-critical: stale cached facts cause confident, wrong answers.
- Hallucination mitigation requires verification steps and confidence thresholds, not just grounding.
- Deterministic orchestration layers like VideoSDK's Conversational Graph extend the same grounding principle to real-time voice agents, where every compliance step must happen in order.
Conclusion
The knowledge based agent represents the maturing of LLM agents from impressive demos to dependable systems. By externalizing facts into a knowledge graph, confining the LLM to reasoning and language, and executing actions through validated tools, you get AI that is controllable, auditable, and honest about what it knows. The pattern generalizes from enterprise search to customer support to autonomous planning, and it extends naturally into real-time voice with VideoSDK's AI agent infrastructure. If you want to experiment, start with the VideoSDK AI Agents documentation, explore the open-source samples on VideoSDK's GitHub, and sign up free at app.videosdk.live/login. What are you building with knowledge based agents? Drop a comment, I'd love to hear which domain you are grounding first.
Final Thoughts
Knowledge-Based Agents are a crucial pillar of explainable and intelligent AI. With their ability to reason logically and operate in dynamic environments, they're enabling smarter systems that go beyond prediction—they understand, decide, and act.
Whether it's automating customer support, assisting in medical diagnostics, or guiding enterprise operations, KBAs are empowering AI to become more transparent, trustworthy, and impactful.
As the future of AI continues to unfold, knowledge-based agents will remain the logic behind the intelligence.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ