


A rag ai agent is an LLM-driven agent that combines retrieval-augmented generation with autonomous planning to answer queries using a specific knowledge base. Instead of relying on pre-trained weights, it retrieves relevant documents, injects them into the prompt context, and synthesizes an accurate response. This approach drastically reduces hallucinations and enables production-grade deployment for enterprise applications.
AI agents are powerful, but they share a frustrating flaw: they hallucinate when they lack reliable context. You ask a plain LLM for a summary of your company's Q3 financial report, and it might confidently invent numbers. This happens because the model relies solely on its pre-trained weights, which do not include your private data. A rag ai agent solves this by grounding the model in a retrieval-augmented generation pipeline. It fetches the right information from your knowledge base before generating a single word. This approach ensures the agent cites its sources and sticks to the facts. In this guide, we will break down the core components, retrieval strategies, and production considerations you need to build a robust, low-latency retrieval agent that performs reliably under real-world conditions.
What Is a rag ai Agent?
A rag ai agent is defined as an LLM-driven agent that uses retrieval-augmented generation to ground its responses in external data. A plain LLM generates text based on patterns learned during training, which makes it unsuitable for domain-specific or private data. A rag ai agent works by intercepting the user query, searching a vector store or database for relevant context, and injecting that context into the prompt before the LLM generates a response. This context injection ensures the model has the facts it needs to produce an accurate answer. Advanced agentic RAG setups go further by using multi-step planning and query decomposition to handle complex questions that require multiple searches. If you are building voice or video applications, platforms like VideoSDK provide API-first integration to connect these agents into real-time communication pipelines, allowing the agent to listen, retrieve, and speak within a live session.
Core Components of a rag ai Agent
A production-grade rag ai agent relies on three distinct layers: retrieval, reranking, and synthesis. Each layer plays a critical role in ensuring the final output is accurate, relevant, and grounded in your specific knowledge base. Skipping or under-optimizing any of these layers leads to poor performance and user frustration.
Retrieval Layer
The retrieval layer is the foundation of your rag ai agent. It stores your knowledge base in a vector database like Qdrant or PostgreSQL with vector extensions. When a query arrives, the agent converts it into an embedding using models like OpenAI embeddings or sentence-transformers. It then performs a semantic search to find the closest matches in the vector space. However, pure semantic search can sometimes miss exact keyword matches, which is a problem for technical queries or specific identifiers. A hybrid search approach combines semantic search with keyword filters (like BM25) to capture both the underlying meaning and specific terms. This ensures low-latency retrieval without sacrificing precision, giving you the best of both worlds.
Reranking Layer
Retrieval often returns a broad set of documents that are semantically close but not necessarily the most relevant to the specific query. The reranking layer refines these results. Cross-encoder models or provider APIs like Cohere rerank evaluate the actual relevance of each retrieved chunk to the user query by looking at them together. This step is crucial because vector similarity does not always equal semantic relevance. Reranking improves the signal-to-noise ratio before the context reaches the LLM, ensuring the model only sees the most pertinent information.
Synthesis Layer
The synthesis layer is where the LLM generates the final answer. It takes the reranked chunks and injects them into the prompt template. The LLM is instructed to answer the question using only the provided context. This layer also handles conversational memory and citation generation, ensuring the agent attributes its claims to the correct sources. Effective prompt engineering is essential here to prevent the model from ignoring the context or hallucinating beyond it.
Designing the Retrieval Strategy
Choosing the right retrieval strategy is critical for a rag ai agent. You have three main options: pure semantic search, BM25 keyword search, and hybrid search. Pure semantic search excels at understanding intent and synonyms, making it ideal for exploratory queries where the user might not know the exact terminology. BM25 shines when you need exact matches, such as specific product IDs, error codes, or legal statute numbers. Hybrid search combines both, using a fusion module to merge results. This is generally the best approach for production-grade deployment because it handles a wider variety of query types.
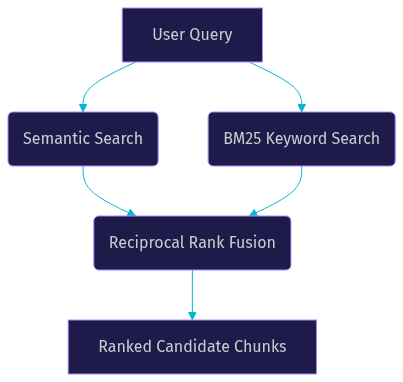
Hybrid search requires tuning the weights of the semantic and keyword results. You might weight semantic search higher for general questions and BM25 higher for technical lookups. Using a Redis cache for frequent queries can significantly reduce latency, as the agent can bypass the retrieval and reranking steps entirely for common questions. This is a key scalability tactic for high-traffic applications.
Choosing and Configuring a Reranker
Once you have candidate chunks from your retrieval layer, you need a reranker to ensure the top results are the most relevant. The right choice depends on your data size, budget, and latency requirements. Cohere rerank offers a hosted API that is easy to integrate and highly accurate, making it a great choice for teams that want to move quickly. If you need to keep data on-premise for security and data isolation, you can host your own cross-encoder using sentence-transformers. Custom models trained on your specific domain offer the highest precision but require ML expertise to maintain and deploy.
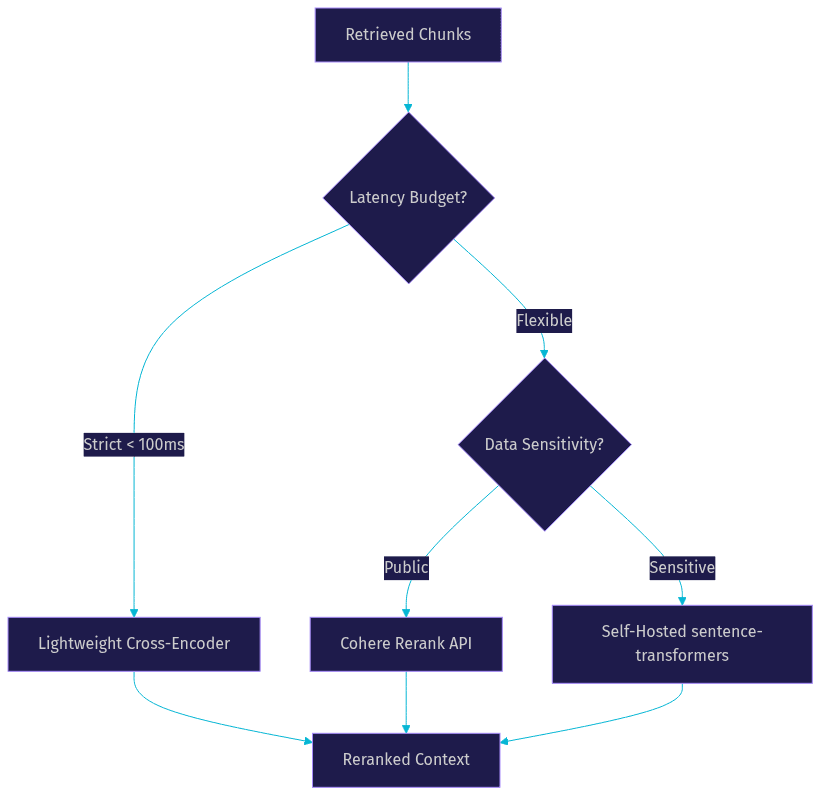
The trade-off is always latency versus precision. A heavy reranker adds milliseconds to your pipeline, which can be noticeable in real-time applications. You must track observability metrics to ensure the reranker does not bottleneck the user experience. Sometimes, a simple time-based cutoff is necessary to maintain responsiveness.
Building a Production-Ready rag ai Agent
Moving from a prototype to a production-ready rag ai agent involves robust ingestion, orchestration, and monitoring. A script that works in a notebook is not enough; you need a system that can handle failures, scale with load, and provide insights into its performance.
Knowledge-Base Ingestion
Ingestion is where your agent gets its knowledge. You must parse documents (text, PDF, images, audio, video) and split them into chunks. Chunking strategy matters: too small, and you lose context; too large, and you dilute the signal and exceed the LLM's context window. You also need to attach metadata to each chunk, such as document title, section, and date. This metadata allows for pre-filtering during retrieval, which improves both speed and accuracy. Multi-modal retrieval requires specialized parsers to extract text from images and transcripts from audio.
Agent Orchestration
Simple RAG pipelines follow a linear path: retrieve, synthesize, return. An agentic RAG setup uses graph-based orchestration tools like LangGraph or LangChain. These tools enable multi-step planning. If the initial retrieval fails to find a good answer, the agent can decompose the query into smaller parts, search again, or use a tool to fetch live data from an API. This loop continues until the agent is confident it has the right context. This architecture is much more resilient to complex, multi-hop questions.
Observability & Metrics
You cannot ship what you cannot measure. Use Prometheus metrics to track retrieval latency, reranker accuracy, and LLM token usage. Implement Ragas evaluation to continuously score your agent on faithfulness and answer relevance. Error handling must be explicit: if the vector store times out, the agent should gracefully degrade rather than crash. Setting up dashboards to monitor these observability metrics is crucial for maintaining a high-quality user experience.
Reducing Hallucinations with Verification
Hallucination mitigation is the primary goal of a rag ai agent. Even with perfect retrieval and reranking, LLMs can still hallucinate by misinterpreting the context or blending it with their pre-trained knowledge. You need post-generation verification. This involves checking the generated response against the retrieved context. If the agent cannot find evidence for a claim in the context, it should either discard the claim or trigger a re-retrieval loop. NVIDIA’s verification gate is a good example of a system that enforces these checks. Setting confidence thresholds ensures the agent abstains from answering when it is unsure, which is safer than guessing. This is especially important in regulated industries like healthcare and finance.
Scaling and Security Considerations
As your rag ai agent grows, scalability becomes a challenge. You need vector-store sharding to distribute the load across multiple nodes. For multi-tenant applications, implement data isolation by partitioning your vector store so one tenant cannot query another's data. Secure your API keys using a secrets manager and ensure all data in transit is encrypted. PostgreSQL with row-level security can be a robust backend for multi-tenant RAG, allowing you to enforce strict access controls at the database level. Regular security audits and penetration testing are also recommended for production-grade deployment.
Real-World Use Cases
Rag ai agents are transforming several industries. In legal document QA, they help lawyers find precedents without reading thousands of pages, providing citations for every claim. Customer-support assistants use them to provide accurate answers based on internal knowledge bases, reducing ticket resolution time and improving customer satisfaction. Multimodal retrieval allows e-commerce platforms to build product catalogs where users can search by text, image, or even audio, and the agent retrieves the most relevant items. These agents can also be integrated into voice applications, allowing users to ask questions naturally and receive spoken answers grounded in real-time data.
Quick-Start Checklist
- Define your chunking strategy and metadata schema.
- Choose a vector store (Qdrant, PostgreSQL) that fits your scale.
- Implement hybrid search (semantic + BM25) for robust retrieval.
- Select a reranker based on your latency budget and data sensitivity.
- Set up prompt templates with strict context injection rules.
- Configure observability metrics and Ragas evaluation.
- Implement post-generation verification for hallucination mitigation.
- Ensure multi-tenant data isolation and secure API keys.
- Test with real user queries to tune retrieval weights and reranker thresholds.
Definitions Glossary
Retrieval-Augmented Generation (RAG): A technique that combines an LLM with an external knowledge base to ground responses in factual data.
Vector Store: A database optimized for storing and querying high-dimensional vectors, enabling fast semantic search.
Hybrid Search: A retrieval strategy that combines semantic vector search with traditional keyword search (like BM25) to improve relevance.
Agentic RAG: An advanced RAG setup where the LLM-driven agent uses multi-step planning and query decomposition to handle complex tasks.
Hallucination Mitigation: Techniques used to prevent an LLM from generating false or unsupported information, often involving context verification.
Key Takeaways
- A rag ai agent grounds LLM responses in external data, drastically reducing hallucinations.
- Hybrid search and reranking are essential for high-precision retrieval.
- Graph-based orchestration enables complex, multi-step planning for agentic RAG.
- Production deployment requires robust observability, security, and data isolation.
- Post-generation verification is the final defense against inaccurate outputs.
Conclusion
Building a rag ai agent is the most effective way to create reliable, domain-specific AI applications. By combining a robust retrieval strategy, a precise reranker, and strict verification loops, you can deploy agents that users trust. Whether you are building a legal research tool or a customer support bot, the principles remain the same. If you are looking to integrate these agents into real-time audio or video applications, check out the VideoSDK AI Agents documentation to see how you can connect your RAG pipeline to live communication channels. What are you building with your rag ai agent? Drop a comment below.
FAQ