


Local TTS (local text-to-speech) is speech synthesis that runs entirely on your own hardware, with no cloud API, no API key, and no audio or text ever leaving your machine. Modern open-source engines like Kokoro-82M deliver near-human neural voices on a laptop CPU or Apple Silicon GPU in real time. This guide covers the engines, setup, integration patterns, and tuning you need to run private, offline speech generation in 2026.
The search volume around "local tts" tells a clear story. Developers want speech synthesis without a vendor bill, without rate limits, and without shipping user text to a third-party cloud. Privacy regulations, offline-first apps, and the arrival of small-but-excellent neural models have made that practical. A model like Kokoro-82M fits in a few hundred megabytes and runs faster than real time on a modern laptop. That changes the calculus entirely.
This article walks through what local TTS is, the technology underneath it, the strongest open-source engines available today, how to set one up, and how to wire it into real applications. If you have been waiting for on-device speech synthesis to feel production-ready, 2026 is the year to stop waiting.
What Is Local TTS and Why It Matters
Local TTS is defined as text-to-speech synthesis executed on the user's own device or server, where the neural model, the inference runtime, and the audio output all stay on that hardware. Local TTS works by loading a compact neural vocoder and acoustic model into memory, feeding text through the model at inference time, and rendering audio directly to a file or stream, with no network round trip involved.
The contrast with cloud TTS is stark. A cloud service like OpenAI TTS or ElevenLabs requires an API key, sends your text to someone else's servers, bills per character, and fails when your connection does. Local TTS inverts every one of those properties.
The key advantages are worth stating plainly:
- Privacy: sensitive text, whether medical notes, legal documents, or personal messages, never leaves the machine.
- Zero marginal cost: generate unlimited audio with no per-character billing.
- Offline reliability: works on a plane, in a secure facility, or in an air-gapped environment.
- Low latency: no network round trip means first audio bytes arrive in tens of milliseconds on tuned setups.
One common misconception deserves correction: people assume local TTS still sounds like the robotic espeak-era voices of the 2000s. It does not. Modern neural models produce natural prosody, and the best small models score competitively on listening tests against cloud services that cost money per request. The second misconception is that you need a beefy GPU. You do not. CPU-only inference is genuinely usable, and Apple Silicon's unified memory makes macOS laptops one of the best local TTS platforms available.
Core Technologies Behind Modern Local TTS
Modern local TTS is built on a short stack of well-understood components: a compact neural model, a portable inference runtime, and an audio output layer. Understanding this stack helps you pick the right engine and debug performance problems later.
The model layer is where quality lives. Kokoro-82M, an 82-million-parameter style-based TTS model released under Apache 2.0, became the reference point for small, high-quality local voices. Its size is the point: it is small enough to load in under a second and fast enough to exceed real-time factor on CPU, while producing voices that most listeners rate as natural. Other engines wrap different models, but the pattern of "small neural model, quantized weights, voice presets" is now the standard architecture.
The runtime layer is usually ONNX Runtime. Exporting a model to ONNX format decouples it from the original training framework, so the same weights run on macOS, Linux, Windows, and even in the browser via WebGPU or WASM. Execution providers let the runtime target Metal on Apple Silicon, CUDA on NVIDIA GPUs, or plain CPU cores, with automatic fallback when a GPU is unavailable.
The output layer handles formats and delivery. Most engines render WAV or raw PCM by default, with optional MP3 or Opus encoding, and increasingly support streaming output so playback can begin before the full file is generated.
The inference pipeline looks like this:
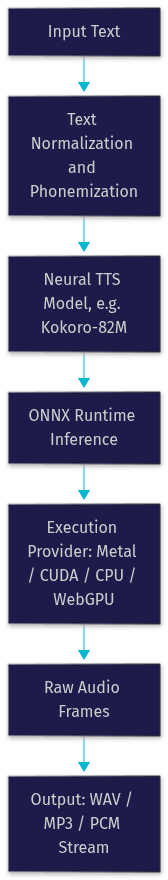
That vertical flow is the whole system. Every engine discussed below is a different packaging of these same stages, which is why skills transfer between them.
Popular Open-Source Local TTS Engines
The local TTS ecosystem matured fast, and a handful of projects now cover the main deployment surfaces: command line, self-hosted API, and browser. Here are the engines worth your time in 2026.
Kokoro-tts-tool (CLI for Apple Silicon)
Kokoro-tts-tool is a command-line utility optimized for macOS Apple Silicon machines. It wraps the Kokoro model with Metal acceleration, so an M-series MacBook generates audio faster than real time with the fan barely spinning. Its strengths are simplicity and speed: point it at a text file, pick a voice preset, and get a WAV back. It is best for batch processing, podcast prep work, and anyone who lives in the terminal on a Mac. Its limitation is platform focus; Linux and Windows users should look at the server-based options below.
Pocket-TTS OpenAPI Server
Pocket-TTS packages a local TTS engine behind an OpenAPI-compatible HTTP interface. That means any application that can make a web request can use it, and auto-generated client libraries work out of the box. Its strengths are a clean REST surface, voice and language query endpoints, and Docker packaging that deploys anywhere. It is best for teams that want a private, self-hosted drop-in replacement for a cloud TTS API without rewriting their integration layer.
ttsd Self-Hosted Multi-Model API
ttsd takes the server idea further by supporting multiple TTS models behind one daemon. You can route requests to different models depending on language, quality, or speed requirements, all from a single local endpoint. Its strengths are model flexibility and a health-check endpoint that makes it easy to monitor in a service mesh. It is best for self-hosters running on a home server or small VPS who want one TTS service to serve several projects.
LocalVoice Studio (Browser-Only)
LocalVoice Studio runs entirely in the browser, loading the model via WebGPU with a WASM fallback. Nothing is installed, nothing is served, and text never leaves the tab. Its strengths are zero-install deployment and genuinely private operation, making it ideal for sharing a TTS tool with non-technical users via a static page. The trade-off is performance: WebGPU inference is fast on supported browsers but slower and more memory-constrained than native runtimes.
Kokoro TTS Browser Add-On
The Kokoro browser add-on brings local TTS directly into your browsing workflow, synthesizing selected text or full pages on demand using an on-device model. It is best for accessibility use cases, hands-free reading of articles, and users who want speech without copy-pasting into another tool. Because inference happens locally, it works offline once the model is cached.
A quick comparison of where each fits:
| Engine | Platform | Best For | Output |
|---|---|---|---|
| Kokoro-tts-tool | macOS CLI | Batch audio on Apple Silicon | WAV files |
| Pocket-TTS | Docker / any OS | API-compatible self-hosting | WAV, MP3, PCM |
| ttsd | Linux server | Multi-model TTS service | Streamed audio |
| LocalVoice Studio | Browser (WebGPU) | Zero-install private use | In-tab playback |
| Kokoro add-on | Browser extension | Reading pages aloud | In-tab playback |
The most important row for most developers is Pocket-TTS: if you are replacing a cloud API, an OpenAPI-compatible local server is the lowest-friction path.
Setting Up a Local TTS Engine
Setup for local TTS follows the same pattern regardless of engine: install the package, download the model weights, verify the service is healthy, then configure voices. The details differ by platform, so this walkthrough covers the decision points.
Step 1: Check your prerequisites. You need a supported Python runtime for most native engines, or Docker for the server-based options, or just a modern browser for the WebGPU tools. Confirm you have a few gigabytes of free disk space for model weights and a working audio output path. On macOS, verify that your machine is Apple Silicon if you want Metal acceleration; Intel Macs fall back to CPU, which still works but slower.
Step 2: Choose an installation method. Native engines install through standard Python package managers, and the newer uv tool resolves dependencies dramatically faster than traditional pip. Server engines are best installed via Docker, which bundles the runtime and model in one image and avoids dependency conflicts entirely. Browser tools need no installation at all.
Step 3: Download the model. Most engines fetch model weights on first run, pulling the ONNX files and voice embeddings from their release hosting. Expect a download in the hundreds of megabytes for a full multi-language voice set, or smaller if you select a single language. If you work in an air-gapped environment, download the weights on a connected machine and transfer them manually into the engine's model directory.
Step 4: Run the first synthesis. Generate a short test sentence and confirm audio plays back correctly. This validates the entire pipeline, from text normalization through inference to output encoding, in one shot.
The workflow maps cleanly to a flowchart:
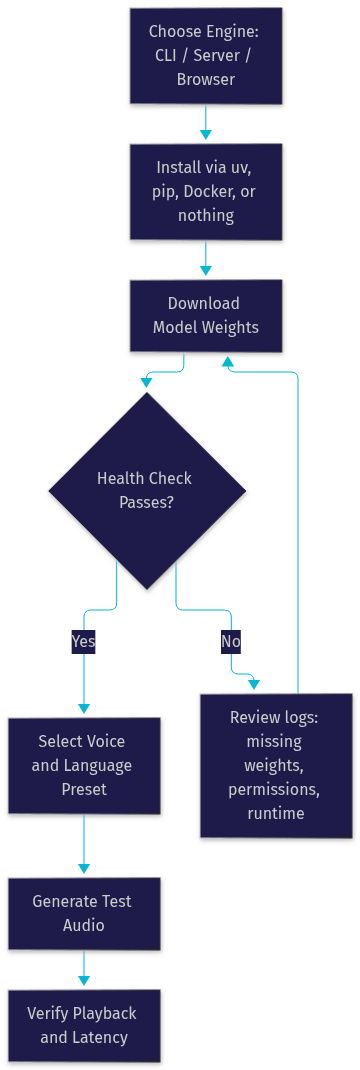
Platform differences worth knowing: on Apple Silicon, prefer engines that expose Metal as an execution provider, since GPU inference is often three to five times faster than CPU on the same machine. On Linux servers without a GPU, CPU inference is entirely viable for batch workloads, and you can run multiple worker processes in parallel to scale throughput. On Windows, the ONNX Runtime handles the DirectML provider, and Docker Desktop works for the server engines.
Verifying Model Download and Health Check
Every server-based engine exposes a health endpoint that confirms the service is running and the model is loaded. Querying it should return a status response indicating readiness, the loaded model name, and often the available voice count. For CLI tools, running the version flag confirms the binary is installed and typically reports the bundled model version. If the health check fails, the log output almost always names the culprit: missing weights, a blocked download, or an incompatible runtime version. Fix the named issue and re-check before moving on to voice configuration.
Configuring Voices and Languages
Local engines ship with voice presets, each a named persona with a defined language, gender, and speaking style. Listing available voices is a standard operation on every engine, whether through a CLI flag or an API endpoint, and the response includes the voice identifier plus its language tag. Filter the list by language code to find voices for your target locale, then pass the voice identifier when generating audio. Multi-language support varies: Kokoro-based engines cover a solid set of languages including English, Japanese, Mandarin, Spanish, and French, while other models specialize. If your application needs voice cloning for a personalized assistant, check whether your chosen engine supports custom voice embeddings, and remember that cloned voices carry their own consent and licensing obligations.
Using Local TTS in Real-World Applications
Integration is where local TTS earns its keep. Four patterns cover most production usage.
Command-line batch processing for podcasts. A CLI engine becomes a pipeline stage: read a script file, synthesize each segment with a chosen voice, and write numbered audio files ready for editing or concatenation. Because there is no API cost, iterating on script wording and re-rendering entire episodes is free, which changes how aggressively you can polish narration. Batch runs also benefit from parallelism: on a multi-core machine, running several synthesis processes concurrently can saturate CPU throughput.
HTTP API calls from web services. A self-hosted server like Pocket-TTS or ttsd slots directly into an existing backend. Your application makes the same style of request it would make to a cloud provider, but pointed at localhost or an internal host. This is the pattern for replacing a paid API in an existing codebase with minimal changes, and the OpenAPI surface means client libraries generate automatically.
Web-worker based browser apps for e-learning. For fully client-side applications, running synthesis inside a web worker keeps the main thread responsive while the model renders audio. An e-learning platform can vocalize quiz questions and feedback entirely on the learner's device, which matters enormously for children's apps where sending content to third parties is a compliance problem. WebGPU acceleration makes this practical on modern browsers, with WASM as the fallback.
Voice cloning for personalized assistants. Engines that support custom voice embeddings let an assistant speak in a consistent, branded, or familiar voice. The pipeline runs locally, so the reference audio and the generated speech both stay on-device. Always secure explicit consent for any voice you clone, and check the license of both the engine and the model before commercial use.
One architectural decision cuts across all four patterns: streaming versus full-file generation. Full-file generation is simpler and fine for batch work. Streaming starts playback before synthesis completes, which reduces perceived latency dramatically for interactive applications. For a voice assistant or a reading tool, streaming is the difference between a response that feels instant and one that feels sluggish. Measure your real-time factor, the ratio of synthesis time to audio duration, and aim for a value below one so generation outpaces playback.
Performance Tuning and Optimization
Local TTS performance is tunable, and the biggest wins come in a specific order.
First, enable GPU acceleration. On Apple Silicon, confirm the engine uses the Metal execution provider rather than falling back to CPU. On NVIDIA hardware, the CUDA provider delivers the largest speedup available. On the browser, WebGPU beats WASM by a wide margin where supported. Getting inference onto the right execution provider is worth more than every other tweak combined.
Second, adjust generation parameters. Speed controls let you render speech faster or slower without re-synthesis cost, and some engines expose sampling parameters that trade slight naturalness for faster inference. For long-form content, use infinite or chunked streaming modes that split text into sentences and synthesize continuously, so a two-hour document never waits on a single monolithic render.
Third, profile. Most engines log per-request synthesis time and audio duration, which gives you the real-time factor directly. A factor of 0.5 means you generate audio twice as fast as it plays, which is comfortable headroom for interactive use. If your factor creeps above one on CPU, either move to GPU, reduce concurrency, or accept batch-only operation.
A practical tuning sequence: verify the execution provider in the health output, benchmark a representative paragraph, adjust speed and streaming settings, then re-benchmark. In practice, teams deploying local TTS on Apple Silicon consistently report real-time factors well under 0.5 for Kokoro-class models, which is why laptops have become legitimate TTS servers for personal and small-team workloads.
Security, Privacy, and Licensing Considerations
Running TTS locally removes an entire class of privacy risk, but it does not remove your responsibility for the remaining pieces.
On licensing, know the difference between the engine license and the model license. Kokoro-82M ships under Apache 2.0, which permits commercial use, but other models carry non-commercial or attribution requirements. Check both before shipping a product. Engine licenses are typically MIT or Apache 2.0, and the well-maintained projects publish their license terms prominently in the repository.
On supply-chain security, prefer projects that run automated security scans. Several of the engines highlighted here integrate bandit and pip-audit into their continuous integration, catching vulnerable dependencies and unsafe code patterns before release. Reviewing a project's scan status before adopting it is a five-minute check that saves real pain.
On data handling, the core promise of local TTS is that text and audio stay on your machine. Preserve that property in your architecture: if you wrap a local engine in a network-facing API, bind it to localhost or an internal network, add authentication if it is reachable by others, and never log the text you synthesize. A self-hosted TTS server that logs every request has quietly recreated the privacy problem you were avoiding.
Definitions Glossary
Local TTS: Text-to-speech synthesis that runs entirely on the user's own hardware, with the model, inference, and audio output all staying on-device and no cloud API involved.
Kokoro-82M: An 82-million-parameter open-source neural TTS model released under Apache 2.0, known for natural voices and real-time CPU inference on modern hardware.
ONNX Runtime: A cross-platform inference engine that executes exported neural models, selecting hardware backends such as Metal, CUDA, or CPU through configurable execution providers.
Real-Time Factor: The ratio of synthesis time to audio duration; a value below one means speech is generated faster than it plays back.
Execution Provider: The pluggable backend within ONNX Runtime that targets specific hardware, such as Metal on Apple Silicon, CUDA on NVIDIA GPUs, or WebGPU in browsers.
Voice Preset: A named, pre-built voice persona with a defined language, gender, and speaking style that can be selected at synthesis time.
Key Takeaways
- Local TTS runs speech synthesis entirely on your own hardware, delivering privacy, zero marginal cost, offline reliability, and low latency in one package.
- Modern small neural models like Kokoro-82M produce natural speech at real-time or faster speeds on laptops, ending the era of robotic local voices.
- The engine landscape covers every deployment surface: CLI tools for Apple Silicon, OpenAPI-compatible servers for self-hosting, and WebGPU browser tools for zero-install use.
- Streaming generation and GPU execution providers are the two highest-impact performance levers, and both are usually configuration changes rather than engineering projects.
- Verify both engine and model licenses before commercial use, and keep your self-hosted server bound to localhost to preserve the privacy that motivated local TTS in the first place.
Conclusion
Local TTS has crossed the threshold from hobbyist curiosity to practical infrastructure. The models are small and excellent, the runtimes are portable across macOS, Linux, Windows, and the browser, and the tooling around them, from CLI batch processors to OpenAPI-compatible servers, covers real production patterns. Whether you are building a podcast pipeline, an e-learning reader, or a private voice assistant, there is an engine in this guide that fits your surface. Start with one, benchmark it on your own hardware, and iterate from there. If your project later needs interactive voice with full calling and streaming infrastructure, VideoSDK's AI agent capabilities can sit alongside your local synthesis work. What are you building with local TTS? Drop a comment, I'd love to hear what kind of on-device speech use case you're working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ